A SARGability Riddle In SQL Server: Why Do Some Queries Seek and Some Queries Scan?

Use The Force


I had a RABID FAN ask me an interesting question about a query. I can’t use theirs, but I can repro the question.

The question was: if using ISNULL in a where clause isn’t SARGable, how come I can use a FORCESEEK hint in this query?

Formatting and linking my own, of course.

The query looked something like this:

SELECT
    c = 
        COUNT_BIG(*)
FROM dbo.Users AS u WITH(FORCESEEK)
WHERE ISNULL(u.Id, 0) = 22656;
GO
SQL Server Query Plan
seekable!

What Gives?


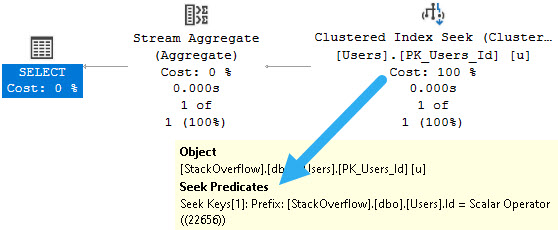
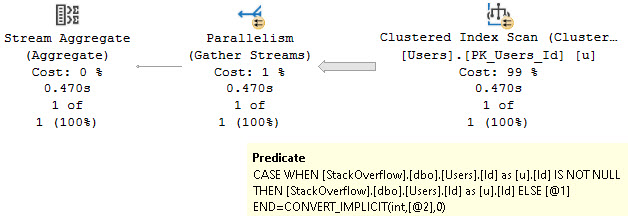
The first thing you should notice is that the optimizer throws out ISNULL, here.

Why? Because the Id column isn’t NULL-able, and since ISNULL is Microsoft’s special non-ANSI baby, it can do this one special thing.

If we use COALESCE instead, we’ll get an error.

SELECT
    c = 
        COUNT_BIG(*)
FROM dbo.Users AS u WITH(FORCESEEK)
WHERE COALESCE(u.Id, 0) = 22656;
GO

Msg 8622, Level 16, State 1, Line 8
Query processor could not produce a query plan because of the hints defined in this query. Resubmit the query without specifying any hints and without using SET FORCEPLAN.

And if we try to use ISNULL on a NULL-able column like Age, we’ll get the same error:

SELECT
    c = 
        COUNT_BIG(*)
FROM dbo.Users AS u WITH(FORCESEEK)
WHERE ISNULL(u.Age, 0) = 22656;
GO

Coacase? Caselesce?


Under the covers, COALESCE is just a crappy band CASE expression.

Without the FORCESEEK hint, we can get the query to actually run.

SELECT
    c = 
        COUNT_BIG(*)
FROM dbo.Users AS u
WHERE COALESCE(u.Id, 0) = 22656;
GO 
SQL Server Query Plan
southa

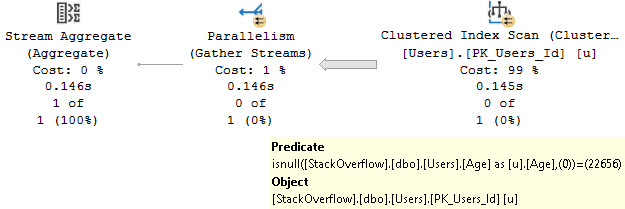
And ISNULL is just… ISNULL.

SELECT
    c = 
        COUNT_BIG(*)
FROM dbo.Users AS u
WHERE ISNULL(u.Age, 0) = 22656;
GO
SQL Server Query Plan
ribs

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Darling Data Is An ECIF Enabled Supplier!

Other People’s Money


Microsoft loves getting people into their Azure services. They love it so much that they’re willing to pay for partners to help customers get them up there in the cloudy stuffs.

2021 10 16 12 12 49
they just don’t love it enough to spell check their copy

I mean, unless they’re making Azure Consumee. Michelin Star, I’m sure.

If you’re looking to move your current database to Azure, but you’re not sure:

  • Which offering to choose
  • Which machine size you’ll need
  • If your current workload can be tuned to reduce machine size
  • Which services your code is compatible with

That’s the kind of stuff I can help with as part of your migration efforts. If you’d like to find out more, you can get in touch with me here.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
When Query Spills Cause tempdb Contention And Performance Issues In SQL Server

Temptables


I was helping a client troubleshoot a scalability issue recently, where during one point in their workload tempdb went out of control.

What was puzzling them was that nothing in the stored procedure did anything with temporary objects, cursors, or any of the other obvious things that go to el baño público. And the query plan itself was a pretty simple little loopy thing.

It wasn’t until I grabbed a quick sample of actual execution plans with Extended Events that the problem became more obvious.

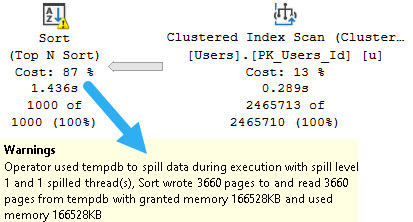
Despite the fact that the query was only passing around 7 rows, we were getting a one row estimate, and there was a spilling Sort operator.

Chance Of Cloudballs


There were a couple compounding issues here, of course, like that their database is hosted in the cloud.

It doesn’t matter which cloud you talk about, this is a problem they all have and I see people face constantly.

I/O sucks, up there.

It was a lot harder to get this to repro on my local hardware, because I have very nice drives.

Let’s take a look!

Bleak


If I run this query, it’ll spill a little bit. I have the MAXDOP 1 hint on there to artificially slow it down. Without that, the fast query and I/O make the contention harder to hit.

SELECT TOP (1000) 
    u.Id 
FROM dbo.Users AS u
ORDER BY u.Reputation
OPTION(MAXDOP 1);
SQL Server Query Plan
just like me

I stuck it in a stored procedure to make calling it from ostress a little bit easier.

No Return


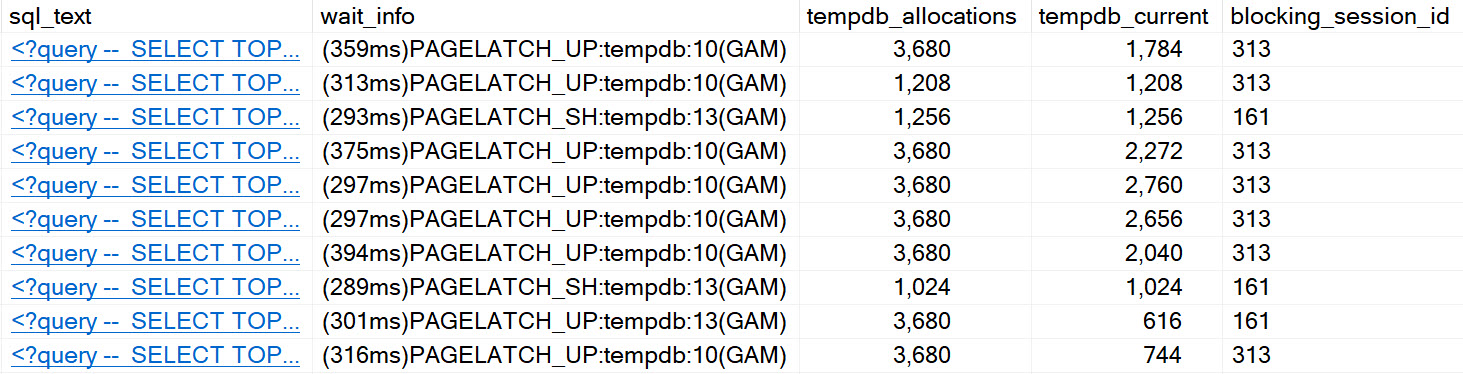
After running for a bit, eventually we hit GAM contention:

SQL Server tempdb Contention
tuesday

We can see all the classic signs of tempdb contention, arising from spills.

It’s worth noting that enabling in-memory tempdb seems to alleviate this issue for the most part. I’d show you a picture of that, but it’s not worth 1000 words.

Fixing The Spill


Normally, I wouldn’t bother fixing a spill of that size, but in this case it was worthwhile because it was harming concurrency.

The quick fix was to add a MIN_GRANT_PERCENT hint. The long-term fix is to add an index to support the Sort operation.

Good ol’ indexes, putting data in order.

There are many reasons why a spill may occur. Poor estimates are quite common, but the reason for that poor estimate has about a billion potential root causes.

Even if your query gets enough memory, sometimes you may still see spills because certain operators had to share memory.

It’s a wild world.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.

SQL Server Features I Still Need To Talk People Into Using

Booze Schmooze


As a counterpart to yesterday’s post, I have a list of Great Ideas™ that sometimes it’s hard to get people on board with, for some reason.

Don’t get me wrong, some people can’t jump on this stuff fast enough — I’ve had people take “unscheduled maintenance” during engagements to flip the right switches — but other times there’s a hem and a haw and a whole lot of’em to go along with the plan.

Somehow people who have auto close and Priority Boost turned on and haven’t checked for corruption since 30 Rock went off the air want a full-bore fisking of every change and every assurance that no edge case exists that could ever cross their path.

Okay pal. You go on with your bad 2012 RTM self.

Lock Pages In Memory


“Please don’t pop my balloon animals.”

To say that this setting only lets SQL Server hang onto memory is a grand injustice. It also lets SQL Server use completely different APIs to access memory through Windows, including skipping over virtual memory space. That can be an awesome benefit for servers with gobs of memory.

What are people worried about, here? Usually some article they read about balloon drivers in 2011, or something.

But the same people aren’t afraid to set min server memory to max server memory, and then wonder why they have no plan cache.

I love this setting though, and if you can also get away with turning on trace flag 834, there are some nice additional benefits.

DBCC CHECKDB


“Well, our index maintenance job runs for 9 hours, so we don’t have time for this. Besides, won’t it cause a lot of blocking?”

Lord have mercy, the foot dragging on this. Part of your job as a DBA is to keep data safe and backed up. Running CHECKDB is part of that.

No DBA got fired over fragmented indexes. More than a few have for data going corrupt.

Granted, this can get a little more complicated for really big databases. Some people break it up into different steps, and other people offload the process.

Some third party backup tools from vendors like Quest and Red Gate allow you to automate processes like that, too. Full backup, restore to new server, run CHECKDB, tell us what happened.

How nice, you get a tested restore, too.

Query Store


“Won’t this catch my server on fire and leak PII to hackers?”

If you’re too cheap to spring for a proper monitoring tool, Query Store makes a pretty okay pseudo replacement. Especially in 2017 and up where you can track wait stats too, you can get some pretty good insights out of it.

Microsoft has also gotten pretty smart about better default settings for this thing, and in 2019 you have more knobs to set smarter standards for which plans get tracked in there.

It’d be really nice if you could choose to ignore queries, too, but you know. Can’t always get what you want, there.

I’d much rather look at Query Store than that unreliable old plan cache, too.

Read Committed Snapshot Isolation


“Why do I want tempdb to be full of old data?”

Remember yesterday? Me either. Nothing good happened, anyway. Do you remember what that row looked like before the update started? No?

Read Committed Snapshot Isolation does. And it wants you to, too. This setting solves so many dumb problems that people run headlong into because Microsoft committed to a garbage isolation level.

One complaint I hear all the time is that a particular application runs a lot better on Oracle with no other changes. This setting is usually the reason why: It’s not turned on.

Once you turn it on, reader/writer blocking and deadlocking goes away, and you don’t need to add a SSMS keyboard shortcut that inserts WITH NOLOCK.

Changing Indexes


“They’re fine the way they are, trust me. That burning smell is another server.”

Index tuning needs to be a process that starts with cleaning up indexes, and ends with adding in better ones.

What makes an index bad? When it’s unused, and/or duplicative.

What makes an index good? When it gets read from more than it’s written to, and it’s a usefully different way for queries to access data.

There are other index anti-patterns that are good to look for too, like lots of single key column indexes, but they usually get cleaned up when you start merging duplicates.

There’s a near fully eclipsed Venn Diagram of people who are worried about having too many indexes and people who have never dropped an index in their career.

Talk, Talk


These are the kinds of changes and processes people should be comfortable with making when they work with SQL Server.

Sure, there are a ton of others, but some of them have become part of the installer and get a little more leeway — parallelism settings, instant file initialization, tempdb etc. — I only wish that more of this stuff would follow suit.

One wonders quite loudly why setting MAXDOP made it into the installer, but setting Cost Threshold For Parallelism did not.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
SQL Server Features I Still Need To Talk People Out Of

We Rust


Consulting gives you a lot of opportunities to talk to a lot of people and deal with interesting issues.

Recently it occurred to me that a lot of people seem to confer magic button status to a lot of things that always seem to be If-I-Could-Only-Do-This features that would solve all their problems, and similarly a Thing-That-Solved-One-Problem-Once turned into something that got used everywhere.

Go figure, right?

Let’s talk about some of them, so maybe I won’t have to talk this over with you someday, dear reader.

Partitioning


How this ended up being everyone’s top unexplored performance feature is beyond me. I always seem to hear that someone really wants to partition dbo.tblSomeBigTable because queries would be faster if they could eliminate partitions.

Maybe if you’re using clustered column store indexes it would, but for the rest of us, you’re no better off with a partitioned table than you are with a table that has decent indexing. In a lot of cases, partitioning can make things worse, or just more confusing.

Few people seem to consider the amount of work that goes into partitioning a really big table, either. It doesn’t matter if you want to do it in place, or use a batch process to copy data over.

Even fewer people talk about Partitioning for what it’s good for, which is managing partitions. Just make sure all those indexes are aligned.

Fill Factor


At this point, I’d expect everyone to understand why Flash and SSD storage is better than old spinning disks. Lack of  moving parts, less pushing random I/O patterns, etc.

And yet, without a single page split being measured or compared, fill factor gets dropped down to 80 (or lower) just in case.

I call this Spinning Disk Mentality, and it hurts to see it out in the wild, especially when:

  • You’re on Standard Edition
  • You already have way more data than memory
  • You’re intentionally making data less compact
  • Your entire workload is stalled out on PAGEIOLATCH_XX waits

I truly appreciate the problem that lowering fill factor used to solve, but let’s join the CURRENT_CENTURY on this one.

Unless you have a good reason to add physical fragmentation to your indexes, how about we skip that?

In-Memory OLTP (Hekaton)


This is a hugely misunderstood feature. Everyone thinks it’s gonna make queries faster because tables will be in memory without reading the fine print.

  • If you have problems with throughput on very hot data, this might be a good solution for you.
  • If you’ve got a bunch of run-0f-the-mill queries that get blocked sometimes and performance generally stinks on, this isn’t really what you need to focus on.

I think the most common useful pattern I’ve seen for this feature is for “shock absorber” tables, where things like event betting, ticket sales, and online ordering all need to happen very quickly for a very small amount of data, and after the initial rush can be shuffled to regular disk-based tables.

If your table is already cached in memory when queries are hitting it, using this feature isn’t gonna make it any more in memory.

You’ve got other problems to solve.

Dirty Reads


Getting blocked sucks. It doesn’t matter if it’s in a database, at a bar, in traffic, or an artery. Everyone wants their reads instantly and they don’t wanna hear a darn word about it.

I’m not here to trample all over NOLOCK — I’ve defended people using it in the past — but I am here to ask you nicely to please reconsider dousing all your queries with it.

In many cases, READPAST  is a better option, so your query can skip over locked rows rather than read a bunch of in-flight changes. This can be the wrong choice too, but it’s worth considering. It can be especially useful for modification queries that are just out looking for some work to do.

We’ll talk about my favorite option in tomorrow’s post.

Recompiling All The Things


Look, you wanna recompile a report or something, fine. I do, too. I love doing it, because then I don’t have one less random issue to think about.

Weirdly sniffed parameter? No mas, mon ami.

Magick.

Especially in cases where bigger code changes are hard/impossible, this can be sensible, like dealing with a million local variables.

Just be really careful using it everywhere, especially in code that executes a ton. You don’t wanna spend all your time constantly coming up with query plans any more than you wanna get parameter sniffed.

Plus, since Query Store captures plans with recompile hints, you can still keep track of performance over time. This can be a great way to figure out a parameter sniffing problem, too.

Gotcha


Basic understanding often is often just camouflage for complete confusion. Often, once you dig past the documentation marketing materials, you’ll find every feature has a whole lot of drawbacks, trade-offs, blind spots, and interoperability issues.

Databases being databases, often just getting your schema to a state where you can test new features is a heroic feat.

No wonder so many millions of hours have been spent trying to replace them.

Thanks for reading!

You Probably Don’t Need To Offload SQL Server Reads To Another Server

Moneybags


Duplicating data for reporting, outside of moving it to a data warehouse where there’s some transformations involved, can be an expensive and perilous task.

Your options come down to a native solution like AGs, Replication, or Log Shipping. You can brew something up yourself that relies on native stuff too, like Change Data Capture, Change Tracking, Temporal Tables, or triggers.

Outside of that, you’re getting into the world of SSIS/ADF, other third party vendors, etc. to get data where it ought to go. That’s none of my business, and good luck to you.

As soon as you let people read that data, you have to fully license the SQL Server that it’s sitting on.

Alt Rock


I’ve talked to a few dozen people about this over the years, too. Most were shocked to learn about the licensing implications, thinking that having Software Assurance from Microsoft covered their needs.

The most frequent desire for offloading reads is real-time reporting, and the most frequently cited reason is that reporting queries put too much load on the current server hardware.

You can see where the conflict sits, here. People think they’re getting a free SQL Server to report off of, so they don’t need to up their current hardware and pay for it. Microsoft may be dumb, but it ain’t that dumb.

Once you get people past the licensing issues, tuning the current hardware becomes a more approachable subject.

Gestalt Block


Of course, the idea of tuning the reporting queries has occurred to most people, but the attempts at tuning are usually flailing attempts to solve problems that aren’t there.

  • Maybe this local variable will do a thing for parameter sniffing
  • NOLOCK is better for reports, anyway
  • Don’t forget to recompile, too
  • Add a DISTINCT, there’s too many rows
  • Throw up hands, rebuild indexes

While everything has its place, it’s rare that this combination will get you past all of your performance issues. Reporting queries are especially interesting to me, because of how few people embrace batch mode to any degree for them.

The cost of tuning queries is far cheaper than the cost of licensing a whole other server, especially for Enterprise Edition customers. If you’re on Standard Edition, you have many other problems. Many, many other problems, standing in the way of scaling and performance issues.

If this is the kind of thing you need help with, drop me a line. This is exactly the kind of thing I do.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
An Annoying OPTIMIZE FOR Limitation In SQL Server

Infrequent


I have occasionally cheated a little and used OPTIMIZE FOR some_value to fix a parameter sniffing issue that didn’t have any other viable options available to it.

This is a pretty rare situation, but there’s a place for everything. Keep in mind that I’m not talking about UNKNOWN here. I’m talking about a real value.

Recently I had to fix a specific problem where cardinality estimates for datetime values would get completely screwed up if they were older than a day.

You’d be tempted to call this an ascending key problem, but it was really an ascending key solution. Whenever a query got an off histogram estimate, it chose a good plan — when it got a histogram step hit, the estimate was high by several million rows, and the plan looked like someone asked for all the rows in all the databases in all the world.

So, you go through the usual troubleshooting steps:

  • More frequent stats updates: uh oh, lots of recompiles
  • Stats updates with fullscan during maintenance: crapped out during the day
  • Various trace flags and acts of God: Had the opposite effect
  • Is my query doing anything dumb? Nope.
  • Are my indexes eating crayons? Nope.

Drawing Board


The problem with OPTIMIZE FOR is that… it’s picky. You can’t just optimize for anything.

For example, you can’t do this:

DECLARE 
    @s datetime = '19000101'''

SELECT 
    c = COUNT_BIG(*)
FROM dbo.Users AS u
WHERE u.CreationDate >= @s
OPTION
(
    OPTIMIZE FOR (@s = GETDATE())
);

And you can’t do this:

DECLARE 
    @s datetime = '19000101',
    @d datetime = GETDATE()

SELECT 
    c = COUNT_BIG(*)
FROM dbo.Users AS u
WHERE u.CreationDate >= @s
OPTION
(
    OPTIMIZE FOR (@s = @d)
);

We get a nasty message.

Msg 320, Level 15, State 1, Line 26
The compile-time variable value for ‘@s’ in the OPTIMIZE FOR clause must be a literal.

Ever Heard Of A Chef Who Can’t Cook?


The solution is, as usual, dynamic SQL, but there’s a catch. Because there’s always a catch.

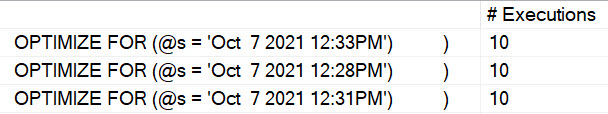
For example this works, but if you run it a minute or so apart, you get multiple plans in the cache.

DBCC FREEPROCCACHE;

DECLARE
    @sql nvarchar(MAX) = N'',
    @s datetime = '19000101',
    @d datetime = GETDATE(),
    @i int = 0;

WHILE @i < 10
BEGIN
    
    SELECT
       @sql = N'
        SELECT 
            c = COUNT_BIG(*)
        FROM dbo.Users AS u
        WHERE u.CreationDate >= @s
        OPTION
        (
            OPTIMIZE FOR (@s = ''' + CONVERT(nvarchar(30), @d) + ''')
        );     
       ';
    
    EXEC sys.sp_executesql
        @sql,
        N'@s datetime',
        @s;
    
    SELECT 
        @i += 1;
    
END

EXEC sp_BlitzCache 
    @DatabaseName = 'StackOverflow';
2021 10 07 12 34 40
dangit

Are You Ready For Some Date Math?


Depending on how we want to address this, we can either:

  • Do some date math to go to the beginning of the current day
  • Do some date math to go to the end of the current day
  • Set the value to the furthest possible date in the future

The first two cases should generally be fine. Saying the quiet part out loud, not a lot of plans survive a long time, either due to plan cache instability or other recompilation events, like from stats updates.

If you’re super-picky about that, go with the third option. This may also be considered the safest option because a stats update might give you a histogram for today’s value. The datetime max value will theoretically “never” be a histogram step value, but that depends on if you let users do Stupid Things™

DBCC FREEPROCCACHE;

DECLARE
    @sql nvarchar(MAX) = N'',
    @s datetime = '19000101',
    @d datetime = '99991231',
    @i int = 0;

WHILE @i < 10
BEGIN
    
    SELECT
       @sql = N'
        SELECT 
            c = COUNT_BIG(*)
        FROM dbo.Users AS u
        WHERE u.CreationDate >= @s
        OPTION
        (
            OPTIMIZE FOR (@s = ''' + CONVERT(nvarchar(30), @d) + ''')
        );     
       ';
    
    EXEC sys.sp_executesql
        @sql,
        N'@s datetime',
        @s;
    
    SELECT 
        @i += 1;
    
END

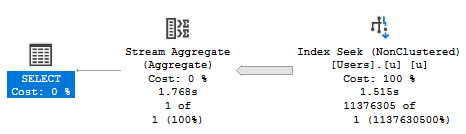
No matter how many times you run this, the plan will get reused and you’ll always have the off-histogram step.

Qualifying Events?


This is one of those “good ideas” I have for a specific circumstance without any other easy workarounds. I don’t suggest it as a general practice, and it certainly has some drawbacks that would make it dangerous in other circumstances.

I can’t easily reproduce the problem this solved locally, but I can show you why you probably don’t want to make it a habit.

SQL Server Query Plan
eek

In cases where you are able to get good cardinality estimates, this will hamper it greatly.

So, you know, last resort.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Be Careful Where You Call Inline Table Valued Functions In SQL Server Queries

Keep’em Comin!


While helping someone tame a bunch of rather unfortunate scalar valued functions, we eventually hit a point where they were able to do some of the rewrites themselves. During testing, they ran into a situation where performance got worse when they made the switch over, and it wasn’t because an Eager Index Spool popped up.

I was able to come up with a demo that shows a reasonable enough performance difference in a couple queries using the same technique as I gave them to fix things.

So uh, here goes that.

Muppet


The query they were tuning had a couple OUTER APPLYs already written into it, and so they added the function on as another.

SELECT
    u.DisplayName,
    b.Name,
    nbi.AvgPostsPerDay
FROM dbo.Users AS u
OUTER APPLY
(
    SELECT 
        CreationDate = 
            MIN(p.CreationDate)
    FROM dbo.Posts AS p
    JOIN dbo.Votes AS v
        ON  v.PostId = p.Id
        AND v.VoteTypeId = 1
    WHERE p.OwnerUserId = u.Id
) AS p
OUTER APPLY
(
    SELECT TOP (1)
        b.Name
    FROM dbo.Badges AS b
    WHERE b.UserId = u.Id
    ORDER BY b.Date DESC
) AS b
OUTER APPLY dbo.no_bueno_inline(u.Id, p.CreationDate) AS nbi
WHERE u.Reputation >= 100000
ORDER BY u.Reputation DESC;

Since they didn’t want to lose rows to the function, they couldn’t use CROSS APPLY. Good enough.

Moutarde


But what they really wanted was to move the function up into the select list, like this:

SELECT
    u.DisplayName,
    b.Name,
    AvgPostsPerDay = 
    (
        SELECT 
            nbi.AvgPostsPerDay 
        FROM dbo.no_bueno_inline
        (
            u.Id, 
            p.CreationDate
        ) AS nbi
    )
FROM dbo.Users AS u
OUTER APPLY
(
    SELECT 
        CreationDate = 
            MIN(p.CreationDate)
    FROM dbo.Posts AS p
    JOIN dbo.Votes AS v
        ON  v.PostId = p.Id
        AND v.VoteTypeId = 1
    WHERE p.OwnerUserId = u.Id
) AS p
OUTER APPLY
(
    SELECT TOP (1)
        b.Name
    FROM dbo.Badges AS b
    WHERE b.UserId = u.Id
    ORDER BY b.Date DESC
) AS b
WHERE u.Reputation >= 100000
ORDER BY u.Reputation DESC;

That way you don’t lose any rows like you could with CROSS APPLY, and the optimizer is more likely to holler at the function later on in the query plan, since the values from it are only being projected — that’s fancy for selected.

Mapperoo


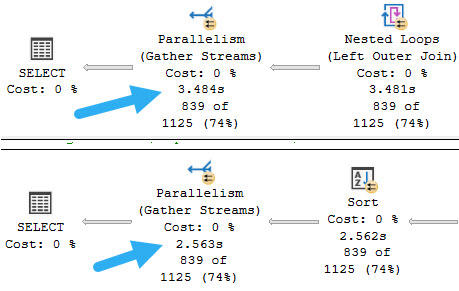
The full query plan is a bit much to untangle quickly in this post, but the timing difference is noticeable enough for my purposes:

SQL Server Query Plan
tootin

So if you ever end up rewriting a scalar valued function as an inline table valued function, make sure you test calling it in the same way. Moving query syntax around may produce logically equivalent results, but won’t always produce equivalent performance.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
How OPTIMIZE FOR UNKNOWN Makes Troubleshooting SQL Server Performance Problems Harder

Detained


Despite the many metric tons of blog posts warning people about this stuff, I still see many local variables and optimize for unknown hints. As a solution to parameter sniffing, it’s probably the best choice 1/1000th of the time. I still end up having to fix the other 999/1000 times, though.

In this post, I want to show you how using either optimize for unknown or local variables makes my job — and the job of anyone trying to fix this stuff — harder than it should be.

Passenger


Like most things, we’re going to start with an index:

CREATE INDEX r ON dbo.Users(Reputation);
GO 

I’m going to  have a stored procedure that uses three different ways to pass a value to a where clause:

CREATE OR ALTER PROCEDURE 
    dbo.u 
(
    @r int, 
    @u int
)
AS
BEGIN

    /* Regular parameter */
    SELECT
        c = COUNT_BIG(*)
    FROM dbo.Users AS u
    WHERE u.Reputation = @r
    AND   u.UpVotes = @u;

    /* Someone who saw someone else do it at their last job */
    DECLARE 
        @LookMom int = @r,
        @IDidItAgain int = @u;
    
    SELECT
        c = COUNT_BIG(*)
    FROM dbo.Users AS u
    WHERE u.Reputation = @LookMom
    AND   u.UpVotes = @IDidItAgain;

    /* Someone who read the blog post URL wrong */
    SELECT
        c = COUNT_BIG(*)
    FROM dbo.Users AS u
    WHERE u.Reputation = @r
    AND   u.UpVotes = @u
    OPTION(OPTIMIZE FOR UNKNOWN);

END;
GO

First Way


The best case is we run this for a small number of rows, and no one really notices. Even though we get bad guesses for the second two queries, it’s not a huge deal.

SQL Server Query Plan
hands on

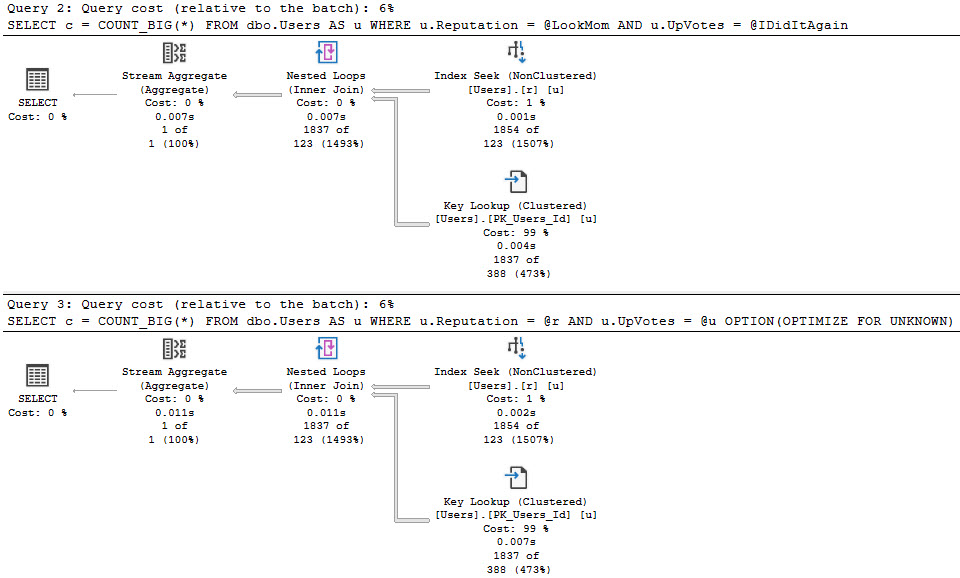
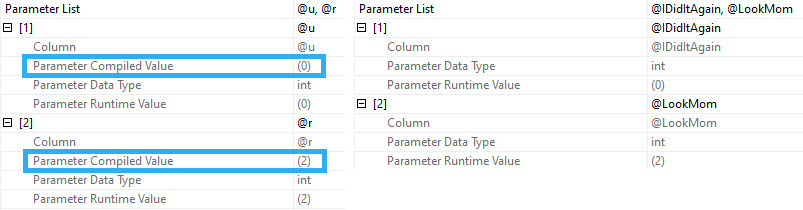
When you run procedures like this, SQL Server doesn’t cache the compile time values the same way it does when you use parameters. Granted, this is because it technically shouldn’t matter, but if you’re looking for a way to execute the procedure again to reproduce the issue, it’s up to you to go figure out what someone did.

SQL Server Query Plan
? vs ?‍♂️

Since I’m getting the actual plans here, I get the runtime values for both, but those don’t show up in the plan cache or query store version of plans.

That’s typically a huge blind spot when you’re trying to fix performance issues of any kind, but it’s up to you to capture that stuff.

Just, you know, good luck doing it in a way that doesn’t squash performance.

Second Way


In this example, our index is only on the Reputation column, but our where clause is also on the UpVotes column.

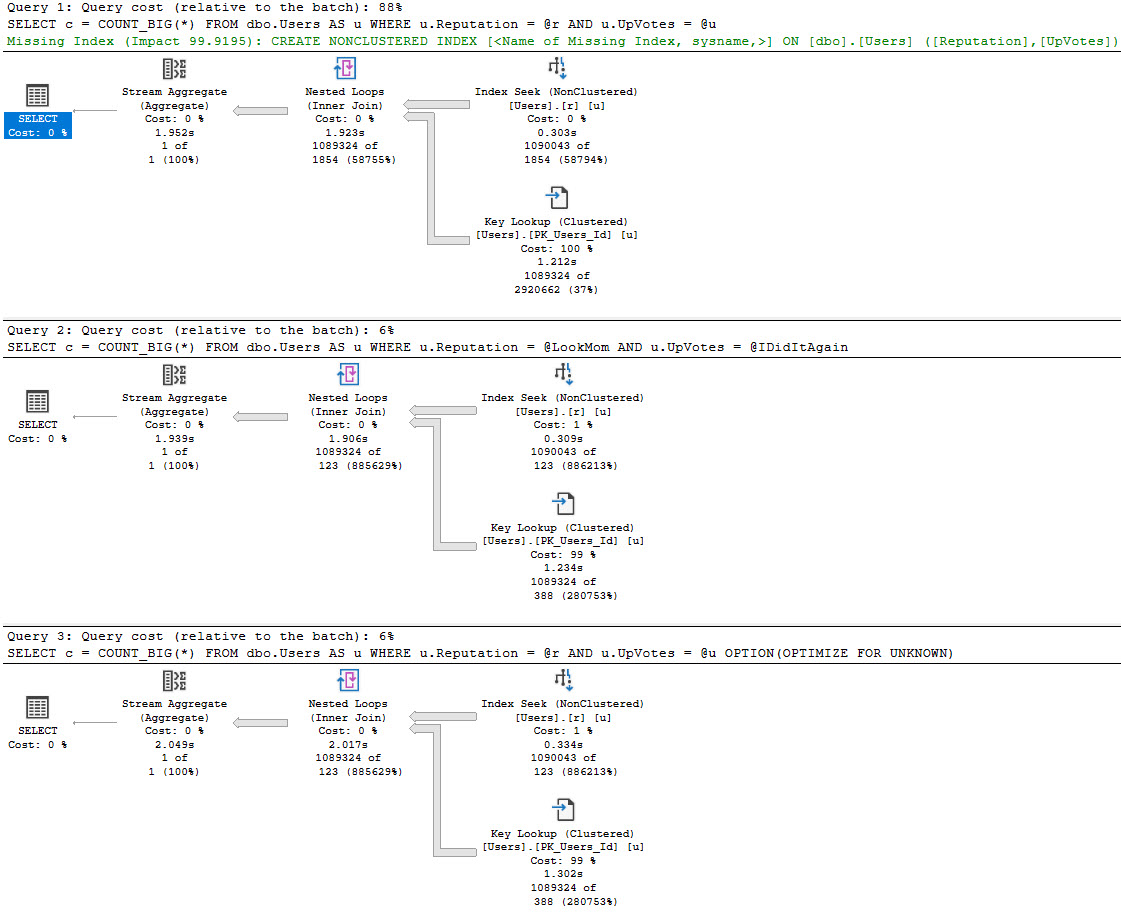
In nearly every situations, it’s better to have your query do all the filtering it can from one index source — there are obviously exceptions — but the point here is that the optimizer doesn’t bother with a missing index request for the second two queries, only for the first one.

That doesn’t matter a ton if you’re looking at the query and plan right in front of you, but if you’re also using the missing index DMVs to get some idea about how useful overall a new index might be, you’re out of luck.

SQL Server Query Plan
mattered

In this case, the optimizer doesn’t think the second two plans are costly enough to warrant anything, but it does for the first plan.

I’m not saying that queries with local variables or optimize for unknown hints always do this, or that parameterized plans will always ask for (good) indexes. There are many issues with costing and SARGability that can prevent them from showing up, including getting a trivial plan.

This is just a good example of how Doing Goofy Things™ can backfire on you.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Different Index Build Strategies For SQL Server

Link Up


This post is links to a series of articles that it’s a shame more people haven’t seen, because they describe why some index builds/rebuilds take a lot longer than others.

Hopefully Microsoft doesn’t black hole these, as they have so much other valuable material recently.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.