I got the chance to sit down and chat about index and statistics maintenance with the wonderful Erin Stellato (b|t), and the nice folks at eightkb.
Enjoy! And make sure to subscribe to their YouTube Channel for more great content.
Thanks for watching!
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Yesterday we looked at where table variables can have a surprising! impact on performance. We’ll talk more about them later, because that’s not the only way they can stink. Not by a long shot. Even with 1 row in them.
Anyway, look, today’s post is sort of like yesterday’s post, except I’ve had two more drinks.
What people seem to miss about scalar valued functions is that there’s no distinction between ones that touch data and ones that don’t. That might be some confusion with CLR UDFs, which cause parallelism issues when they access data.
Beans and Beans
What I want to show you in this post is that it doesn’t matter if your scalar functions touch data or not, they’ll still have similar performance implications to the queries that call them.
Now look, this might not always matter. You could just use a UDF to assign a value to a variable, or you could call it in the context of a query that doesn’t do much work anyway. That’s probably fine.
But if you’re reading this and you have a query that’s running slow and calling a UDF, it just might be why.
If the UDF queries table data and is inefficient
If the UDF forces the outer query to run serially
They can be especially difficult on reporting type queries. On top of forcing them to run serially, the functions also run once per row, unlike inline-able constructs.
Granted, this once-per-row thing is worse for UDFs that touch data, because they’re more likely to encounter the slings and arrows of relational data. The reads could be blocked, or the query in the function body could be inefficient for a dozen reasons. Or whatever.
I’m Not Touching You
Here’s a function that doesn’t touch anything at all.
CREATE OR ALTER FUNCTION dbo.little_function (@UserId INT)
RETURNS BIGINT
WITH SCHEMABINDING,
     RETURNS NULL ON NULL INPUT
AS
BEGIN
DECLARE @d DATETIME = GETDATE();
RETURN
(
    (
      SELECT @UserId
    )
)
END
GO
I have the declared variable in there set to GETDATE() to disable UDF inlining in SQL Server 2019.
Yes, I know there’s a function definition to do the same thing, but I want you to see just how fragile a feature it is right now. Again, I love where it’s going, but it can’t solve every single UDF problem.
Anyway, back to the story! Let’s call that function that doesn’t do anything in our query.
SELECT TOP (1000)
    c.Id,
    dbo.little_function(c.UserId)
FROM dbo.Comments AS c
ORDER BY c.Score DESC;
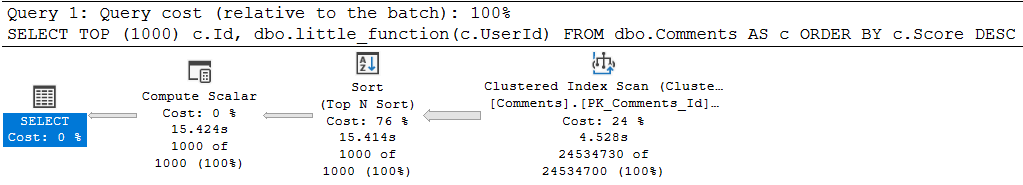
The query plan looks like so, with the warning in properties about not being able to generate a valid parallel plan.
what’s so great about you?
In this plan, we see the same slowdown as the insert to the table variable. There’s no significant overhead from the function, it’s just slower in this case because the query is forced to run serially by the function.
This is because of the presence of a scalar UDF, which can’t be inlined in 2019. The serial plan represents, again, a significant slowdown over the parallel plan.
Bu-bu-bu-but wait it gets worse
Let’s look at a worse function.
CREATE OR ALTER FUNCTION dbo.big_function (@UserId INT)
RETURNS BIGINT
WITH SCHEMABINDING,
     RETURNS NULL ON NULL INPUT
AS
BEGIN
DECLARE @d DATETIME = GETDATE();
RETURN
(
    (
      SELECT SUM(p.Score)
      FROM dbo.Posts AS p
      WHERE p.OwnerUserId = @UserId
    ) -
    (
      SELECT SUM(c.Score)
      FROM dbo.Comments AS c
      WHERE c.UserId = @UserId
    )
)
END
GO
Not worse because it’s a different kind of function, just worse because it goes out and touches tables that don’t have any helpful indexes.
Getting to the point, if there were helpful indexes on the tables referenced in the function, performance wouldn’t behave as terribly. I’m intentionally leaving it without indexes to show you a couple funny things though.
Because this will run a very long time with a top 1000, I’m gonna shorten it to a top 1.
SELECT TOP (1)
    c.Id,
    dbo.big_function(c.UserId)
FROM dbo.Comments AS c
ORDER BY c.Score DESC;
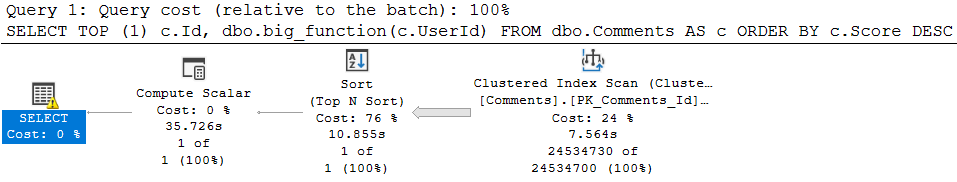
Notice that in this plan, the compute scalar takes up a more significant portion of query execution time. We don’t see what the compute scalar does, or what the function itself does in the actual query plan.
got yourself a function
The compute scalar operator is what’s responsible for the scalar UDF being executed. In this case, it’s just once. If I had a top that asked for more than one row, It would be responsible for more executions.
We don’t see the function’s query plan in the actual query, because it could generate a different query plan on each execution. Would you really want to see 1000 different query plans?
Anyway, it’s quite easy to observe with operator times where time is spent here. Most people read query plans from right to left, and that’s not wrong.
In that same spirit, we can add operator times up going from right to left. Each operator not only account for its own time, but for the time of all operators that come before it.
The clustered index scan takes 7.5 seconds, the Sort takes 3.3 seconds, and the compute scalar takes 24.9 seconds. Wee.
Step Inside
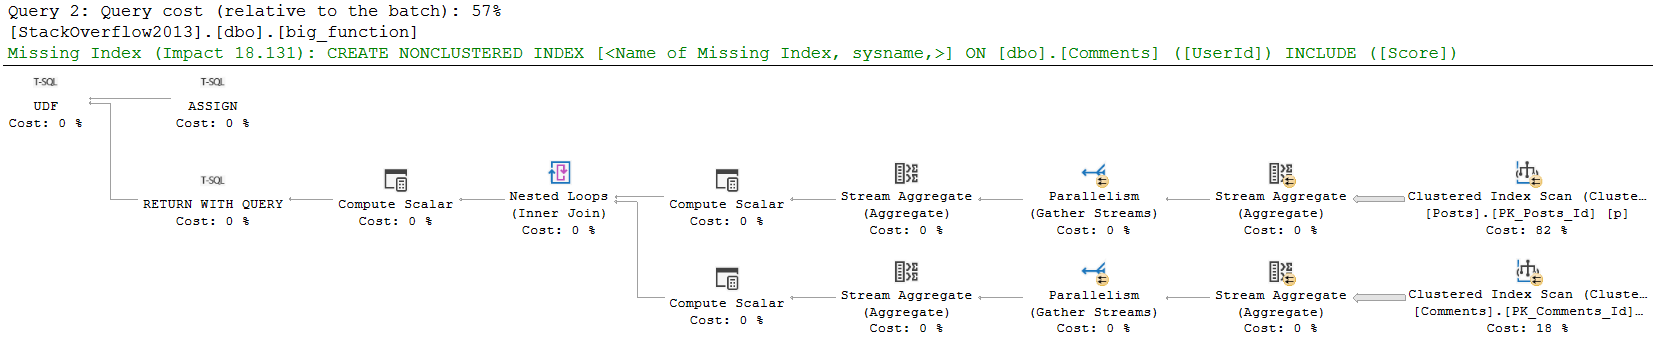
If you get an actual plan for this query, you won’t see what the function does. If you get an estimated plan, you can get a picture of what the function is up to.
monster things
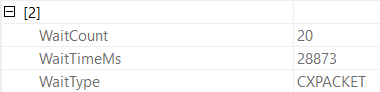
This is what I meant by the function body being allowed to go parallel. This may lead to additional confusion when the calling query accrues parallel query waits but shows no parallel operators, and has a warning that a parallel plan couldn’t be generated.
hi my name is
It’s Not As Funny As It Sounds
If you look at a query plan’s properties and see a non-parallel plan reason, table variable modifications and scalar UDFs will be the most typical cause. They may not always be the cause of your query’s performance issues, and there are certainly many other local factors to consider.
It’s all a bit like a game of Clue. You might find the same body in the same room with the same bashed in head, but different people and blunt instruments may have caused the final trauma.
Morbid a bit, sure, but if query tuning were always a paint by numbers, no one would stay interested.
Anyway.
In the next posts? we’ll look at when SQL Server tells you it needs an index, and when it doesn’t.
Thanks for reading!
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
CPU waits are relatively easy to figure out once you wrap your head around the settings that contribute to them, and the queries that cause them. There’s a pretty direct correlation between parallelism, thread usage, and CPU usage.
Compensating for disk waits is a bit of a different game, because there’s a bit to consider from a few different angles. But first, let’s distinguish a little bit.
Waits that commonly crop up when you’re waiting on disk:
PAGEIOLATCH_**
WRITELOG
When people hear they’re waiting a lot on disk, their first inclination might be that they need faster disks. For WRITELOG waits, that can definitely be a factor. For PAGEIOLATCH waits, it probably shouldn’t be your first move.
Relatively Speaking
When SQL Server hits PAGEIOLATCH waits, it’s to signal operations needing to read pages from disk into memory. If you just rebooted, this is inevitable. You start with a totally cold buffer cache.
But if you have enough memory, you’re not likely to see queries consistently waiting on it. Why? Because if data you need is already in memory, that’s where you go get it from. Why go to disk if you don’t have to? It’s icky out there.
If you really want to compensate for this wait, you’re going to need to think about a few things, like
How much memory you have, and how much memory you’re allowed (non-Enterprise versions have limits)
How much data you have, and how many indexes you have
Let’s say end user queries are consistently waiting on reading from disk. It doesn’t matter much if the wait is fast or slow, what matters is that the data isn’t in memory. Sure, it matters more if the waits are slow, but the first question is memory.
Do you have enough?
Can you add more?
Would what you have be enough if you had fewer indexes? (Unused/Duplicative)
Would what you have be enough if you had less data? (Purging/Archving)
Judgement Night
The reason getting memory right is so crucial is because of how much it’s responsible for.
Aside from caching all those thoughtfully crafted data pages, queries need it to sort and hash data, and there are all sorts of other lower level caches that rely on it. The plan cache is probably the most obvious.
Once you realize that memory is a shared resource, you treat it a whole lot differently. Especially if you know just how much memory some things can take.
Yeah, memory is cheap. Unless you need so much that your next step is going to Enterprise Edition.
But there’s an intermediate step in the mix that not many people talk about. You can have 2-3 Standard Edition boxes with data split out, and have it potentially be more cost effective than jumping to Enterprise Edition.
This is a better fit for applications/servers that use multiple databases, of course, but I’ve seen people do it with archival data too.
Of course, there are some disk things that you should fix. Like if you’re on a SAN and using <8Gb networking, or if you’re using a VM and not using PVSCSI disks.
The point though, is that if you have room to add memory, you should do that before fiddling with disks. It just plain goes further, because you’re not just helping queries read data into memory faster. You’re caching more pages overall, and you have more memory available for query memory grants (and other caching activities).
Faster disks also won’t do anything to help the waits we’ll talk about tomorrow, that can for sure be a sign that SQL Server doesn’t have adequate memory.
Thanks for reading!
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
I’m going to be taking a break in August, but I still want the Blogs To Flow™ while I’m letting my brain meat get its groove back.
So this month I’m going to run some fundamentals posts that I like teaching people about. Apologies in advance to people who expect a constant flow of more advanced stuff.
Why fundamentals? Because I still run into people struggling with the basics more than I run into people struggling with more advanced stuff.
Lots of people think they have advanced problems, but they really just screwed up something basic.
Anyway, my hope is that if you learn the basic stuff the right way, you won’t have to un-learn a bunch of bad habits later.
As far as hardware and settings go, I have 64GB of RAM, and 8 cores. That means my settings are:
MAXDOP: 4
Cost Threshold for Paralelism: 50
Max Server Memory: 51200
If your hardware and settings don’t exactly match those, you may get different results. These things matter, apparently ?
Stay Curious
You have everything you need to work along with these posts. If you have questions on anything, you can run your own experiments to try to answer your questions.
It’s not that I don’t want you to comment to ask them, but I’m not going to be checking in on stuff as regularly, and I don’t want you to think I’m ignoring you when you could be learning independently. You don’t need my permission to do that!
Over the course of the month, I’ll be talking about how queries get executed, query plans get made, along with table and index design, wait stats, and more. I hope you’ll stick with me, even this material is stuff you’re already comfortable with.
Thanks for reading!
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
In this video, I wanted to share some insights on crafting effective abstracts for conference sessions. As someone who has presented at various SQL Server events and continues to do so, I’ve learned that the key lies in striking a balance between intrigue and detail. The first line of an abstract needs to be compelling enough to grab attention—like a movie poster or Netflix thumbnail. It should pique interest without overwhelming with specifics. Following this, the title is crucial; it must clearly convey what attendees can expect while also catching their eye. I often reference Adam Mechanic’s approach as a benchmark, reminding myself and others that clear, engaging content is key to drawing in potential attendees.
Full Transcript
Thank you.
أي KHERRI. What a Friday, huh?
what a Friday it’s always exciting when it’s Friday because I know exactly what I’m going to be doing all weekend working working, working, working working on things for you lovely people out there working on things will hopefully make your lives easier less painful you know all that good stuff all that good stuff hopefully I can give you ways to make your job like maybe not hate your job as much or something, I don’t know like little things, right?
like little things that you get out of life not hating it not hating life is typically an admirable perhaps not achievable but admirable goal we should all strive to not hate life so how is everyone?
I assume you can hear me since no one’s complaining about not being able to hear me and Streamlabs is at least telling me that my microphone is receiving input but who knows who knows what these eyeballs have in store who knows what’s behind these eyeballs?
there we go we have message number one 99 to go until Twitch congratulates me on people 99 to go oh my goodness is that Chrissy here?
I’m terrified now now I’m terrified I’m going to say something I’m going to say something incorrect about seltzer and get yelled at see I’ve got two cans of seltzer here if you’ve been to my previous streams you know that I take seltzer very seriously take seltzer incredibly seriously and this this LaCroix seltzer right here is perhaps one of my least favorite seltzers of all time you know why?
the bubbles big and soft when you open it they sound big and soft like that’s a big soft opening and when you drink it it’s barely a seltzer it’s barely a seltzer the bubbles just pass over your tongue too quickly this Canada Dry the official seltzer of Canada it’s much sharper bubbles when you open it ooh you hear that?
bah it’s a big pop it’s a big heart these are good aggressive bubbles they spike the tongue they get on there they make your tongue feel like you’re drinking a seltzer it’s the big stuff it’s the good stuff big soft bubbles if you like big soft bubbles thank you thank you if you’d like to know more about it I will post things about the mic and headphone combo when I’m done but to me I feel like I’m still junior level with all of this with all this streaming stuff I feel like just very entry level I’m just showing up like hey I have a great screen hopefully I won’t elbow it and knock it over it’s like silently praying that I won’t fall backwards unless I ruin the illusion and see my dumb posters beavis and butthead artwork the best streamer on the whole twitch plant I don’t know I’ve never taken my shirt off shown my feet or played a video game so I think that there are people who are light years ahead of me with streaming who I think could easily topple me as in the best streaming category we are going ASMR with soda bubbles you’re going to learn a lot about soda bubbles today a lot you know what I think what I might start doing so that I can meet in the middle with much better streamers than me is I might get the headset with cat ears so I can at least be sort of cute on stream could at least be like a little cute do like a few cute things I could do like some paw stuff like this and then maybe I would catch up maybe I would catch up with with other streamers who are who are much better than I am much more talented than I am much better setups than I am I get I see what happens to me is I get weirded out because I watch people who stream and record streams and I think I think they have either much more talent with video editing than I do or they have like a company that does it for them because they get all these like cool graphic popovers and like sound effects and like things are like queued up properly like they’ll be like if you want to see more of my content like and subscribe and like a little ding ding ding bell will go off and like the button will show and you’re like what how’d you do that me I’m just like there’s a button somewhere on the website you’re looking at press it it’s okay I would like to have you back having people here gives me self-esteem when I have eyeballs when I have eyeballs I feel better especially on a Friday I feel better on a Friday all right so let’s get some nonsense out of the way let’s see it’s still hard for me too I hear slobs helps with the glamour but I haven’t so that’s what I use right now I use Streamlabs OBS and I think without the help of Drew Fergwell I would I would have I would have a much much crappier slob setup it there was a bunch of weird stuff that went wrong at first like I was starting up like when I share these screens with you they’re RDPs to either a VM that I have local on my laptop or a VM that’s running on the desktop that I have down here and to my right so for like SQL demos and stuff I go to the desktop so that I don’t have the streaming stuff competing with the demos right because some of them can get pretty intense when I used to record videos and everything was local on my laptop if I ran a demo that was particularly stressful on the hardware like if I was intentionally making SQL server boot on memory or on CPU the video recording would start to suffer like my voice would go all and like the camera would get weird and like pixelated so I realized pretty quickly that I had to like offload that stuff somewhere else but when I first started doing it I would do what I normally did when I did like Camtasia or something and I would just be like okay well I’m just going to hit I’m just going to type RDP down in the bottom and the RDP window is going to come up and I’m going to share that but what got messed up was that slobs couldn’t detect the window when I typed in RDP I had to type in MSTSC and Drew helped me figure that out Drew also helped me get my act together with the size of the canvas I was working on and the chroma key thing and getting things worked out so there was just a lot of stuff that were not for some help from some smart kids I never would have figured out on my own but as much as I’ve encouraged the smart kids to blog more about things they know about streaming they haven’t so it might just be on me to write the dumb kid distillation of what the smart kids taught me how to do so it’s tough so slobs does help with stuff but I just don’t feel like I’m a super advanced user and you know like adding in the crazy pop up here’s a thing like right now I don’t even have the slobs ability to not have my arm I can’t figure this out I end here that’s the end of my world and I wish I wish that I could figure out how to get like myself to just sort of be big enough to reach across the screen but without like making me so big that I cover up a lot of the screen without it like I just want I want to be able to move my arm in bigger directions but some of that is like office space limitations too like I don’t have the most amount of space right now but hopefully hopefully we’ll see what happens so we’ll get a couple silly things out of the way we are or we I am going to be presenting two online classes about performance tuning SQL Server it’s a full day of learning and it also a ticket to that class will get you access to all 24 25 hours of my recorded content if you use the coupon code floating above my head there that for some reason powerpoint has told me is a typo we’ll fix that we’ll fix you powerpoint if you use that you will get 75 bucks off the face value of a ticket and I don’t know that’s that I hope to see you either on July 10th or 24th those are both Fridays one of them is next Friday and one of them is I don’t know see if I could do this in movie style then it would be Friday and then next Friday and then Friday after next and I don’t know if they line up quite that well but they’re both Fridays in July so we have that to look forward to have that to look forward to so let’s get out of this enough enough advertisement as they say and let’s look at we’re going to look at a blog post first the first thing we’re going to do before we write one single second of a thing on the screen we’re not going to read the whole thing because you can tell by the size of this scroll bar over here that it is a long post and there’s a lot of information in this well actually there’s a lot of comments on this post apparently there’s more comments than post maybe but it is a fairly long post and there are a fair bit of words in it what I’m going to do though is I’m going to stick the link into chat so that everyone has it if you want to read it if you want to ignore me and read this if you want to save it for later either way is fine with me I won’t judge I appreciate I appreciate that you would come here and then click on that at all but this is a blog post by my old pal Adam Mechanic and he wrote this Adam you know spoke quite a bit Adam was you know quite adored and admired by the SQL server community until he left us for Python and Postgres and whatever other things he’s doing I hear he cooks with sea urchins a lot these days I don’t know he’s a very fancy person very fancy person but he wrote that he used to speak a lot he used to you know do a lot of pre cons SQL Saturdays user groups conferences all that good stuff and he was like he wrote what I thought were were very good very detailed abstracts and intros to his pre cons and so whenever I’m sitting down to to write anything new about what I’m going to teach people about I always like to go through this and just kind of you know like remind myself of a few things and I think one of the most important things is is this header right here because this is something I always mess up I try to write I try to write an abstract that I would think was like cool or funny or you know that like like I would look at and be like oh yeah I’d want to show up to that and that like well that’s not entirely wrong what that leads to a lot of the time is me not giving enough detail about what I’m going to be doing I sometimes make the mistake that like people might see my name and people might see like the title of the the session and people might see like sort of a round up of things that like things that I put in the abstract but like without enough detail without enough me saying like here’s like exactly what I’m going to go through the thing is that like sometimes I find that sometimes I find that tedious to read and sometimes I don’t know if that’s what’s going to grab people so what I try to do is have a mix in there I try to make that like first line like pop that first line has to have like some zing to it that first line has to be like like this is what’s going to grab you and make you want to like maybe read the rest of it or at least skim enough of the rest of it to like be like yeah I’m into that right like like like like you know like the cover of a movie back when movies used to have covers you know you’d go to like blockbuster be walking down the aisles and be like looking for a movie to rent you’re looking around and I know I know this is going to age about as well as a phone book analogy for indexes but that’s okay it’s okay you we will work through it we’re grown-ups we’re adults we’ll hold hands we will make through make it through this together but like has to pop right has to be interesting now like you know if you’re scrolling through Netflix or like Hulu or whatever service you use they don’t sponsor me either the only the only sponsor I’m after is Canada Dry Canada Dry if you’re watching I’ll work for Seltzer but so like when you’re when you’re like looking for something to watch like like either like the the picture that you see or like that the first line that you that you see has to kind of grab you right a lot of the times with with conference speakers you know there’s a cult of personality around them you know if you show up to a conference looking to learn something in particular or you’re looking at a conference website looking to learn something in particular there’s a list of names in like your mental rolodex of what things that you work on things that you’re interested in and you know you might like see a name that matches up with that you know whether you know it doesn’t matter what it is and have to be SQL Server it could be anything right like if you’re really into HADR you might have read like Alan Hurt stuff and you’d be like oh yeah I gotta go with Alan Hurt right like stuff like that there’s a mental rolodex of people who do that kind of work and if you are going to a conference or a session or let’s just let’s stop saying going to let’s say attending because going to these days is not it’s not a thing if you’re attending a conference or a user group or anything mentally you would you mentally associate this person with doing that thing like like that that’s like one of the first things that grabs you if you don’t like see then if you don’t see a name that grabs you immediately then you might start looking at titles so the title has to be really clear and the title has to grab you once you make it past the title well do people really want to sit there and read 10 paragraphs of explicit detail about everything you’re going to cover and learn and talk about and all like little bullet points and factoids and everything I don’t think so I mean I’ve never I’ve never had it come to the point where someone was just like you know I’m on I’m on the fence about attending your session I’m this close I just want to know if you’ll cover this one specific topic that wasn’t listed here like I’ve never had that like in you know I think sort of generally people understand from the title and from like the zinger what you’re going to get into and so I try to like you know get really specific with that stuff so like the title has to be specific but it has to be catchy and memorable and the the first line like the stuff that you put into the first into like that first paragraph or so the first few sentences not even like a full paragraph like like two to three sentences has to like grab people a little bit and it has to be something that people identify with you know if you are going to be teaching level 100 stuff or level 200 stuff that’s totally legit you can totally do a full day of teaching people you know like how to SQL with training wheels on I’m not against doing that it’s not typically what I aim for but it’s you know if that’s if that’s your jam go for it but sort of like generally you know I aim for somewhere in the I aim for an average of 300 but the day is gonna spend time between 200 and 4 like on the 200 side and on the 400 side I want an average of 300 I want people who maybe aren’t so advanced to be able to get to 300 and I want people who want really advanced stuff to also be satisfied with going above the 300 mark so you know you try to straddle the 300 no one’s really doing 500 you can’t do 500 500 is would be very difficult to do in an hour 500 is still pretty tough to do in a day 500 requires so much technical background and detail that it’s it’s difficult to properly humanize and I think the average conference attendee doesn’t appreciate that you know there are there are select few people who appreciate that but if you want to really really like reach out to a wide audience and get like like a like appeal to a bunch of people saying that like you know you’re gonna spend the day at 500 a that’s a tough mark to hit it’s tough to go eight hours at 500 eight hours at 500 stuff eight hours at 400 is tough eight hours at 500 is like I think you would have to be David DeWitt to spend eight hours at 500 but so like you know try to straddle it’s like try to straddle things right like set expectations for what we’re gonna do and set it appropriately you know I think that everyone learns something at some level regardless of whether it’s that 200 300 400 but you know you do you do have to you do have to give people mental breaks and you know giving the people who show up for the 400 level stuff a mental break is good and giving the people who show up because they need to get to 300 some like like like like totally it’s like like really tough stuff to think about down the line that’s also good right like challenging people is good but you don’t want to lose people right so it’s sort of a sort of like a it’s a fine balancing act he says I had a week course at 400 I reckon it was exhausting well yeah that sounds that does sound exhausting I think a week even a week at 200 is exhausting like I think like you know like beyond a day you’re that’s that’s a tough one to pull off it’s tough to pull off so there’s there’s lots of important stuff that goes into figuring out a what you’re gonna say what you’re gonna say about it you know you’re gonna have people you’re gonna have to get people in quickly you’re gonna have to get people to invest quickly because they have a lot of choice especially these days there’s a ton of choices out there for people to go and you know get their learning from everything is online and that just makes everything so much more accessible he says it was way over me if I’m being honest I was good for two days really yeah so you know there’s um if if it’s constant 400 after I think you’re right at probably after two days the the glamour wears off and you’re just like constantly bludgeoned by despairing facts and crazy niche stuff that you might have to do and be aware of and learn in these very specific scenarios but the other I think so like that brings up something in it because I think I think another really big problem with constant 400 level stuff or I mean forget 500 level stuff anyone who says they’re presenting at 500 I’m not sure I’m not sure like that I think that like like you would have to really carefully qualify someone talking about something at a 500 level like it couldn’t just be someone who like just uses it I think you would have to be talking to someone who like was part of the design or development team of a product or feature in order to get 500 but I think a lot of the the problem or the a lot of the difficulty with a constant stream of 400 is you’re just playing SQL jeopardy you’re listing off facts all day you’re listing off stuff that might never apply to people you’re listing off stuff that you know like you might have seen once in 20 years of working with whatever technology you’re talking about and you feel compelled to tell someone about it because just maybe just maybe it’ll it’ll help them one day but you know that’s what’s when you start that’s that’s that’s when like the the checklist stuff comes in and the SQL like the you know I guess this the this subject jeopardy stuff kicks in it just gets really tough to stay at that like get like get at that level and stay at that level that’s a it’s a tough one so there’s stuff in here that’s very good to consider when you’re writing an abstract right appealing to your audience figuring out who they are I start a lot of my abstracts with saying you know you’re a DBA or developer who’s been working with SQL Server for x number of years you know identifying the crowd be like oh yeah that’s me you know you have tough performance tuning problems like XYZ and XYZ can be you know XYZ doesn’t have to be terribly specific like XY doesn’t have to be like and you have a lot of problems with with like paging queries or you have a lot of problems with like I don’t know whatever else right like you don’t know how to read execution like there’s a lot of like it’s like like overly specific stuff that you can put in there but you need to be able like like this is like for me some of that stuff is like what goes later on like when we get into detail when I’m trying to figure out what problems you need to solve I’m like you have a tough time like figuring out where to start you have it you don’t you don’t know where the problem is like you know you have performance problems but where are they is it the queries the indexes is it like you know is it like the way your tables are designed are your server settings terrible is your hardware like underpowered like like like where do you start right like people who are just looking at SQL Server and like maybe open activity monitor or like run SP who or SP who to and is it just like the I don’t know what happened because SQL Server is tough like that SQL Server does not make it terribly easy does not make it terribly easy to figure out what happened they make it very easy to see sort of they make it easy to see what’s happening there’s a lot of stuff you can capture hitting f5 but you know if if something was wrong you know at the rate that users report it you know last Thursday or two hours ago or something you know this might not be a lot you can figure out or do with that so you know a lot of people do have problems a lot of people do have problems with figuring out you know just where to begin with SQL Server troubleshooting like and you know it’s it’s my job as a presenter to think to tell them which place I’m going to get them to right carvin says can you please suggest database migration checklist no that’s not the kind of thing that I do but if you really want something good to help you with that give me one second to bring up the commands over here migration here we go if you want something to make that easy there you go but just to make it perfectly clear this isn’t that is not something that I do and that’s not something that I have and if if you have more detailed questions about it I have I cannot I will not have more detailed answers if I had to do it that’s what I would do I would I would I would hit it’s not f5 in PowerShell in PowerShell it’s f8 I would grab that script I would hit f8 and I would I would sit back and let PowerShell do the rest I’m not smart enough to have written it but I’m smart enough to use things that smart people write because that’s that’s basically what the world is is is learning something is like being lucky enough to have smart people around you do things and you just say oh they can make my life easier so let’s see when we’re when you’re trying to figure out who we want to talk to how we want to talk to them right and we and we want to make sure that we do it in a way where you know someone who might be like nervous or just sort of like unsure where they fall into the world well I mean you have you have to be careful with the way that you phrase things and way you the way you word things right because you you want you really do want everybody to be in there like you don’t you don’t want to say like oh like you know you’re you’re a you know beginner IT guy or something like that right you just don’t like you know leave that kind of stuff out so what we need to do is figure out who we want to talk to what we want to talk to them about and then we can come up with the catchy stuff we need we need to know we need to identify a few things first before we go and before we go and even start writing a single thing he says must be utterly nerve-wracking doing presenting as I said it’s no like the presenting part doesn’t really make me nervous anymore streaming makes me nervous because I am just not confident in the technology enough like I I I’m relieved and I find it to be quite miraculous that I could download a few things hit a few buttons and show up on a screen and close to real time in front of people I am amazed by that but like it still makes me nervous it still makes me very nervous I don’t like like nothing I think is bad technology it’s just it’s it’s nerve-wracking like just think like waiting for something to go wrong right like waiting for audio to cut out waiting for video to cut out waiting for like my internet to fall apart waiting for like one of like the receiving servers to just fall apart like just all this stuff that could go wrong when you’re on screen you’re just like oh please don’t fail like like and it’s not because I’m like I would be embarrassed for me it’s because like I don’t want I don’t want anyone who watches me to have a bad experience watching it’s tough enough watching me without technical difficulties so yeah so Adam brings up a good point and this is kind of the point that I was starting to make is people can’t be some people can’t be bothered to read big full paragraphs of words because I like the lack of pretzel so I I tried pretzel for a minute I downloaded it and I started listening through the music the EDM category was deeply deeply offensive deeply offensive but even more offensive was the hip-hop category if you ever want to be deeply offended if you if you like hip-hop at all and you want to be deeply offended look at like listen to the music in the hip-hop category on pretzel you will be so angry it’s it’s horrible it’s horrible read in 2020 let’s see I know that’s in here somewhere yes read in 2020 is there is there a reference to 2020 in here I thought there was so yeah so let’s let’s let’s back out of this blog post because I think we’ve spent enough time in the blog post all right there’s there’s enough in here there’s enough for you to go over later on your own so let’s talk a little bit about what we could present about because usually you know the thing that I get into and that font is just terribly small I don’t know why I don’t know why you’re messing with me PowerPoint’s messing with me all the time let’s make that a nice size font 28 sounds good to me that’s because what I usually talk about is performance what I don’t talk about things that I’m not particularly good at is HA no DR no security hell no not my jams PowerShell I’ve tried it was not I found myself sadly wanting in all things PowerShell couldn’t hack it I was not good I was not I was not good enough I was not smart enough and and power me and PowerShell did not get along what would always happen is uh you know I would and like I would I would I would have something to do and I would think this is what people use PowerShell for this is what people use it for and I would spend some time like searching around for the right commands to run and I would like try some stuff out and then like you know I would start getting closer and closer and then like three four hours later it would just be like me weeping over the keyboard because I couldn’t get anything to work it was just I T SQL has so infested my brain that that is like that is just where I have to go and where I have to stay whenever things get whenever things go outside of that I fall to pieces this is like if I’m not performance tuning something I’m like I don’t I don’t know what it does like like like poking it just like what are you I don’t understand so uh we shouldn’t we should at least get this to now match up right heck yeah so I do performance stuff uh yeah so it’s just it it’s funny how like like someone can be you know very very good at one thing technically or even intellectually or you know and just like you know be able to just like very quickly deeply like understand and grasp things and then look at something else that’s like equally and you’re just like like I don’t know like riding a bike like like riding a bike just like ah pedals like you could be an f1 driver like like be able to speed around tracks at like close to 200 miles an hour and handle things perfectly and then like like you know look at look at look at a bicycle and be like I what is this is this I don’t I don’t know I don’t know it goes too slow for me to figure it out so we have performance which I’m into HA is out DR is out security is out powershell is out but we still have some things within performance right within performance we have some choices do we want to talk about server tuning which would be weight stats hardware settings etc do we want to talk about index tuning and if we’re going to talk about index tuning what are we going to talk about within index tuning we have to set some expectations here because there’s a lot of different kinds of indexes within SQL Server not all of them are typically well used and they’re probably not things that people would expect you to cover but you have to you know if like I think you know you don’t need to say uh no XML spatial or in memory like you probably don’t have to go so far as to say that’s but you should probably specify are you going to cover a columnstore are you only going to cover rowstore like what what are you going to cover within these things now I I love I love columnstore but I do not have the chops with columnstore to spend a full day talking about it the internet is full of blog posts about columnstore that are just sort of rundowns of the documentation you can kind of tell that someone flipped on their laptop you know had like one of the smaller Microsoft databases ran a few scripts and they were just like cool here’s a blog post you they’re missing that sort of deep understanding of columnstore the things you can run into it like the actual like production usage of it like my friend Joe Obish he uses columnstore like a champ he uses columnstore like a champ he but he’s been through serious serious pain learning it without that pain some of that some of that learning just isn’t there and you kind of get this like you know that shady acres pamphlet like just send your data to columnstore it’ll be it’ll chase rabbits all day there will be other data just like it it’ll have friends without like any of like the real deep understanding of just like oh damn don’t do that oh dude just stay if you’re doing that run screaming like bad idea bad idea bad idea you know you get like you get like the glossy pamphlet you don’t get you don’t get the full story there’s a lot of errors and omissions when people have not used something deeply in production and so as much as I love columnstore I am not qualified to talk about columnstore I have never done any big uh you know columnstore migrations I’ve never done any big columnstore tuning projects I’ve done regular query tuning and I’ve you know figured out when people would be better off with columnstore and I’ve helped them you know move some stuff into there but I just haven’t run into like like the bevy of problems that you know you would if you’re regularly working with columns or with ETL stuff like that so we’re gonna not do columnstore if we’re gonna do columnstore I am going to stick generally to rowstore indexes, because that’s where my knowledge is.
I just don’t know columnstore well enough to stand there and answer questions about it. So, if I’m going to do server tuning, this is an interesting one.
This is an interesting one. Because it feels to me like the more you talk about waitstats, the less people want to use waitstats.
Waitstats have very real flaws in them. Particularly the way SQL Server logs them, where they’re just sort of aggregated since the server started up.
You can have very, very unreliable data there. But they’re somewhat helpful to identify big bottlenecks. Big problems.
Big problems. All right? If you see just like crazy waits on something, it can be helpful there. But you can miss a lot of the picture, right?
If you have a bursty workload that’s only busy some parts of the day, and does really nothing else for hours at a time, waitstats become less useful.
So, if you’re going to teach people about waitstats, you have to give them a way to gather waitstats in a way that makes them more useful for them. Not many people have that constant 24-7 pounding workload on a server.
And even if they do, that workload isn’t typically all user-facing, right? Even those servers will have some sort of night maintenance, you know, code rollout, change management, you know, whatever they’re doing, taking backups, running CheckDB, index maintenance, stats maintenance, whatever it is they’re doing, there’s typically some maintenance window for that.
But very few people have the, like, 24-7 need to just constantly be running queries. So, or user-facing queries, I should say. So, if you’re going to do waitstats, you really do need to give people a way to gather waitstats in a way that they can make sense of their workload.
There’s all sorts of stuff about waitstats. Sure, you can hit F5 and you can get sums and averages and percentages, but a lot of the stuff that you can just hit F5 on, you also don’t get, like, how long the server has been up, so you can kind of compare things to that.
Because a really important metric when you’re looking at waitstats is, like, compared to what? Like, the famous economist question. Like, compared to what? Like, how are you doing today?
Compared to what? I don’t know. Like, compared to someone who is staring at an IV in the hospital, probably pretty good. Compared to someone who’s sitting on a yacht in, like, the south of, like, off the south of Europe, you know, doing something fantastic with themselves, probably not as good, right?
Compared to what? So if you’re going to give someone stuff about waitstats, you need to give them a lot, like, a lot to, like, make sure that they know what to compare it to, how to gather stuff, how to read stuff, what waitstats mean, what waitstats are problems.
And that’s a tough gig. Because most of the time, when you start writing stuff like this, you start thinking, well, maybe you should just get a monitoring tool. And you think, maybe I should write a monitoring tool.
And you think, oh, that sounds hard. I should just go work for a monitoring tool. And you think, oh, I don’t really want a real job. And so I tend to stay away from this stuff now.
The thing about hardware, too, is that with a lot of workloads being virtualized or in the cloud, stuff that you can say with confidence about physical hardware changes quite drastically when it comes to virtualized hardware.
You know, there’s stuff you could say about, like, SOS scheduler yield, CX packet, you know, page IO latch, all that stuff. That, you know, on bare metal hardware, you would be right.
Virtual hardware, you would have a lot more to dig into. So if you’re going to start talking about hardware, you kind of have to know a lot about not just, like, the CPU and the memory, but now you have to start understanding virtualization layers, how VMs talk to the virtualization layer, how things might look if you have a lot of VMs on, like, a lot of VM guests on one host, all sort of making crazy requests, asking for resources in different ways.
Like, maybe you have an over… Like, what used to be a concept like, oh, your CPU, like, your SQL Server hardware is just underpowered. Could be, well, you gave SQL to the SQL Server VM enough hardware. The problem is it has to share that hardware with, like, 30 other SQL Server VMs on the same host.
Because everyone who virtualizes is a cheapskate, and they license enterprise at the host level, and they’re like, cool, so everything gets enterprise and goes here. And that’s, like, the new kids on the block version of, like, just stacking a bunch of SQL instances on the same server.
So, like, if you’re going to do hardware, you really have to understand, like, virtualization. You really have to understand VMware, all the little intricacies of things that can go on in there with, like, settings and, you know, how you, like, can, like, have VMs allocated and, like, where they go and, you know, like, crazy stuff, too.
Like, just, like, how, like, what a big difference, like, para-virtual SCSI connections can make over other things. And then, like, you have to, like, you know, like, the stuff you have to get into with hardware can be pretty challenging.
Forget all the stuff you might need to know about the cloud and cloud instances. It’ll be wrong in three months. So, hardware is kind of getting turning into a tougher and tougher subject to teach.
I used to really like talking about hardware because there was, like, some, like, cool stuff that you could show people, like, like if you have a bunch of queries run and run out of worker threads, or when you hit resource semaphore because you run out of memory to grant out the queries, or when, like, your server just plumb doesn’t have enough memory and you spend most of your time waiting on page I.O. latch or whatever it is.
But, you know, like, and, like, well, I still enjoy that stuff from teaching people about it from a performance perspective. You know, you get to the point where you’re like, okay, so, like, is the fix for that in the cloud, like, to just move to a bigger instance size?
Because, like, there’s no longer that challenge of, like, oh, we’re going to order the memory, shut the server down, install the memory, turn the server back on, wait three days for post to test the memory, stuff like that.
It’s just, like, it becomes a lot easier to just say, well, flip a button and see if it goes away, or flip a button and see if it minimizes some, right? So, like, when I teach people about those wait stats now, it has to be in the context of, well, how can we tune the query or the queries or the indexes in order to make better use of the hardware so that we are not pounding SQL Server out the way that we used to?
And then, you know, settings, golly and gosh, I can’t imagine someone sitting through a full day of how to set maxed op and cost threshold. So, the server tuning stuff, I kind of get away from a little bit.
So, within performance, we can talk about, you know, index tuning, and we can talk mostly about rowstore indexes. So, that’s one possibility.
There’s also query tuning, right? And query tuning, but, you know, query tuning should go hand in hand with index tuning. I would say there are certain query writing patterns that should certainly be taught and addressed, but if we’re going to talk about how to tune a query, you can’t just leave out how to tune indexes.
You can’t just leave out how to identify if your index key columns are in the wrong order, if you should fix a key lookup, if you should fix a sort, if you’re getting the right type of join or the wrong type of join because of the way your indexes are designed.
There’s just, like, so much that you need to think about and figure out when it comes to that stuff. The query and index tuning kind of go hand in hand.
There’s a couple of things over in chat. I’ve been watching your video from 11 days ago for the past 30 minutes and realized I wasn’t live. Ha ha ha! Well, now you’ll be able to tell because I’m much hairier. We have OLAP queries in the weekend which screw up all the wait stats.
See, that’s another thing. You can, like, that’s another terrible thing about wait stats is, like, you can’t filter them out based on when they happen. And unless you’re on SQL Server 2017 and you have Query Store turned on, it’s very difficult to figure out which queries are responsible for which waits.
Like, what happened to you? Like, what caused you? Oh, like, that makes a big difference too, right? Like, if you had some, like, big OLAP query come along and cause a bunch of, like, thread pool to restore a semaphore waits, you might look at wait stats overall for the server and be like, holy smokes!
What happened to you? But, then, like, you look at, like, the regular user workload and you’re like, none of that’s happening then. So it’s just like, come on, Microsoft, give me something.
Give me something. Throw me some bone. So within performance, query tuning and index tuning should go hand in hand.
And, I think it’s very important with indexes, specifically, to not, to make sure that people understand you’re not going to sit there and teach them what a B-tree is because that doesn’t help them.
You don’t want to, like, what’s on an index? Like, here’s an hour of DBCC page demos. Like, it’s just, stuff has to be practical too.
Right? Like, if you just sit there and do a full day of, like, this crazy trick that no one’s ever, no one’s going to walk out of there and ever see in their life, they’re just going to be befuddled as to what happened.
Like, what did I do? What did I just learn? If I see this, this one very specific set of circumstances that this consultant up on stage saw once in his 25 years of working with computers, well, eh.
But it’s so great to teach people about IO complexity. Yeah, when they’re really interested in IO complexity and they’re geared up to learn about IO complexity, that’s a great thing.
If you have a bunch of accidental DBAs in a room who are just like, do I have IO complexity? Is my IO complex? Do they really need to learn about how complex IO is or do they need to learn how to find their problems and fix them?
Right? It’s like, if you have people who are like, yeah, teach me about, like I’m a sanded man, teach me about the IO complexity or like, you know, like it’s just someone who has an interest in it because they’re down with it, then like what?
Yeah, great. IO complexity in general, not going to solve a lot of problems for a lot of people. It’s just not. A lot of people are not going to look at IO complexity and be like, oh, now I know why that query is slow.
So query and index tuning should go hand in hand, but it has to be practical things they can use when they leave.
Right? We can’t, we can’t just teach crazy stuff all day long. So we have query and index tuning. We have, we have that.
But there’s a lot of query and index tuning stuff out there. Do we want to specify it? Do we want to say something like for OLTP, for OLAP?
Like, do we want to specialize? I don’t know. I don’t know. Within query performance there’s other stuff too. Right? Like, if we’re going to query and index tune, what if it’s not just the query?
What if there’s blocking? Do we need, do we need to cover blocking as, do we consider blocking to be a performance problem?
Is blocking a performance problem or a concurrency problem? That’s something else we need to figure out. Right? Like, like, like, where do we want to go with this thing?
Like, which areas do we want to cover? Within performance there’s a ton of different things that you can look at. So, what do you think? What do you think out there?
There are, there are, there are people who have been in here listening to me. Listening to me talk and listening to me talk about, like, you know, like performance tuning subjects.
And not just today, like, you know, over the past, like, couple weeks or so that I’ve, I’ve been streaming. What, what things do you find yourself wanting to know more about?
What, what things do you find yourself having trouble with? He says, one thing I have found a gap in with a lot of things I have attended, it’s really looking at queries the size of the ones you see in real life. Presenter needs to get to the point across, but it’s a different world.
Yep. So, and I run into that too. So, here’s the thing. If, if I may, if I spent the time to make every single query big and complicated, and I, and I showed it to you, there’s a lot that you would get distracted by.
You would be looking at the query, trying to figure out what it does. You’d be looking for mistakes. You’d be trying to find this out of the other thing. What presenters need to do is come up with the simplest way to describe a concept, to describe an anti-pattern to look for, to give you something to look for in those big queries and in those big plans that you can single out and try to fix.
It’s not always like, you know, the most germane thing in the world to try to, you know, write a gigantic query that has this one problem in it and focus in on that.
Sometimes you have to say, look, here’s the problem you’ll see. It could be part, it could be a small part of a big picture, but here’s the small problem and here’s how to fix it. Let’s see.
Coyote McD says, does a pre-con have to be super practical? What about a pre-con for nerds who just want to learn how things work? Sure, but that’s a very, very limited audience. If I’m going to do a pre-con, I want to appeal to a wide, to a wide range of people who need, who need help.
Right? The nerds who want to know how things work are, I mean, what? one in, like, like the people who are really, like, ready for that, interested in that, and need that, there’s a much, much smaller crowd than I would aim for.
I want to be able to teach, I want to be able to teach as many people at one time as I can. So for me, it does have to be practical. And, you know, it’s funny, it’s funny the way you worded that because a pre, like a pre-con for nerds who want to learn how things work, sounds pretty practical to me.
But I get what, I think I see what you’re getting at with, like, you want the deep internal stuff. You want, you want that next level in that isn’t common knowledge. And like I was saying before, to get that sort of thing, that’s where you need, that’s where, I mean, say, like, that is where you need a Bob Ward type person who has that, who has access to the, like, who can see the source code, who can see the private symbols, who is, you know, whip crack with window bug, and can, who can, like, give that deeper internal’s knowledge and, you know, do pretty well with it because people would want to learn that from Bob.
There are very few people who, A, people would want to learn that from and there are very few people who I think are ready to and who would fully grasp whatever they’re teaching. So, what you said is actually a very practical thing.
A person who just wants to learn how things work. Right? They just want to, just want to know how to solve a problem. Learning how something works so they can fix it.
Lee says, I guess it’s a fine line between hobby and work. Hobbyists want to get deeper, the next thing I want, yeah, exactly. And you have to, you have to be able to respect both crowds. Right?
And there’s also, there’s also a funny question there, is it’s, does the hobbyist show up to a day-long pre-con to learn? Does a hobbyist get, you know, their work to pay for a pre-con to, like, for them to attend, show up, hang out, learn stuff for a full day?
Does the hobbyist show up for that full day training? The hobbyist might show up to a conference to get some time off work, to get some free travel, show up to a couple few sessions where the title attracts them, but I don’t know if the hobbyist is going for that full day.
Getting the hobbyist into the, if you can, if you find a way to get the hobbyist into a full day, you have cracked a very, very unique market. That is, that is a very, that is a tough, tough nut to crack.
Mostly you, mostly you need the people who, you know, either, you know, they are the hobbyist, or rather, like, yeah, they’re the hobbyist who wants more, who, like, you know, craves more, or, you know, they might be, you know, the people who, you know, who just want to, like, learn how to solve a problem, but their boss is just sick of them being that person.
They’re like, look, we have real problems that you want to solve. Here’s an extra 400 bucks. You’re going to go to this day. You’re going to learn some stuff. Maybe it’ll help. Right? Look at all the crowd that you have.
Yeah, you know, sometimes it’s better than others. Sometimes it’s better than others. This isn’t, this isn’t a particularly riveting SQL Server topic. So I don’t know.
I didn’t expect a big crowd today. But I’m happy for anyone who shows up ever at all. But, you know, if I’m doing something where I’m actually talking about, like, real SQL Server stuff, then you usually have a few more people.
And this is, this is like a weird soft skill one. So I don’t expect a lot of people in here who aren’t just, like, drunk, bored, in Europe after work. Something like that.
So, you know, I had different expectations for this one. Different expectations. But, we’re having fun anyway.
And we’re going to write this thing anyway. So, we figured out a few things. We’re obviously going to talk about performance. But where do we want to go with performance? I do a lot of performance tuning training that ends up hitting pretty advanced stuff.
And I think, well, I think two things at the same time. Sometimes it’s difficult. But I think two things at the same time.
One is that there is probably a market out there for people who are beginners who want to start being advanced.
And then there are also people who think they’re way more advanced than they are. They’re the people who always have a what about but what if but it’s never about anything particularly pertinent or anything that would really work.
So, there’s two crowds out there. If I’m going to focus on a crowd right now as far as material goes, I think I want this crowd a little bit.
I want people who realize that they don’t know what they don’t know. who are having real troubles performance tuning.
They might read blogs. They might, you know, watch videos. They might, you know, they might go to user groups and stuff. But they’re just not making that jump.
They’re not making the right connection to figure, to like get themselves on the path to advanced. So, I want to start, I want to start, I think I would like to, for this one, attract people who need to go, maybe not from like 200 or 300 to 400, but maybe from like 100 or 200 to 300.
I don’t want to have to get crazy deep into stuff. I just want to give people, I want to give people enough so that when they start looking at code and indexes and query plans, they can start like, like thinking for themselves, learning for themselves and fixing problems themselves.
He says, I don’t think he wants to see us. That’s not true at all. I would love to see faces. Like, maybe not in this format, but if, if, if, well, we were live and in person and I was looking out at you while I was doing this, I would be very, very happy to see, see those faces.
So, it’s not like I don’t want to see you. I just don’t think this is a great format to see you in. Like, if I had like a Brady Bunch style, like lineup of faces off to the side, I don’t, I don’t know that that would be helpful.
The CPL puts you and it’s like, connection timing out and whatnot. So, what could we call, what could we call a pre-con?
What is our title going to be? Where we try to, we try to attract people who need to go from like one, two hundred to three hundred.
Like, what’s some good stuff in there? What’s some good stuff that we could call it? I’ll give, I’ll give y’all some time to think. I’m going to, I’m going to give it a few. Let’s see. Maybe, uh, the beginner’s guide to advanced performance tuning.
That might be a good one. Uh, man, you’re failing me miserably. no and no. Uh, damn, Arthur.
Putting me up, putting me on blast like that. Put me on blast. Video freeze for anyone else. I don’t know, but I’ll stop and wait for someone else to answer.
Maybe try refreshing, Arthur. Did the audio also freeze or can you still hear me? Uh-oh, Arthur.
Might want to check that internet, pal. So maybe the beginner’s guide, why are you blue? Oh, because you’re, no, screw.
I’m not changing that. Beginner’s guide to advanced performance tuning that might run. starting SQL, um, uh, let’s see here.
Uh, let’s see. Uh, what would be a good way of starting? Maybe starting isn’t that great of a, maybe that isn’t. Had to reboot.
Like your whole computer? I’ve been playing too many video games, man. It’s got, you know, all that precious VRAM. That precious VRAM is sucked up like video games.
SQL Server, taking the next step from beginning to advance. Okay, that’s got something to it. All right. I don’t know if I necessarily want SQL Server in front of that.
Maybe I could do, you know what, maybe we could, we could combine forces a little bit here. Maybe we could call it, oh, and look at that pasting with full formatting. So I’m going to give you, I’m going to give you probably the most invaluable piece of advice that I have.
When you have text that is formatted in a certain way, like when I paste that text there, it comes up with a background and different fonts and everything. If you click on the Windows icon, oh, it’s not in here.
If you click on the Search icon and you paste something in there and then you copy and paste it out, you get rid of all the formatting. But we’re going to have to fix these words a little bit.
Next. Step. From. Beginner. To. Advanced.
There we go. Using Notepad for that. See, there you go. There’s all, see, there’s all sorts of fun tricks out there. I don’t trust Word.
When he says paste values in Word, I don’t trust that. Every time I paste values in Word, you know what happens? It changes fonts on me. Like, I’ll hit enter a couple times and a font will switch to something else.
It’s never a good experience. I don’t, unless I can, unless I have the raw values from somewhere else, I just don’t trust Word to do anything right. Like, like, you ever try to, like, get Word to, like, like, go, like, you scroll down and then you’re like, oh, I want to put something here and you’re like, hello, and then you, like, write some stuff up here and you hit this and then, like, this just jumps down and then you, like, spend some time trying to get this to work and it’s just like, it just jumps up and down in, like, weird increments on you.
Like, I just don’t trust Word to do anything right. I just don’t. I just don’t ever do it. So, let’s call this title. So, we have two now.
We have Beginner’s Guide to Advancing and we have this one. Oops, come on. Come on. All right.
So, what else do we have in here? What else could we do? We’ll be, I’ll give, I’ll give, I’ll give one more lucky, lucky person a chance.
Come up with a title. Advanced Performance Tuning, Starting SQL, Taking the Next Step from Beginner to Advanced. see, the problem with this one is, we need, we need, we need, we need people to know, uh, that it’s about performance tuning.
If we don’t know that it’s about performance tuning, people will say, Beginner to Advanced, what? What you should know about performance tuning?
I don’t know about that one. It needs to be, it needs to be more, be more action packed. Right? It needs to be more action packed. It’s a bit nebulous. We need, we need something that, we need something that signifies someone is, someone is, someone is starting from the beginner area.
Right? Someone is on the path to advance, but they haven’t quite made it there yet. Right? So, we’ll, we’ll, we’ll come back to that and we’ll think. So we have the title. So we have the titles down.
So, who? There’s performance tuning, find where it hurts and fix it. Woo! I, I like it and I would use that for something else, but you know what?
But I, I, I, but I, what I need to, or what I would need to do with that is I would need to, I would need to figure out how to get, oops, I would need to figure out how to get it to also include the fact that, you know, this is a beginner level class, that this is not going to be, you know, three and like, you know, 400 level stuff.
stuff, and I would need, so I would need like that, that sort of thing in it. We’ll get some, get some capitalization in here.
So, who, who are we talking to? In this case, we don’t necessarily want, uh, DBAs, because, uh, oftentimes, so actually, you know what, let’s not do it by title.
What we don’t want, this is, not about, infrastructure, issues, like, backups, hardware, HADR.
Right? So, accidental DBAs is, is okay. I’m okay from, I’m okay with, uh, accidental DBAs. I’m also okay with software developers. But what I don’t want is, infrastructure DBAs.
I don’t want a junior DBA, who, is consumed by, you know, taking backups, restores, check DB. Not because I don’t want them to learn about performance tuning, but that’s just not where they’re focused right now.
That’s not where, like, that’s not what they’re showing up to a class to learn. I don’t want people to think, I’m going to teach you how to take backups faster. Right? And I want people to learn, like, like, you know, how to, you know, how to, you know, get your availability group to fail over faster.
So, like, I don’t want the infrastructure DBA. I want the, I want DBAs who are doing performance tuning. So, let’s, let’s, let’s focus in a little bit about that, on that.
You’ve, then, performance tuning SQL Server, for, for, let’s see, for a year or two. So, a year or two is probably good.
Um, because that would at least get people in the door who have, you know, looked at a query, query plan, have looked at indexes, have probably fixed some problems on their own, and who are, who have probably gotten to the point where they’ve hit a problem where they had to go read something.
Right? So, like, they’re not totally unfamiliar with things. They just might not have the depth of knowledge on certain things that gets them to the advanced part. So, did the advanced part.
Uh, so let’s say you’ve been, you’ve been performance, like, uh, we want people, let’s, let’s not write the abstract in the who. People who have been performance tuning for one to two years, probably read blogs, watch videos, and are familiar enough with SSMS.
Oops. Uh, query plan, oops. Someday I’ll get it right. Query plans, uh, indexes to not need, um, let’s see.
Well, let’s figure out a different way to say it. Um, let’s say to not know, like, so like, like, what I want to identify is, you know, people who, um, um, people who know what these things are and where to find them.
Like, I don’t want someone who’s just like, but what script should I run to look at my indexes? Like, I want someone who’s a little bit more engaged in that. Uh, uh, and how to find them.
That’s good enough wording for now. So, let’s see here. Lee says, it’s the glue that links different concepts together to provide a solution. That’s the hard part.
Yeah. So, you know, um, whenever you’re tuning a query, you know, there, you know, there could be any number of things that look pathologically wrong with it. You know, it could be something in the query plan with the parameters, the way the query is written, but getting like to the end result of what was actually slowing it down, it could have only been one or two of like the five or six things that you spotted.
Right. Like it could be, and it could be like, you were just like, Oh, Oh, it could be that. Oh, it could be that. But then like, you know, you go hit a five, you look at the actual plan. You’re like, Oh, that’s what it, that’s that one thing.
It wasn’t the five or six other things that will probably go wrong next. It’s that one thing that was wrong now. So, so we want people who have not been doing this for a very long time, but who at least have the wherewithal to know some stuff up front.
Right. Like, I don’t want anyone to ask me like, how do I get an execution plan? You know, how is query formed? Uh, what’s the difference between a clustered and a nonclustered index? I want people who have like some meat on their bones, but I don’t want people who are like up on stage flexing.
Right. I want like some people who have just like kind of got a little bit out of it. So, and I want to know what’s their pain. Do they need to, are they, do they have a tough time reading query plans?
Um, understanding what’s wrong with way, uh, query, ha ha ha ha ha queries written.
Oh man. I buffed that one, huh? designing indexes. Um, like what, what, what, what pain points do they have?
What are they, what are they currently just struggling with? So think back to when you were like a year or two into performance tuning, what kind of stuff, um, what kind of stuff were you just befuddled by?
Okay. Identifying the real body in the bottleneck. Okay. Uh, I find it difficult to find out what I should expect as performances for a query. Parallel.
Ha ha ha ha. Coyote McD, a lot of people are still befuddled, flummoxed, and perplexed by a parallelism as we have recently learned. It’ll be, actually, no, let’s go find it.
Let’s go see where things are at. So, um, my dear friend, Paul White has, has a Twitter poll. Has a Twitter poll.
And if I go search through here a little bit, I will find the Twitter poll. It’s in here somewhere.
There we go. So if you’re on Twitter, I highly suggest that in the next three hours or so, you go and answer this poll.
The poll is a, it’s a good question. Some replies were hidden by the tweet. Ha ha ha.
Good for you. So the answer, or rather the question posed by Mr. White, for scientific purposes. A row mode parallel query runs at max.4 on a SQL Server, 2005 to 2019 instance with eight total cores.
What is the maximum number of threads that can be running concurrently for the query? Notice we’re not saying schedulers or cores. We’re not saying CPU, the maximum number of threads that can be running concurrently for the query.
Oh, Michael, I’m not going to say if you’re, if you’re right, wrong, or anywhere in between.
I am going to say that you are a very, very smart person. And that if more people listen to you, more people would, would be smarter too. He says resource usage versus query speed.
I know that you didn’t say cost, but, you know, resource usage is interesting because what if, so here’s, here’s an example.
What if you have a query that uses one second of CPU, uh, and runs serially? So that, that every time that query runs, it takes one second.
Now let’s say you have, you tune that query and it goes parallel. It now runs at dot four. So it now uses four seconds of CPU, but it runs for 250 milliseconds.
In this case, we had perfect parallelism. Everything teamed up. Gene Omdahl stretched out in his grave, put his arms up and screamed, we did it.
I’m not sure if Gene Omdahl is dead. It just had a good visual to me there. Zombie Gene Omdahl, like we did it. I’m sorry if you’re not dead, Gene.
I apologize. So you used four times the amount of CPU to get the query to be four times as fast. You used, you used more resources, but the end user gets the result faster.
Did you tune the query or not? Did you do better? Is the query better? Can you, is there, is there a, is there a serial plan for that query? That would be 250 milliseconds.
This is, these, see, when it comes to resource usage, it’s a tough thing to gauge whether resource usage has made a query better or worse. The same thing goes for reads too.
Same thing goes for reads. Same thing goes for reads. You can, you can, I have tuned queries, I swear to you, where I have ended up doing more reads, but the query has been much, much faster.
It’s a, it’s a real thing. Kalil says, depends on the query and how many branch. Well, go vote. You have, the link is in chat. You can go vote.
You can, you can tell Paul what you think about his question. So that’s interesting though.
So we have some things, some things in here we have to add. So we had some stuff. Identifying bottlenecks.
Parallelism. Resource usage. By queries. Let’s see.
So what else? What other, what other pain points might people be struggling with in their first year or two of query tuning? Maybe, well, we have designing indexes.
Let’s just, let’s add what’s a good, what’s a good index. Making CTE faster. That’s a good one. Parameterization.
Arthur. Holy smokes. Man, is that, is that, so, I’m going to ask you a tough question because you’re a smart person, Arthur.
How would you teach beginner people about parameterization? Like, like what would be your end goal? Michael says when there are too many indexes.
Too many indexes. That’s a good one too. Because too many indexes can really, really cause things to barf up in the wrong way. And they really cause things to go down the wrong pipe.
So having too many indexes is probably a good thing to identify. I’d be with you on that. I’d be with you on that.
Three most common. Ad hoc, prepared, and procs. Here we go. Prepared and procs.
And so, when you teach them about parameterization, do you also go into forced parameterization? Do you go into, oops, that didn’t, that didn’t go well.
Let’s, let’s scoot that over a second. Parameter snapping, things like that. Maybe dynamic SQL. Ooh la la.
I love the sound. That. So, what about dynamic SQL? What about dynamic SQL? Would you, would you, would you want, you, you have wanted your past just starting out with SQL Server stuff to learn?
Would it be, you know, staying safe by, staying safe, no SQL injection, when to use it.
So, I guess we, we already have, oh, staying safe, when to use it.
So, it’s, you know, it’s funny how much the, the parameterization thing, and the dynamic SQL thing, dynamic SQL thing, come into, come into play together.
Right? So, let’s actually make this, a topic up here. Why didn’t you do what I said to do? You’re very mean to me, Microsoft Word.
So, maybe we’ll, take designing indexes out of there. And we’ll keep, what’s a good index, when there are too many, well, you know it’s about indexes now, so we don’t have to keep that in there.
So, let’s see here. Let’s call this, query, anti, patterns, and what, and stuff that might fall into, this.
So, it’s interesting you say deadlocksly, because, are deadlocks a performance problem? Or, are deadlocks a logic problem? Are deadlocks, well, see, and we talked about this earlier.
So, locking and blocking, are they performance issues, or are they concurrency issues? If I wanted to teach someone, if I wanted to do a day of concurrency, I would be all game, to teach people about locking, blocking, and deadlocks.
I would be all, I would be all about that. But, I’d have a tough time, covering, the amount of ground, that I’d want to cover, with performance tuning, and also getting to locking, and deadlocks.
When it all goes crazy, with triggers and firing keys. So, you know, and that’s, that’s a funny one too. Because with foreign keys, in general, not always, but in general, as long as, you have, pretty good, indexes, to support your foreign keys, then you’re in good shape.
The trouble with triggers, the trouble with triggers, is that, people, are going to do, dumb things, inside of triggers, all the time.
If I, if I were to, try to tell you about, or try to show you, the triggers I’ve seen in my life, where people have written, applications, inside of triggers, that run to account, for like, a decade of business logic, when a single row, gets inserted, not only would you not believe me, but we’d have a hard time, like, tuning that trigger.
People do some real bad things. CLR triggers. No, I don’t, I don’t do CLR much, because I’m not smart enough, to use C sharp.
So, CLR, CLR, well, it seems like a fine thing, and I’ve, I’ve bought books on C sharp, I have them, I’ve started to read them, and you know what always happens? I start typing, and, I, I, I fall over.
I fall over. I just, you know what it is, I think it is, is that I have not had, I have not had, a good reason, to, or rather, I have not had a good application, for CLR in SQL Server, at least one that didn’t already, have a solution to it.
So, like, recently, my dear friend Josh, helped me, write a, a, a CLR utility, to take, all the numbers, out of a string, or all the string, all those, like, alphanumerics, out of a string, or something like that, and like, he was very smart, and good about that, he did it very quickly.
If I were to try to do that, I would have beefed on that thing, for days, probably come up with something, that, like, didn’t even compile, maybe if it compiled, the results would be wrong, I just haven’t had, a good application for CLR.
Is it CLR, so, anything is a bad idea, in, in the right amount, right? I don’t think, see, there’s anything necessarily wrong, with CLR triggers, I don’t necessarily think, there’s anything wrong, with some business logic, and triggers, a lot of what, a lot of what goes bad, in the trigger, is going to be, what goes bad, inside of, other user queries, someone’s going to write, a bad query, someone’s not going to, understand how to, index to make the trigger, go as fast as possible, things like that, like, people are, people are going to, like, you know, write cursors, inside triggers, use triggers, to call store procedures, triggers, one of my very first, consulting gigs, was, working with a client, who had, terrible, terrible problems, every time they, inserted to a table, really quickly, I, like, we, like, I was able to spot it, because I was running, SP who is active, every time they, inserted a row, a trigger would run, that would call a report, that would generate, three different reports, on every single, like, different, on, like, the same table, three different ways, I was able to spot that quickly, but no one else, looking at it, everyone else, was just like, boom, so, like, if there’s a, if there’s, like, a moral to this, or it’s like, sure, don’t put store procedures, that call three different reports, on a table, inside of a trigger, every time you insert a row, is that a good performance tuning topic, I don’t know, so, I think, you could take a lot, of the performance tuning stuff, and apply it, to the bad idea stuff, that people put inside of triggers, I just don’t see, how, like, targeting triggers, is going to really help, Aaron Bertrand, has a really good talk, I think it was at SQL bits, Aaron Bertrand, SQL bits, triggers, where Aaron Bertrand, talks about, some ways to write, more effective triggers, I’m going to close that window, before the video starts playing, but I’m going to stick the link, into chat for you there, so, Aaron Bertrand, has a good, has a good session, on writing, more effective triggers, but a lot of the stuff, that’s bad, that people do, inside of triggers, is bad stuff, that people do everywhere, you know, they’ll put the, the entire content, of the trigger, inside of a transaction, they’ll, you know, you know, call cursors, and loops, and iterate over things, and you know, and like, more understand, how to tune the queries, or the indexes, that go inside the trigger, so I’m like, I’m like, I just don’t think triggers, are like that appealing, of a subject overall, I would rather have people, be able to, learn as much as they can, about query tuning, and be able to apply it, to things that they see, inside of those triggers, to make those triggers, go faster, so when people want to apply, 10 years of business logic, it happens as quickly, as possible, so let’s think about, some other stuff, so we have, stuff about query plans, we have stuff about, query anti-patterns, some stuff that we can put in there, off the top of our heads, it might be, table variables, might be, functions, might be, sargability, might be, implicit, conversion, what are some other things, that we might see, as a query anti-pattern, spiritualizes, that’s something you can put in a class, the good, the bad, and the ugly, I don’t know what you mean, I don’t know what you mean by that, clarify, and I will answer, CTE, yes, well CTE, we know they’re not magic, with all that, CTE, let’s see, what are some other things, that we could stick in there, wait stats, so we, I talked about, why I stay away from wait stats, earlier, you showed up a little late, I’m not going to, talk about it all again, but wait stats, are just not that interesting, to me when it comes to, tuning a single query, wait stats are more of a, server tuning thing, Bosco says, nesting store procedures, again, if you nest, nest store procedures, that’s totally fine, there are actually, very very valid reasons, to nest store procedures, again, what I’d rather cover, is, you know, rather than like, something like that, I’d rather cover, making the code, inside of those, nested store procedures, as fast as possible, so that people can, tune those store procedures, to go so fast, that no one cares, that they’re nested, right, like I see, like I see what you’re getting at, but you know, nesting store procedures, to me, is a good choice sometimes, I’ve actually solved, a lot of problems with that, let’s see, Spare Deli says, I guess you do that already, similar to what you discussed, about triggers, examples of the, this is ugly, this is the bad, and then the good, yeah, so, sure, but you know, again, the triggers are going to be, T-SQL anyway, right, the triggers are going to have, queries in them, the triggers are going to, need to be tuned, in certain ways, so it doesn’t matter, that the code isn’t a trigger, what matters is people, being able to like, get the query plan, look at the text of the trigger, see what indexes were involved, and then start to solve problems, from there, but learning by example, is huge to me, right, because if, like learning by example, is I think the best way, to learn, right, if like, like if, if it’s just a bunch of theory, then, people, people, people leave kind of empty handed, if it’s just all theory, people don’t have concrete examples, of, when things are bad, how to know that they’re bad, how to fix them, stuff like that, then like, what do people really walk away with, more guesses, right, more, more things that they’re not sure about, right, if you give them, if you give them a, a steps, to solve a problem, that’s a, that’s a powerful, powerful thing, teach them how to fish, as they say, right, teach them how to fish, all right, so let’s see, what are some other query, anti-patterns, that we can maybe put in there, let’s see, curious, curious, curious what else, we could maybe, put inside of there, oh, we know what’s a good one, I can’t believe I didn’t think about that, local variables, okay, so I think that’s a pretty good list, so when we say, identifying bottlenecks, maybe we should put, identifying bottlenecks, up under reading query plans, because that’s probably, where we’re going to identify, the bottleneck, that’s like the most reasonable place, to identify a bottleneck, is looking in the query plan, if you just look at a query, it might be pretty hard, to figure out, what in the query, is causing the bottleneck, one of the biggest, one of my biggest pet peeves, if I’m looking at any Q&A site, is someone posts, just the text of a query, and they’re like, I need to tune this, okay, what would you like to do with it, what’s slow about it, right, like, so like, if we’re going to identify a bottleneck, we’re probably going to need, some deeper information, that deeper information, is probably going to be, stuff that we find, in the query plan, so reading query plans, let’s take the question mark, out of there, we’re going to be identifying, bottlenecks, let’s see, go, it says, put UI logic in query, ouch, that is no good, so one crazy thing, that I saw recently, was someone, had, a table, with, a, a binary column in it, and that binary column, and that binary column, could be converted to XML, and the XML contained, the entirety, of each individual user’s, user settings, application logic, things that they had customized, about their application, and, every time someone logged in, they had to go through this table, convert, their row, from, var binary, to XML, and then, search the XML, for different things, it was, one of the ugliest things, I’ve ever seen in my life, it was like, like, just, like, what were those, what happened with your developers, that they did that, the worst part is, that they, they, they fancied themselves, to be X query experts, but they were casting their XML, to Envarkar, and just searching things, as it, as like a SQL blob, and I was just like, bless your little hearts, bless your little hearts, so, let’s see, reading query plans, identifying bottlenecks, query anti-patterns, like table variables, functions, archibility, and plus diversity, local variables, parallelism, alright, so, Coyote McD, if you are still here, what about parallelism, would you want your one, or two year, into SQL self, to learn?
Let’s see, good tables, and normalization, so, good tables, and normalization, is certainly, a, a performance topic, it’s very hard, to get people, to make changes, to table structure, there are, there have been, many, many, many, many, many times, in my consulting career, when I’ve tried, to tell people, well, look, it’s going to be, really hard for you, to, to get the kind of performance, you want, unless you, normalize stuff out, like this one, big wide table, you have, is giving you, a really hard time, within that table, we have a bunch of, groups of columns, that would actually, they’re actually sort of, identify, themselves, as tables, like you might have, columns with a bunch, of prefixes, like client name, client address, client phone, and you might have, a bunch of, of, columns that identify, themselves, as, like things, that just sort of, belong together, like phone one, phone two, phone three, phone four, phone five, things like that, like you might have, those sort of, self identifying tables, with inside, like inside of your tables, and that’s, that’s an okay thing, to tell people about, but that’s a hard thing, to get people to change, it might help them, the next time, they start a project, from scratch, but it’s really hard, for them to get, to change their application, or change their like, table design, and then change their application, to work with the table design, even if you give them hints, like, well you know, you could change this, and then use like a view, that has like the join in it, to sort of do things, it’s, it’s not, it’s not an easy undertaking, there are a lot of gutches in there, so good, good tables, and normalization, sure, but I have about, five minutes worth of things, to say about that, and you just heard it, let’s see, what’s going on here, why repartition streams in there, and why ordering is bad, with parallelism, so coyote mcd, that’s stuff that, you would want yourself to know, after one or two years, of learning about, SQL Server performance, that’s, that’s a tough couple things, for people, like, like if I started talking about, like, exchange spills, or parallel, like, interquery parallel deadlocks, to people who have been working, with SQL Server, for a year or two, I think that, I don’t think that, they would be able to make, heads or tails of it, it would be like, a scare quote, right, it would be like, one of those old movies, about pot, where someone jumps out a window, like, and, and, and the other thing is, if I tell them about that, you know what they’re going to do, they’re going to hate parallelism, forever, they’re not going to trust parallel, query, every time they see a parallel query, they’re going to be like, oh god, is it doing that thing, that guy told me about that one time, is it spilling, what’s going on, maybe I was a little advanced, at one to two years, yeah, yeah, so, you’re, you’re a smart, you’re a smart fella, you’ve, and you’ve, and you’ve hung around, smart fellas, and you’ve invested the amount of time, that would, that would certainly get you, um, past where most people would be, um, uh, but, I think, it would be tough, tough to sell that to, someone starting up, so, Khalil Jamil says compression, sure, so, what about compression, we have row compression, and we have page compression, what kind of stuff, would you want to learn about it, so, let’s see, uh, let’s take these out for now, well, you know, let’s move these a little bit, because we have some questions about these, I’m going to figure these things out, let’s go, X, U, and, and we’ll add compression to the list, and so, what about compression would be interesting to you, for anyone else, for anyone else out there, like, what sort of, if you have any ideas about, like, what your one to two year into SQL Server self, would be into, about parallelism, resource usage by queries, or compression, throw it into chat, we can, we can try to figure this out together, try to figure out what kind of stuff, you might be interested in, this is all stuff I’m game to go into, it’s just, I want to make sure that I’m, I’m going down the right path, for what people, for what would, what would really bake people’s noodles, what would get you going, what would make you, happy to see, be taught, all right, got kind of quiet there, all right, so I think we have a pretty good list of topics, right, so what’s their pain, all of these things, it’s a challenge, knowing what you don’t know, yeah, yeah, it is a challenge, knowing what you don’t know, but it’s, it’s also a challenge, trying to teach you, what you need to know, you know, you, you know, like, just maybe, the thing that you need to know about parallelism, is, whether it’s good or bad, if you, if it’s something you should worry about, like, what it is, what it does, you know, like, or maybe, what you need to know about resource, which is by queries, is this like, like, like, is that, is, is that something that you should be concerned about, is, like, do, do, will queries that use more resources go slower, for compression, it’s, what, like, what kind of compression should I use, I mean, that’s pretty well documented, there aren’t a ton of gutches with compression, I sort of like compression, I just don’t see it get used a lot, the other thing about compression, is it just hasn’t changed much, since like, SQL Server 2008 R2 or so, so like, you know, it’s, it’s another one where like, if I’m going to teach it, I need something very specific to teach people about, you know, like, like, really, it’s, it’s sort of a, it’s like a five minute statement, in a lot of ways, it’s like, compression, it’s good because, this, you should use row compression when, you have fairly unique data, you should use page compression when you have less unique data, I mean, it’s just like, you know, like, stuff that you can just get out of the way pretty quickly, it might not demo well, and it might not be anything that people need to know about, Ken McT says, the very basics of what the optimizer does, so, hmm, okay, so let’s see, let’s see, let’s go back to here, the basics of what the optimizer does, he says, I would have liked something about how to measure changes you make in a better way than just watching the timer at the bottom right of SSMS, so would that go under resource usage, and how to measure changes, uh, yeah, there we go, so parallelism, uh, so let’s just call that, uh, how to set settings, that might be a good one, that might be, uh, that might be close enough, and we’ll, we know what the settings are, we don’t have to worry about that, we know we’re not talking about resource governor, Kendra didn’t show up, because I, apparently I’m not talking about resource governor, so Kendra didn’t show, I was very hurt by that, I’m kidding, I think it’s just, Kendra’s probably just drunk on a couch somewhere, I don’t blame Kendra, it is that time, it is that time, when you’re in the UK, okay, it is that time, it is that time, we’re not talking about, the basics, of, the optimizer, so, Coyote McD, it’s a good suggestion, but I want to ask you, what are optimizer basics, if you, if you had to think about, optimizer basics, would it be, um, you know, uh, optimizer assumptions, like the cold cache, uh, that the data exists, that data is independent, stuff like that, uh, would it be, um, you know, figuring out query plans, or like, like maybe optimizer tricks, like, uh, like simplification, or, you know, contradiction detection, or stuff like that, uh, collapsing sub queries, or expressions, like what kind of, what kind of optimizer, or what would you consider, to be basics, of the optimizer, that would be, or maybe like, uh, optimizer has rules, stuff like that, uh, query plan reuse, so query plan reuse, I would put that up, under parameterization, uh, so I would put that up here, and plan reuse, so that would be a good topic, under parameterization, because that is, that is very, that is very, very good, and that definitely falls into, like a pretty big wheelhouse, of, of subjects, and topics, that you can talk about, with people, that will, like, boggle, and make them angry, and be like, why does it do that, like, who does, design this thing, why are they so great, like, what are they thinking, so yeah, that’s definitely a good one, that we can, um, we can put in there, I would add that in there, uh, has something about statistics, been put down yet, no, nothing about statistics, statistics, but, what about statistics, what’s something about statistics, would you want to learn, how to look at them, uh, how to figure out, if they’re good or bad, you know, there’s like, the ascending key problem, that got, that got kind of fixed, with SQL Server, with the new cardinality estimator, it’s a kind of fixed, but like, what about, like, like old statistics, when to update statistics, because if we’re talking about, when to update statistics, that’s a maintenance thing, oh, it’s off, but I never grasp, the service broker, how to use it, why be better than the, yeah, it’s service brokers, I mean, Remus Rosanu, is one of the finest people, you may never meet, in your life, I still don’t know, why service broker, came to be, um, my old, my old co-worker, Jeremiah, once used service broker, to asynchronously, shrink transaction logs, people often have to, hunt for reasons, to use service broker, Michael Erickson says, I guess it is hard, to understand parameter sniffing, without basic statistics knowledge, so that’s a, that’s an interesting one, and that would kind of, tie into, what happens, with, uh, stats and local variables, uh, maybe, this would also, have something about, stats in it, sagability would certainly, have something about, stats in it, and so would implicit conversion, there would definitely be, stuff about stats in there, and then parameterization, this would certainly, have stuff about, stats in it, because you, you know, when you, when you’re learning about, uh, when you’re learning about, you know, why SQL Server chooses, different plans, then statistics are a big part of that, so Lisa says, let me rephrase that, estimations and how to troubleshoot, when they are out by a lot, you mean aside from updating statistics, statistics.
So there’s, there’s a lot that goes into that, so when, when, so when cardinality estimates are terribly wrong, you know, you have to go back and you kind of have to look at, is it one of these problems?
Did I not update statistics recently? Um, or, did I write my predicate, or my join in a way, that SQL Server is unable to make a good guess?
The other thing that’s a big, the other thing that’s big there, is figuring out when, uh, when inaccurate statistics guesses are actually a problem.
I see questions posted quite a bit about, statistics were right, but everything else was wrong, or, statistics were wrong, but like, and I have, here’s my query plan, how do I fix it?
But the plan is still remarkably fast. So, uh, I think when it comes to statistics in general, rather than have a section on statistics, I would rather weave statistics in, to a lot of the different things I teach, because you can, you can, you can, you can really, I think you can, you can drive home how important statistics can be, when they’re, like when they cause problems, and when they don’t.
So, I would probably want to weave that in. okay, let me say, maybe something about the optimize forehand. All right, so, would I put that under, you know what, I would, I would want to have that under local variables, since optimize for, since optimize for, does just about the same thing there.
So, I would have optimize for, alongside local variables. So, well, optimize for unknown, right? so, let’s make sure that’s specific. The optimize for unknown, would be, would certainly fall into the local variable category.
I don’t, but, you know, that’s something that I would want to be, tie into there, because I don’t want people to walk away from this, with a question like, but what’s the difference between, you know, optimize for unknown, and a local variable.
And the same reason that, you know, you see the question all the time, people asking, you know, like, what’s the difference between, no lock, and, read, uncommitted, right?
Like, that, what’s the difference between, same thing, the difference between local variables, and optimize for unknown, it’s the same damn thing. He says, I guess transactions would fall under concurrency. So, when you’re talking about transactions, when you’re talking about, begin, begin tran, and commit or roll back, everything that happens within that, is subject to query tuning, right?
And we know they’re dangerous, because they increase the chance of blocking. If you update, if you like, say, begin tran, update a single row, then go do, like, go off on some crazy meandering path of doing things, and then finally roll back or commit way down here.
Well, if all of this big meandering path is fast, then that, then that one lock you took up here, that was done, say, 200 milliseconds, 500 milliseconds later, probably not the end of the world.
But, if you take that one update, and then this big meandering path is like, two to five seconds, then that lock becomes more interesting.
So, when it comes to tuning transactions, tuning transactions is more about tuning everything that happens within the transaction. Same thing with triggers, right? Same thing with functions, same thing with store procedures, same thing with anything that contains code in SQL Server.
However, if you have, if you have a whole bunch of stuff that’s slow between a begin tran and a commit or roll back, we can focus on tuning the stuff that’s slow in there. You know, sure, there’s, there, there might be times when you can move the begin tran to like some other part of the code where it really matters.
But, otherwise, what do you tune about a transaction? You tune the underlying queries and indexes, right?
You don’t go in, you don’t, you don’t, there’s like no, like, like hint, and there’s no like option for begin tran that makes things faster, right? The transactions generally would, would be a concurrency thing.
Not that concurrency has nothing to do with performance. It’s just that concurrency is such a topic unto itself with locking, blocking, deadlocks, transactions, things like that, that it’s really tough to sort of, you know, like stick into a performance tuning talk easily.
So we have a good list of things here, right? We have, we have a few different titles up here. And that’s, that’s good.
That’s good stuff. So let’s start on this page. Let’s start on this page. And let’s say, what is our abstract going to be? So let’s just, let’s not say you’re a DBA or developer.
Let’s, let’s take titles out of it. Right? And let’s say something like, you’re new to SQL Server.
And your job is to, let’s say, fix performance problems, but you don’t know where to start.
You’ve been looking at queries and query plans. And, let’s see.
queries, query plans. And let’s just say something.
We’ll, we’ll fill that in later. And something indexes for a year or two, but it’s still not making a lot of sense. Logs, read, give, bury.
Nice. Oh, stop it.
Or if it applies to you, use UUID as a primary key. I’m totally fine with that. I’m just happy if you have a primary key. I’m happy if you have tried so hard to design things properly, that you have a GUID as a primary key.
There are ways to like not have it be so painful. Like if you make your primary key, a nonclustered index, or if you use a, like a sequentially generated GUID, you can have far fewer problems with GUIDs as a primary key.
But most of the time, when I see someone has a primary key, I’m like, you know what? You tried your best. You tried, you tried hard.
And I understand why, you know what? You know, when you think about numbers in SQL Server, you think about ints and big ints, what do they have that GUIDs don’t have? They have an end.
There’s a, there’s a finite number of those numbers until you have reached the end of those numbers. GUIDs, wide open baby.
You can have GUIDs go on forever and probably be unique. Numbers, finite. Even if you start negative and go positive, they are still finite.
finite. Granted, big ints take a long time to go from the negative end to the positive end and hit both sides of that limit. But I have faith that with big enough data, with real big data, you could do it.
All right. Okay. So I’m going to take a quick break and I will be back and we will work more in the middle of the year.
Bye. Bye. Bye. Bye. Bye.
Thank you. You know I’m home. You know I’m home.
Where else am I going to be? Leave it. It’s fine. All right. So let’s finish up strong. We’ll go until the hour and we’ll finish up writing this abstract here. The blog is where you give you a very specific advice and you’re not sure if it applies to you or it’s even the problem.
So using some of these advice. So using some of these advice, beyond that, you’re not sure how to measure if your changes are, let’s say, are working. Cool.
Cool. So we got that part. All right. And we’ll say something like, you know, like in this day long, right? So let’s see.
Join me for a full day. All right. It is going to be a full day, right? You know what? I don’t like the way that sounds. You know what I don’t like about that? It starts with join.
Join. You know what bums me out about join? Too punny. It’s too punny for me. Much like LaCroix bubbles are too big and soft for me.
And only Canada Dry bubbles satisfy me. Things that are too punny don’t go over well with me. So in this full day, I don’t know.
Let’s just say something funny in here. Performance tuning extravaganza. You’ll learn all of the stuff.
I’ll get to that in a second. Okay. You’ll learn about all the most common anti-patterns in T-SQL. Oh, I messed that up terribly.
T-SQL querying and indexing. How to spot them. Using.
Oh, come on. I was so close. Using execution plans. Ah, here we go. All right.
That’s a full enough thought. In this full day. Performance tuning extravaganza. You’ll learn about all the most common anti-patterns. In T-SQL querying and indexing. And how to spot them using execution plans.
You’ll also. Leave. Knowing.
The. Let’s see here. What could we call. Some of these things. Knowing.
Why. Why they cause. The problems that they do. And. How you can. Solve them.
Quickly. And. Painlessly. Pain points. Pain points indeed. So I don’t like to say pain points too much.
Because I don’t want. I don’t want people. I want people to. To come to me.
Knowing that they have them. Without me having to point them out. Getting like. Oh. That looks like it hurts. Oh. That looks like it hurts. Oh. How’d you do that? So. Let’s see here.
Let’s see here. So we could add in some specific stuff now. Right.
So. You’ll. Learn. Let’s see. When. Which. Temporary. Object. To.
Actually. No. Let’s start. We’ll get to that in a minute. You’ll learn. How to. Write. Queries. That. Will. Never be.
Slow. I mean. That sounds good. But I don’t know if that’s. I don’t know if that’s totally true. You’ll learn how to write queries. You know what?
Screw it. We’re going to stick with that. It’ll never. Be slow. We have a lot of you’ll learn in here. You know. There’s a lot of you’ll learns. We have a lot of.
You have too many you’ll learns. Do we have. How many do we have? Not that many. It is a bold statement. But I’m a bold human being. I’m like barbecue sauce Lee.
Bold. And tangy. Alright.
That’s all I got. I’m not bald. I’m doing okay. I’m doing okay. So let’s see. Let’s read it a little. You’re new to SQL Server and your job is to fix performance problems. Ooh.
You know what we should do here? Your job more and more is to fix performance problems. But you don’t know where to start.
You’ve been looking at queries and query plans and puzzling over indexes for a year or two. But it’s still not making a lot of sense. The blogs you read give very specific advice.
And you’re not sure if it applies to you or if it’s a problem. No. I don’t like this one. I don’t like that one. Beyond that. You’re not even sure how to measure if your changes are working or even the right thing to do. There we go.
That can be a big assumption. But the nice thing there. The nice thing there.
is if they leave with the materials, they have no excuse not to learn it eventually. Even if they don’t learn it that day, they’ll bring it home and they’ll learn it eventually. So it’s bold.
So you’ll learn is like future predictive. You’ll learn at some point in the future. Might not be today. Might not be tomorrow. But at some point, you will open up that thing that I gave you.
And you’ll say, ah. And you’ll have learned it. So you will learn. You’ll learn. It’s not like saying, you’ll pay.
I would even say if they have the concept that they have no excuse to learn. Yay! I just don’t want to put that kind of thing on people. Like, look, you have no excuse.
It’s not like my mother vacuuming outside my door when I had a hangover when I was a kid. No excuse. Oh, not for the doc.
Yes, not for the doc indeed. So let’s see here. Pretty happy with this. You’ve been looking at queries. You’ve been pulling around the air to have something on a sense. Beyond that, you’re not even sure how to measure if your changes are working. Sorry, my printer just started spazzing out for some reason.
In this full day, performance, tuning, extravaganza, ganza, ganza, ganza, you’ll learn about all the most common anti-patterns in T-SQL queering and indexing. And how to spot them using execution plans. No, we’ll keep that all together.
You also leave knowing why they cause the problems that they do and how you can solve them quickly and painlessly. If you want to… If you want to…
The… Knowledge… And… Confidence…
To tune queries… So they’ll never be slow again… This… Is… If anyone…
Who’s thinking about attending… Watches this video and sees all the typos I’m making… They might change their mind. I found the main barrier for me is not being able to learn about something is my laziness. No excuse other than that.
Well… Lee… I understand that fully. If you want to gain the knowledge and confidence to tune queries… I’ll never be slow again… This is… The…
The what? This is… The training… You… Need. So let’s go back… Let’s see here…
Let’s see… Training you need… All these in one day…
So… No… I… I asked… I asked the attendees… For their ideas. There’s a lot of this stuff that you can…
You can cover… In a day. I would probably cut the line about here. Because I think…
A lot of… So… It’s a good… That’s a good question, Paranoid DBA. Okay… And… If you think about… What’s being talked about here… As…
Like… Come on… Man… Come on back… Where’d you go? Why are you not… Whatever… Screw this… So if you think about… Teaching each one of these concepts individually…
Yes… That is a big… Crazy… Wide open… Day of learning… Right?
You can think about it like that… But… If you tie these all in together… If you tie these things in together… So that…
When they… They learn about… Sargability… They also learn about implicit conversion… And like… You can… You can tie a lot of these subjects in… So that you… You kind of put… You put more of these pieces together into a puzzle…
Spirit of Lies says… The Friday session had a lot of these topics… Minus blocking… Yeah… So… Yes… But… This would be like… Beginner stuff…
So this would be like… Very… Like… Early on entry level stuff… When you’re… When you’re… Like… As you progress through performance tuning… The first thing you have to learn is…
Like… You have to learn the fundamentals of these things… And then as you get more advanced… You can… You can like… You know… You get more…
You get… As you get more advanced… You can apply them to more advanced things… So… What I’ve found over the course of my life performance tuning… Is that… A lot of the reasons why queries are slow…
Hasn’t changed a lot… But there are different audiences… And those different audiences have different strengths… Different weaknesses…
And someone just walking into query tuning… Who needs to know… Like… Just the right thing to do… They might not… They might not need to know… Like…
Lots of super advanced things that you can do with these things… But they need to know what the right thing to do is… Right? They need that basic fundamental knowledge… Of like…
Why do table variables give me a weird plan? Right? What is sargability? Well… Stuff like that… Are CTE better than temp tables? Why…
Like… How come when I use a local variable… This execution plan gets weird on me? You know… Like… If I have a query that’s going slow… How do I know if it has a good index? Things like that… The more advanced stuff…
Is just like… The next stage of… Like… You already understand what an implicit conversion is… We don’t need to talk about that… You know…
What you need to know is like… You know… You’re looking at an execution plan… And… It has a spool in it… And you need to know… Why that spool is there…
And how you can fix that spool… So you’ve gotten to the point where… You kind of know this basic stuff… But getting to the next point… Paranoid D.U.J. says… But that changes in each version of SQL…
No, it doesn’t! It sort of changed for some things in SQL Server 2019… And it didn’t even change in a complete… And like…
Overwhelmingly good way… It does not change in each version of SQL… Implicit conversion has been the same… CTE have been the same… The problems with local variables have been the same… The problem with sargability have been the same…
The problem with functions have been the same… All of these problems have been the same… With only a few changes in SQL Server 2019… And if you think that there are a lot of people…
Who are one to two years into their SQL Server journey… Who are going to be coming to training… Let’s say in the next two to three… Maybe six months… Who are all fully fledged using SQL Server 2019…
In production… You are out of your mind… But most of these things have not changed… With every version of SQL Server…
What’s a good index has not changed… Parameterization has not changed… Parameter sniffing has not changed… How to use dynamic SQL properly has not changed… None of these things have changed…
With the SQL Server… Lee still has SQL Server 2008 instances… Lee no wonder you want a different job… I hope that works out soon for you… So let’s see here…
Let’s finish this up… And let’s get on out of here… It’s been a while… Me babbling on and on to you… If you want to gain the knowledge and confidence… Toon queries so they’ll never be slow again… This is the training you need…
Let’s see here… I don’t know if I want to add anything to this… You know what I’m going to do… I’m going to save this… I’m going to save this…
This PC… I’m going to save this… I’ll save this later… What I’m going to do is save this… And I’m going to sleep on it… Free candy at the end… How about…
Um… And… You also get… Access to all my… Videos… Blah…
Blah… Blah… BING! I’m not giving away my Canada Dry Lee… Canada Dry is my favorite seltzer… It’s much better than La Croix…
Canada Dry is the best seltzer… Never going to give away my Canada Dry… You can’t take my Canada Dry…
Don’t try to… All right… So… I think we’ve done a pretty good job of getting… Getting the…
What we want to teach… Who we want to teach it to in the abstract… In there… Uh… I should tweet that… I’m too lazy to tweet that… Any vodka with it?
No… Not today… Not yet at least… Uh… It’s still… Um… You know… It’s still 3 o’clock here… And… Uh…
I don’t know… I wanted to at least get through this thing sober… Right after this… Right after this… Botsco… Sure… Let me…
Point you… To my website… Where there is… Yet another post… About local variables… Yeah…
Well that’s a bad idea isn’t it? Michael says… I think this would be good for devs that need to write queries right from the beginning… Yes… That is absolutely what I’m going for here… Um… So I want people who…
So like… Expanding a little bit on what Michael said… Because Michael brings up an excellent point… What I want… What I would say about training like this… Is…
That… When… You have… Had a… T-SQL… Application… That’s been around for a while… You most likely have a lot of bad practices in there…
SQL Server developers will show up to… Either… It’s going to be their first day on the job as a T-SQL developer… They’re not going to really be a T-SQL developer… They’re going to be a developer in some other…
Something else… And… You know… They’re going to see what you did in that code that’s bad… And… What’s going to happen is… They’re going to just keep doing that…
They’re going to keep repeating the same mistakes… They’re going to take those mistakes with them elsewhere… And… What I want to do is… Get people to the point where… What…
When they’re writing a query… They’re not making those fundamental unforced errors… They’re not continuing on that… That legacy of… Of poor T-SQL hygiene… So what Michael said is very, very…
On point with what I want to do… I want to give people the right foundational knowledge… So that… You know… They don’t get bit by a lot of… Just the… You know…
Those like… Like… Head… Like… Why performance issues… Right? That’s what I want… That’s what I want… So…
Thank you for… Hanging out with me today… While we… While we talked about… What makes a good abstract… And writing… The abstract… Also thank you very much for your ideas and suggestions… I appreciate it…
It’s nice having people… To brainstorm… With… If you… Would like to join me… Friday… 10th…
Or 24th… I have a full day of online performance tuning… The coupon code… Floating above my head… Will get you 75 bucks off… From there… If you want to get tickets…
You can head over here… And if you buy a ticket… You get free access… To all of my training… Forever and ever… You can look at… What…
My training covers… Over at that link… So… Feel free to click on those… At your leisure… If you… If this is the kind of… SQL Server content… That you enjoy watching… You know…
You can… Hit the little bell buttons… On YouTube… To like… Subscribe… Or whatever… Whatever you cool kids do these days… Same thing for Twitch… If you want to follow me on Twitch… You’ll get notified when I go live… You won’t have to depend on…
Twitter to tell you… Because… We all know how… Untrustworthy… Twitter is… So… Thanks for joining me… Uh… Come on back… I’m not…
I’m not going to be doing one tomorrow… Because it’s Saturday… And… Uh… I’ll probably end up… I’ll probably not be in good shape… For doing a live stream… Plus I think I’m about to get arrested anyway… So…
Thanks for joining me… Um… If I can get through one live stream… Without sirens… I would be so impressed… Thanks for joining me… Uh… Thanks for hanging out… And I will most likely… Uh… See you…
Uh… Next week… For… Some more live streaming goodness… Take care everyone… Stay safe… See you next time…
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
In this video, I delved into a detailed analysis of query performance and optimization in SQL Server, specifically comparing execution plans between compatibility levels 140 and 150. The primary focus was on understanding how row mode operations behave differently under these settings. As I ran the queries with varying parameters, I noticed significant differences in execution time and memory usage. Compatibility level 140 maintained a relatively quick execution, while level 150, despite using batch mode for certain operators, experienced a much slower sort operation due to single-threaded processing. This led me to explore wait statistics and memory grants more closely, highlighting the limitations of these tools in diagnosing performance issues under different execution modes.
Full Transcript
Thank you.
Welcome. Welcome, welcome, welcome. All you lovely people out there. How is everyone doing?
there are people here so you better answer me of course people started disappearing when I came on screen I guess they were disappointed I guess they were disappointed I guess I wasn’t good looking enough when I showed up I’ll have to go try a face mask or something next time throw that on on camera if you guys can hear me through this maybe this will improve if anyone out there has a Bane fetish maybe I can work with you on that no yeah Steve you were born on a pair of skis or something I’m not going to do the Bane voice that’s where things cut off I don’t do impressions I’m not good at impressions never have been you’re at a ski condo now how does a guy who runs a free free message board end up at a ski condo gotta figure that one out I’m gonna start a free message board wife is successful well she’s gotta be supporting a bum like you lazing about in Hawaiian shirts all day do I have any update to my plans on smoking cigarettes in a French graveyard no just not soon enough not soon enough not soon enough there’s no such thing as soon enough when it comes to that is there every every second you wait is just too long it’s too long sooner the better though still trying to get that all figured out suppose I could call an immigration lawyer right still like look here’s what I do here’s what I want to do here’s why I can only do this in France because you’re the only place that has the proper brand of cigarettes and French graveyards and all I want to do is is work from home not bother anybody and contribute a lot of money to local bars and restaurants and and tobacco shops that’s it I will be an ideal French citizen I mean I’ll be quiet my kids not so much I’ll be quiet but I think I think that I think I would like aside from like being probably like mentally incapable of learning French I would I would be an ideal French citizen whole travel ban thing might have yeah you know that’s a little that’s a little unfortunate but you know hopefully a small travel ban now will result in less of a travel ban in the future or at least like let me just get there and then ban travel let me get there and then travel screw it I’ll figure out I’ll figure out how to SQL Server in French I’m gonna you know what that’s how you know what that’s how I’ll learn French that’s how I’ll learn French I’m gonna learn it from SQL Server error messages so in SQL Server there’s a view right we can do oops from sys.messages and it’s oops I’m gonna start off hitting the right button it’s usually a good good idea and if we look in sys.messages we’ll see all sorts of I mean there’s all sorts of text over here from the messages that you can get from SQL Server right so what’s does anyone know the language ID for French offhand I’m fine go look it up go figure out SQL Server language ID French 1036 ooh la la as the French say so let’s see where oops Steve can you please fix SQL prompt how would I have a with there where language ID equals 1036 run this let’s get oh this is how I’m gonna learn French check this out I have all of the SQL Server error messages in French now you need text to speech I do I do I need text to speech and speech to text because I find that one of the biggest one of the biggest hurdles I have to writing is typos and and like I’m like I think I spend more time going back and fixing things than I do actually writing Duolingo my wife does my wife has been doing Duolingo in French with French specifically for like two years now and Duolingo is still giving her nonsense stuff like the like the men are rich and calm or like the men ate all the strawberries or like the cat is black it’s just like the same stuff like like like like just going like she’s regular with it too every single day and just like nothing like like no real advancement after a certain point so I’m gonna I’m gonna learn it from SQL Server error messages and I’m gonna blow her out of the water the prefix date okay so let’s see the colon prefix does not correspond with the table name okay so apparently what I need to do is figure out a way to have the language IDs alternate and what I’ll do is let’s see in six and let’s say order by I’m on message ID and let’s see well you know it’ll have to be message ID and then language ID will that work no because that’s going to order that first if you just order by message ID it should give us that let’s see if that works no no it didn’t work 102 is it did I miss something did I get something terribly wrong randomly would be funny right 1033 why is language ID 10 oh duh why didn’t anyone yell at me 1036 I had that all wrong there we go now we got it now we got it see I was off by one on that off by one let’s set the whole thing off all right now we got it this is great warning so advertisement anyone help me with the pronunciation there note the error in time and contact your system administrator no the error and the error in time and contract your system administrator well no you see numerically I was off by one but physically I was off on the keyboard by one by 80 I was off numerically by 80 on the keyboard I was off by one so I wanted 1036 and I ended up with what 2016 so I was off by one on the left hand that just screwed everything up screwed up everything but yeah this is great so I figured I have a plan now I have a plan column prefix does not match with a this is great yes I’m going to contact everybody query not allowed and wait for oh this is awesome this is truly awesome oh this is going to be fun I have a plan now I was was wondering how I was going to spend my summer vacation and now I know how I’m going to spend my summer vacation this is great so let’s talk about this query tuning thing now I’ve got a store procedure with two statements in it I’m going to run one at compat level 140 you should sort by language ID no if I sort by language ID then it’s going to be all the 103 3 first I want them to be interspersed like this ordering by message ID so that I can see the English version and then the French version now I don’t want both would screw it up because then I would have all the 103 3 first this way works message 101 message 102 message 103 if I have it by if I sort by language ID then 103 3 will sort first and then all the 103 6 will come later and I want them together so I can see the translation it’s a terrible idea Mr.
P. Shaw I’m ashamed of you ashamed of you no you’re not getting it it’s okay it’s okay all right so let’s look at this thing here right we got one query up here that’s going to run a compat level 140 one query here that’s going to run a compat level 150 and let’s go look at what happens when we execute these so just to be extra short let’s recompile and let’s get that going let’s run this run this all right we’re on we’re on to something else now go talk about order by some go talk about order with yourself I don’t want to talk about this anymore we’re on to the query tuning bits so let’s look at these two query plans they both end up pretty quick all right if you look at these this finishes very quickly and this finishes very quickly good good good we have a sort here and we have a sort here and everything is generally pretty dandy with these sorts but then if we go and run this and we look for a different number for the gap right we’re going to supply a different gap we’re going to go from 9 here to 0 here we’re going to keep post type id at 1 though and if we run this the row mode there’s going to be the compat level 140 is still going to be pretty quick but we’re going to have a real problem with compat level 150 you can see that this thing is kind of still over well that that executed it for a little while there right that gave us about 10 seconds total of execution time if we look at the query plans now this is going to be the row mode plan this is going to be the one that executed in compat level 140 and if we look at the sort it’s going to spill a little bit right now knowing what we know about row mode plans and knowing what we know about reading execution plans with these times in them this operator went for this operator ran for about 256 milliseconds and the next one ran for 1.253 milliseconds but it’s a little bit under a second because 253 there’s the 1.253 minus .256 is going to bring us to about a second because remember in row mode plans operator times are cumulative cumulative right so this is actually just running for about a second and the spill isn’t that bad spill level 2 one thread right about a little bit less than 10,000 pages ended up on disk so I’m totally okay with this this did actually pretty good considering this sort is going to continue to be in row mode because we were looking at it in compat level 140 compat level 140 doesn’t allow batch mode for rowstore compat level 150 does at least if you’re nice enough to pay for enterprise edition or smart enough to just use developer edition instead don’t tell the licensing police I said that but you know all the smart kids are doing that so now we have this section of the plan which is pretty okay but looking down here this is where things all of a sudden got bad boom boom boom boom boom boom boom boom boom boom wow I got spam thanks mr.
gamer 2018 let me update your nickname nerd what’s wrong with you jeez so this is since these two operators run in batch mode all right that’s a batch and even though the storage is row stored since this is compat level 150 we’re able to buy or we’re able to buy we’re able to batch run this in batch mode we’re able to run this in buy mode because we bought enterprise edition apparently we bought followers primes and views because we’re famous we want to be famous I wish I could get famous apparently mr.
gamer left made fun of his nickname too much but now this sort since these two operators are in batch mode right we can see a batch mode here and we can see a batch mode tooltip you weren’t working with me there we can see a batch mode here since these two things run in batch mode this is interesting right since these two things run in batch mode the times are no longer cumulative the times are per operator so this sort really did run for nine almost let’s just call it 9.3 seconds this index seek was very fast but this sort was very slow now there’s a funny quirk with sorts in batch mode it doesn’t apply here it applies to parallel sorts in batch mode where the output from them is single threaded the batch can run multi threaded but the output from a batch mode sort is single threaded unless they’re the child operator of a window aggregate we don’t have one of those here we also have a serial plan here so it doesn’t matter everything’s on one thread anyway but this single threaded batch mode operator well it’s kind of funny isn’t that kind of funny spill level 8 and it only wrote 5142 pages to disk so if we go look at the memory for these two queries this one here got about a meg of memory that’s 1024 kb so we got about a meg of memory here and with that one meg of memory we still had to spill out a little bit but we spilled out about close to 10,000 pages but this happened pretty quickly this happened in about a second the batch mode plan gets just about five and a half well let’s just call it five and a half megs of memory that’s close to 5.4 and 5.4 is pretty close to 5.5 so we’ll just stick with this so we get about a 5.5 meg memory grant here we spill out but man this operator runs for nine seconds nine seconds and it spills about half as many pages now what a lot of people will do when they start trying to tune queries is they might care very much about wait stats newer versions of SQL server have wait stats and query plans which can sometimes be helpful you can sometimes find things in there for the query that runs quickly though well we have about 260 milliseconds of IO completion right that’s fine for a query that ran for a second we don’t know what we did for the other second but we know that we had 260 milliseconds of IO completion that’s the only weight that’s stored in this query plan for the query that runs in batch mode this gets even more curious if go to the properties over here and we look at weight stats well we only have 24 milliseconds of one weight reserved memory allocation ext this is not a terribly helpful weight see one of the real dark sides of some of the things that Microsoft adds is that they decide to filter things out for you they decide what you see and what you don’t see in some of these additions to help you troubleshoot problems the thing is having that knowing that this query waited 25 milliseconds on reserved memory allocation ext is not going to help us figure out what’s wrong with this query but neither would looking at what we actually waited on so let’s look at weight stats using my store procedure sp thunderous underscore look at that look at this thunderous underscore that thing that’ll buckle the these human events and we’ll use it to look at weight stats at least as I’m slowly learning the answer to every SQL question is it depends yes but the important thing for every SQL question is knowing what it depends on because if you know what it depends on then you can solve the problem yes the answer to most things it depends but the secret is knowing what it depends on knowing those dependencies is where one gains expertise depends on what you got it you got it that’s the bumper sticker isn’t it so we’re going to use sp underscore human events we’re going to look at weight stats for this one session right so we’re going to focus this one session and we’re going to get some information out of this now the thing with these is that if we look at the weight stats for this there’s going to be just nothing in there right we didn’t generate a single thing that made us get a weight even for like the other plan in 150 we don’t have really anything of interest in here right there’s nothing about weight stats in here blah blah blah blah blah blah not fun not fun at all doesn’t really help us so let’s use sp queries to finish again all right so that first one finishes quickly we’re probably not going to see much for interesting weights there and this other one is going to execute and this one’s actually going to take a little bit longer now right that was like 9 point something seconds before it’s at 10.1 seconds now so this sort actually did a little bit more work on this one actually no it did about the same it just took longer I hate you so using sp human events we get information about query weights at three different levels right and this is because I do a whole lot of work in my store procedure to give you this data at three different levels for the entire time that it ran we had for the total weights we had 999 weights on this mysterious sleep task weight and then at the database level well the only database that was active because this is just my personal computer this is not Stack Overflow production database this is just my personal laptop so there was only one database active that was Stack Overflow 2013 but that will report that we had the 999 weights and we waited 8.2 seconds on them now the other thing that I try to break down with human events is to give you weights by query and database so we can look at things overall by database then by query and database and we get of course some information here oops I did not hit the right button so we get the query text and the query plan of the queries that generated the weights we can see there what happened to it now since this is two statements in one store procedure we unfortunately get the query plan for the whole store procedure I’m working on something to make this better but I don’t quite have it yet so I’m working on something to focus this in it’s almost there but it needs a little bit more work so we at least see the query that caused the wait since this is a plan that comes from the plan cache we don’t get the actual plan if extended events were better if extended events were a tool that Microsoft cared about us using and using happily we would be able to chain things together we would be able to say hey extended events I want you to fire off this event if this other condition meets whatever I want so let’s say that for us we cared dearly dearly near and dear to our hearts we cared well I mean I care about learning French from error messages but let’s say that we cared nearly and dearly about queries that were waiting on sleep task weights what I would like to be able to tell extended events is hey if you find a query that waits on sleep task go grab the actual execution plan for it we can’t do that together we have not extended events that far into the future we cannot chain events together we cannot chain sequences of events together and that’s a pretty big gaping hole in extended events I’m not saying profiler is any better at you can go get that magically from profiler I’m just saying if Microsoft really wanted extended events to be helpful and usable they might want to invest some time in getting people to actually use it by making it more useful I don’t know just me I’m not angling for a job as the PM of extended events or anything that would be a nightmare because it’s all XML and I’ve seen it and it’s ugly but this is one of those things where if you build it they will come Microsoft built a really crappy it was not a field of dreams it was a field of not quite maybe it is a field of nightmares because of the amount of XML so I wish I could chain things together to get something different but unfortunately if I was going to do this and get wait stats and query plans I would have to collect actual plans all the time and that wouldn’t be a lot of fun because then I’d be collecting wait stats and actual execution plans rather than being able to chain things together and be able to only get actual plans after some other extended event condition got past the filter so I have the estimated plan for the query that this sort ran for a long time but you know this is probably a pretty good lesson in and of itself how can you track just one sort you can read the documentation because it is in there there is an object name filter in there you can track just one procedure that doesn’t apply to every single one because not every single one gives you the ability to track just one procedure you can only do that if you’re tracking queries for wait stats I think you can do something I forget exactly what I wrote the documentation so I wouldn’t have to remember all this stuff but if we look at the estimated plans and this is sort of a good lesson about estimated plans general cash plans in general if I told you I had a query running for 10 seconds it would be very very difficult to ascertain if each query ran for 5 seconds or a second and another query runs for like 10 seconds you can go to my website it’s a good place to start it’s all there so if you look at these two estimated plans estimated plans lie to you estimated plans hide a lot of things estimated plans hide a lot of things because they are only estimates this is what goes in the plan cash this is what goes in the query store this is I am collecting an actual post execution plan I cannot get the level of detail that you are after if you look at a few small differences here if we look at this sort in the estimated plan we have estimates for everything we have estimates for all of these things estimated execution mode operator cost IO cost you can read all those things if we go back and look at the actual plan for it oh I have two versions of that open we don’t need two we just need one if I go back and look at the actual plan for this we get actual values we get what the query encountered when it executed for a bunch of things right we get actuals for this we get actuals for this we get well this we get the actual execution mode we get actuals for many things one set of values in here that we don’t get actuals for are costs see all those costs there’s no actual cost that gets updated at the end there’s no actual cost addition to operators to query plans where SQL server says oh I was totally off about how long this would take I was totally off about these costs my bad I’ll go fix that we don’t get that kind of honesty from SQL server all we get is SQL server saying well I estimated that if I was wrong I was wrong my bad my bad I was merely speculating but what’s important here is that when you run into a situation either where SQL server was wrong or where you have been parameter sniffed you end up with stuff like we know that this sort ran for 10 seconds but the cost is merely 1% if we were looking at this query and saying geez costs are super important let’s try to figure out where SQL server spent all the time we would look at this completely innocent index seek and say wow you are half the cost how do I make an index seek faster bad idea don’t look at costs they are lies they are lies because costs are not about your server costing is a general algorithm that has no idea about your hardware how awesome your disks are the great gobs of memory you have any of that stuff costs have nothing to do with you costing is a general algorithm that has to apply well to everybody regardless of how good or bad their hardware is it just so happens that SQL server is general across a wide variety of hardware but they are still not specific to you that’s why there is no actual costs in an execution plan SQL server doesn’t go back and correct those costs nor does it attempt to cache plans with those costs we can see that the cost for all this stuff 86% in an index dear lord we need to make that seek faster what a terrible time what a terrible thing that we have to do what a terrible thing that we are tasked with and look at the actual plan how long did this thing that cost 85% run for 0.001 milliseconds how much did this thing that cost 55% run for 0.002 milliseconds how long did this thing that cost 2% run for 1.5 seconds it gets worse down here where this thing that cost 1% runs for 9.9 seconds SQL server SQL server I wonder if all of the data in Azure if they’ll be using machine learning to correct cost estimates no because the cost estimates still have to work across a wide variety of Azure machines too I mean Azure is not one size fits all in Azure you can get a server with less than one core I think you get a hyper threaded thread in that case but you can get an Azure server with less than one core and the costing would still have to respect that you would only be able to get a serial plan for that because SQL server will say we have half a core probably round up and say we have one core probably not because even if they did that for the current gen of Azure machines think about in five years or 10 years or even in one year what different Azure machines we would have what kind of hardware might be behind them you know you start adding in like all sorts of like weird cool new features and you start adding in stuff like persistent memory and all of a sudden what do we get much much more difficult to figure out what something would cost and all that coyote McD says why do the percentages add up to more than 100% in that particular plan because SSMS is broken because costing is broken everything is broken the world trembles beneath us and we have no idea what holds it up we have no idea so yeah we have we have this thing we have this thing and we’re not really sure what’s going on but what I want to show you here is this is happening in batch mode and this is going poorly in batch mode so in the interest of full disclosure SQL server 2019 has this lovely mechanism for giving queries feedback about memory grants between executions if we run this a second time they’ll both be fast right so SQL server has adjusted the memory here we have gotten more memory on this execution and this sort no longer spills and we no longer have a big spill here the problem becomes really if we run this query a few more times then memory will eventually adjust back down not for that one but for this one the memory grant on this one is back down to 2.3 megs now and if we run this query it’s going to start spilling again because the memory grant will have adjusted down to compensate for needing less memory and this will run for I don’t 10 seconds again 8 9 there goes 10 seconds and look what we got back to spillsville and back to a bad memory grant for this thing super cyber says would century one plant explorer report correct percent values compared to SSMS I know they do some correction to it let’s look see what happens 0.3 1.3 so yeah it looks like the costs are different in these so that’s let’s go let’s see here this is the first statement in there this is 0.3 1.3 60 38.4 and if we go back to SSMS they got 0 to 85 55 so yeah planet explorer does report correct percentages how would force parameterization affect this affect what exactly everything is parameterized this is parameterized this is parameterized I don’t know what you would expect force parameterization to affect we have force parameterization by actually parameterizing things we have nothing that is not parameterized so we have got that so the problem with memory grant feedback is that it can be a bit schizophrenic if you have queries that really do vary back and forth constantly then if we look at this we can go in the execution plan we can go to the properties and we can see come on tooltip don’t go over where I’m trying to look you can look at the memory grant info and we can see oh where is it oh you’re not hiding there where are you hiding why are you not in there am I losing my mind am I losing my mind no I think I’m losing my mind I think I might be oh no because that’s the that’s why that’s the that’s the that’s the 2017 plan if we look at memory grant info for the 2019 plan I knew I was off by something we have this info and we have this information here about memory grant feedback adjusting going back and forth Lee Brownhill says I’ve stopped using plan explorer unless it’s a monster plan I’m looking at I don’t know where so many items are within PE so you’re I think you’re right plan explorer is not good at showing some things but plan explorer is absolutely masterful in showing you the query plans for long store procedures just because we have a store procedure with two statements in it it’s very difficult to navigate statements within a big store procedure using SSMS but with plan explorer you can’t beat this if SSMS had this I think people would stop using plan explorer completely it’s just it’s a magnificent feature it’s a magnificent feature for that but you know for so like the other thing is that we brought an actual execution plan into plan explorer right we have the duration we have the CPU but we don’t have the per operator times in here like we have an SSMS right it’s just not in there now if now we can get it if we go and get an actual plan come on dummy okay fine whatever it’s not going to let me do it but if we went and got an actual plan from plan explorer then it would show us operator times but right now we don’t see the operator times here we can get it if we measure it with plan explorer but if we have an execution plan like this one that has operator times in it for us then that doesn’t import into can’t you add that no you can’t add that no right click and copy yeah I’m not I’m not dealing with it right now I don’t feel like dealing with it so let’s get back to the query at hand here let’s figure out what could we say about this query what could we say about this that would help people trying to look at issues with moving to SQL server 2019 maybe they’re seeing some weird query regressions maybe things are just not going so well for them well we could generally say that we have to beware of regressions when going from row mode to batch mode if we backtrack a little bit for the people who showed up late ungrateful rude people who showed up late when this query executes in row mode everything kind of goes okay for it right maybe not like perfect right but pretty okay this sort operates in row mode runs for about a second it spills a little but you know like not like like I’m not one of those people who you know like fixates on every single spill in an execution plan you know sometimes spills are just going to happen they’re not always the gigantic performance degradation that people worry about but this spill is this batch mode spill ends up being far far worse than if we have the spill happen in row mode and what’s I mean so like just to kind of go back and like you know make sure that everyone understands the row mode spill spills about 10,000 pages and runs for about a second the batch mode spill spills half as many pages let me get that tooltip focused in correctly just finished was it a pizza because I saw that pizza saw that pizza and that pizza looked good the batch mode spill runs for like 10 like 9 seconds here goes to spill level 8 which which means that we had to read data from the spill 8 times but it spilled half as many pages so we can’t even necessarily say you might see bigger spills in SQL server 2019 and that might cause a problem you could say that smaller spills in SQL server 2019 if they happen in batch mode could be a problem but how could you reasonably ask someone to measure that you could say that batch mode sorts are something you have to be careful of but I think a lot of what I would fish pizza good lord monster but I think a lot of what I would maybe go and warn people about with batch mode sorts would be stuff like they output data in a single threaded even if they run in parallel tempdb activity increase so the spill was smaller right like I’m not sure what activity you would measure to get it to see an increase right we have a smaller spill here so we might even see less of it it’s just it’s curious because like how do you tell people what to do what to look for what to deal with you might be able to tell them that they you know if they’re seeing a big uptick in sleep task weights that they could have something on their hands but you know the problem here is also that sleep task is not just for spills at all it’s not just for that it’s quite strange it’s quite strange so Lisa says I didn’t know fish pizza was a thing I wish I didn’t so I would say the one thing the one place I would be okay with fish pizza one of the best things I’ve ever had was Indian pizza it was just like a big piece of naan with basically just piled with Indian food on it and one of them there was like a tandoori fish one and it was excellent probably excellent because there was no cheese involved I don’t know if you ever watched a cooking show once you involve cheese and fish you’re in trouble cheese and fish should not be on a plate together that’s not a kosher thing that’s just like a human thing like just please do not have cheese and fish cohabitate you would have to be such a magnificent chef to make that work but one of the best things I ever had was a tandoori fish pizza knocked my socks off I lost my mind over it it was fantastic I forget what else was on it but holy cow that was good that was good so like you could like say SQL Server 2019 you could like ask for an uptick you could like say well if you see like some queries slowing down and you see like an uptick in sleep task weights maybe that but oh but man that’s a tough thing to measure and like I was saying sleep task weights don’t only account for sort spills they can also account for hash spills they can also account for anything that the people at SQL Server are too lazy to put in a definite compartment sleep task is just like saying it’s almost worse than the miscellaneous weight it’s almost worse than that so what could we tell people to do here what could we tell people to beware of what could we tell people that would help them fix this because what we have is a sort that SQL Server is using to optimize this nested loops join he says I see a lot of sleep task weights on Azure when restoring databases well it’s probably just a sign that your databases are really boring sorry to say you need more exciting data you are putting your computer to sleep spice things up a little bit get something interesting in there stop having dull data so this is a known thing this is not a new thing so if you look at SQL server let’s look at the fellow up by name Craig Friedman optimize IO nested loops is it is it Paul White Paul how did you steal Craig’s blog yes emerald that stuff emerald your data Lee Brownhill says I’m guessing as well as copying the replicas and yes yes yes production DBA activities are very boring they are very boring now where is this darn blog post why are you hiding from me Craig why are you hiding from me let’s let me let me go look over here because I know we have it let’s just go right to the root of Craig’s blog because then we can find it then we can find it very easily so SQL server has a whole bunch of things built in to the optimizer that can help it they can help help it like optimize certain activities one activity that is a frequently used optimization is putting data into order oftentimes if we don’t have an index that puts data in the right order or we just use a different index than the index that has data in the order we would want it in we can end up with SQL server saying you know I’m going to sort this I’m going to sort this for you we’re going to get this all sorted out for you so SQL server has a number of things that it can do and I’ll stick these links into chat so everyone has them operating operating optimizing I by sorting part one part two it’s a two parter it’s that exciting I wish Craig Friedman would come back he works on all sorts of weird no SQL stuff these days but what Craig talks about in these blog posts is things that are built into SQL and these blog posts are not new these are not spring chickens but these are still things that happen and exist inside SQL server that can contribute to anything that you see in an execution plan today this is SQL server 2019 that I’m running these demos on you still see the same stuff happening you still see SQL server optimizer costing things doing things the exact same way crazy today I had a transaction log corrupted sorted out but with heartache yes that would give me heartache too that would give me a lot of indigestion I I hate stuff like that that is not the type of problem I like solving I do not like that because they are heartache problems they are truly heartache problems they are not problems that often have a happy ending to them right it’s like putting down a dog there is no happy ending when it comes to that it’s terrible but these two blog posts very good actually the entirety of Craig’s blog is pretty awesome I would suggest reading it again even though it’s not the newest material in the world it is all still relevant it is all still absolutely relevant everything he talks about in here is stuff that we don’t need this anymore so we see SQL server sorting data putting things in the right order to make this nested loops go faster and if we look at what we’re sorting so we can see what SQL server is doing Craig is still at Microsoft he’s just working on no SQL stuff now Craig is just working on other things now just not working on SQL server stuff apparently that I know of at least he stopped writing and blocking about SQL server so I assume he went on to do other stuff I know traitor what can you say though maybe he did the right thing maybe he got out at the right time maybe he got out at the right time maybe he got out just when he should have maybe he said SQL server is a mistake I need to go work on something else I wouldn’t blame him I wouldn’t blame him SQL server is a tough one so we have sort of an interesting thing here where let’s say that we had written this query in a very specific way because it solved a very specific problem in SQL server prior to 2019 right we have for a small amount of data this runs very quickly now let’s let’s do this let’s do this backwards let’s run this for a of data first we end up with a parallel plan for both of these right and if we look at the properties of this we look at the number of rows we can see that we have some spread maybe not the greatest most equal evenly balanced spread in the world but that is going to be different if we look at this SQL server is solid old 40 year old technology that yes built on the legacy of Sybase built on the legacy of Sybase did this end up so yeah so this is where things get a little bit interesting if we think back let me actually backtrack a little bit so that I can make sure everyone is on the same page when we run this for a small amount of data first right this second execution plan that has the sort in batch mode and has the seek in batch mode right these both occur in batch mode right even like batch mode for row store that whole thing so for some reason for a very small amount of data SQL server is like throw the batch mode at it if we recompile this and we say hey let’s do this for a big amount of data SQL server is like batch mode not so much not so much the seek is still in batch mode but SQL server is like I don’t want to batch mode sort there right we’re not going to see batch mode at all here because we’re having this query up here is executing in 2017 compatibility mode so when this goes parallel SQL server is all of a sudden like I know it’s not going to be good I don’t want to do that it’s not my jam has the thread count spread improved well let’s go look not really it’s about the same you see the threads end up on different rows so Lee you should know this from yesterday with because you have Joe’s post on how rows are assigned to threads via hash algorithm so we’re getting the same rows and they’re going to end up hashing out so the spread isn’t going to really improve here it’s going to be a little bit different what if it’s already in batch mode we already have batch mode on row store we don’t necessarily need it’s trick with a fake column store index or Nico’s trick with a temp table that has a column store index on it that’s empty we don’t really need either one of those we get batch mode on row store here batch mode sorts have very specific issues where like I said earlier I’m not sure if you caught it or not but batch mode sorts output data single threaded from whatever data comes in so that can cause problems in a parallel plan right so like unless they’re the child operator of a window aggregate then they can output data on parallel threads but otherwise they’re kind of stuck outputting data on a single that’s no good the Joe posts are a weekend reading they’re pretty heavy for my little head yes Joe Joe’s head is like he is megamind Joe’s head is fantastically large it’s got all that brain in it but now what’s interesting here is if we can run this multiple times and this will end up being pretty fast right just without just avoiding that batch mode sort and if we run this for the for the small amount of data this will be reliably fast too so one wonders a little bit with SQL server 2019 is if they start seeing those sort of batch mode sorts like well would you want to force a parallel plan would forcing a parallel plan cause SQL server to change its mind about those batch mode sorts like what could we really tell what is a good call to action for all this what will we tell people to look for what will we tell people that we really need to get ahead of here and it and a tough question because it’s a tough problem because if we happen to run these plans and sniff them for a large amount of data we don’t run into the same problems that we do when they run and we sniff them for a small amount of data I’m not saying this is always going to be the case of course there are times when a big plan would be terrible would cx packet weights change dramatically I’m not sure what you mean because the serial plans won’t have any cx packet weights and the parallel plans are fast and we’re probably not all that consumed with cx packet weights when parallel queries are running quickly if you look at the weight stats over here figure out which cx packet was we’re not going to see cx consumer of course but we on the second one I would be surprised if it was much different because they both finish in a pretty close amount of time cx packet okay yeah a little bit more then a little bit more but probably not enough that I’m terribly concerned about it right because it’s a hundred millisecond difference between one and two if I mean sure absolutely if you know you have let’s see let’s see if we can let’s see if it’s still so here’s an interesting one too is the sort for the fully row mode plan will never adjust because we’re in compat level 140 but the sort for the compat level 150 plan where we end up with the some batch mode operators that will that will adjust the memory grant over here and not like holy cow we really beat the pants off it but we do get rid of this we do alleviate the sort there and we do have just about the same CX packet weights across both of them now so 361 there should be just about the same here too 369 so CX packet weights aren’t going to change dramatically I’ve gotten away from looking at weight stats for the most part on servers they can be helpful at your bottlenecks but when tuning a single query I I’ve never found weight stats terribly helpful and today’s a pretty good example of that like when we looked at weight stats specifically for that query when it spilled we got 8.2 seconds of sleep task and what the hell can you tell someone to do about sleep task weights what can you really tell people to do it’s not a lot there’s not a lot that you can tell people like it’s actionable on sleep tasks like watch out for spills people are already watching out for spills people already have their eyes peeled for spills that’s one of those things that people focus on why did this spill send pages so yeah so eliminate the sort and bam the problem is gone the problem is that if we eliminate the sort here alright so we’re ordering by score descending here if we eliminate the sort here how do we only get the top 500 rows into the app if we take the top out how many rows do we get back and do we want to send all of those rows to the app and then have SQL server sort that so let’s go let’s actually just experiment right why not let’s take the top out of these so we’re no longer going to get the top 500 here we’re no longer going to ask for any ordering here we’re just going to say SQL server go off do your thing return all the rows how do we get only like the top 500 rows in the order we want into the application if we don’t do it in SQL server this returns not too many rows for the first one but we 4,000 rows this returns 4,000 rows but now if we do this for a big chunk of gap we’re going to go from 4,000 rows to a whole lot more rows what if we added a range 1 to 500 filter range based on what but we could generate a row number but then we would have to generate a row number over the entire set and we would have to generate that row number based on some ordering element and that ordering element would have a sort in it if you want the behavior of top your options are to use top or to use offset fetch which are pretty much commensurate within SQL server or your option is to generate a row number and only get that only include rows where the filter on that row number matches what we want to send back but if you want that row number to be ordered in a meaningful way so that we actually get the top 500 rows based on score we need to order by score on the row number which means we have to sort score to get the row number in the right order that doesn’t help us either we still I mean we’re not doing any better here right this one finished and then this one here is still going oh wait no it finished so this took a minute and a half this this returned 1.7 million rows this put this returned 1.7 million rows sure we’re no longer putting data in order but we are running for a pretty long time and we have now shoveled 1.7 million rows into the application and we have now we’re going to ask the application to just cut down on 4 so just to show you what I mean we no longer have the order by here but let’s say we wanted to get things we wanted to generate like the row number over score anyway and we say row number over order by p dot score descending as end now we can’t use this in the where clause directly so we would have to make two changes to this query we would have to not only add the row number here but we would then have to either select we have to turn this into a derived table right and say select star from and do this as x where oops steve fix this thing oh why did you do all that you are crazy it is x where x dot n let’s just do just to have it done between on and 500 so we would have to use as a CTE CTE are garbage stop relying on CTE would it be possible to have an index on score to prevent the sorting yes it would be possible to have an index on score to prevent the sorting but that might mess up other stuff and we do have an index currently on the table it does have score in the include so it’s not in order why is CTE garbage because they don’t do anything useful they don’t fence off queries they don’t materialize data they’re just useless they’re just like having a view or a drive table or anything else they’re not good they don’t help you do anything better so let’s also do select star from this as x where x dot n between 1 and 500 so yes we could change the index to have score in order but then we’d have to disrupt the key columns of the index and if other queries use this index if you know just think of all of the pain that can come from changing key column order in an index because remember key column order matters included column you can have in whatever order you want but if you have key columns set up in a specific way there is a column to column dependency from owner user ID to the diff to post type ID if we put score here or if we put score here or if we put score at the very beginning we would disrupt queries being able to go across that’s a lot of records for a temp table maybe yeah 1.7 could be a lot for a temp table it could also be a lot to stick into an application server because those things are always just murder boxes anyway so we could think about changing the index or adding a different index but we would have to be sure that if we were going to disrupt the order of columns in the key of the index that it was for a very very very very good reason because who knows what crazy legacy application stuff needs the index in this order we could also add a new index that maybe helps things out but then we would have to be sure that new index wouldn’t cause any regressions across other queries and also that new index would actually get used by our query now I haven’t gone down that path of adding a different index and seeing if it gets used I am willing to do that here but let’s just see what happens when we run this with a row number first Zane says it’s more of a created so Zane you’re almost right it’s not an abstraction it’s a distraction it is a complete distraction and you know what we’ll talk about why CTE are silly too what about a column store index what about a column store index tell me what about one you’re going to throw the kitchen sink at me we’re going to have to ask why so when we generate a row number over p.
score we also end up sorting for it here right so this will not help us tremendously I would wager I would wager this would not help us tremendously because we’re still going to have that big old sort now Kelly if you’re suggesting a column store index in order to get batch mode we’re on SQL server 2019 and we already get batch mode for row store which you’ve talked about a little bit here much or maybe you got distracted by CTE and walked away from the webcast for a little bit but we already have batch mode going on in here right problems and he said Zane’s been drinking the Kool-Aid yes Zane loves Kool-Aid I hear but since we had a question about it let’s look at why CTE are stupid of course I misspelled stupid right let’s just say we select top one from users old style top we want to have the new style top in here and since Andy is here we need to take sort very seriously the sort is now batch you have been if you have been paying attention you would have seen that right the entire time the sort has been batch mode the entire time we’ve been talking about it the sort only wasn’t in batch mode when it was parallel the sort was batch mode the entire rest of the time we need to work on your concentration skills so let’s select the top one u.id and let’s capitalize things properly so that our friends in the case sensitive server department do not get angry and let’s just say where id equals 22656 cool I’ve forgotten s there there we go now we’re all sorted out but you didn’t capitalize properly either SQL prompt is broken today let’s see I’m recognizing the delegate for the new style top delegation yes those new style tops hopefully someday hopefully someday I’ll be able to make it so with just running the query inside of the CTE we have one seek to the users table right and if we look at the results that we get back from there we will just have this one column called ID now if we say select star from CTE are stupid and let’s say as C1 we will still get the same execution plan we still have one seek and two users but now let’s go and join CTE are stupid as CTE on that ID column and you know what we don’t even need to get things from other places C1 dot star right and we look at this and we say CTE are stupid and now we look at the execution plan we have two seeks into the users table we no longer have just one and if we go ahead and say join CTE are stupid as C3 on and I don’t care what we do here should I do it on C3 dot ID equals C2 dot ID or C3 dot ID equals C1 dot ID I’m fine doing either one you tell me which whoever answers first I’m going to do what you say we need an Eric blood pressure gauge widget on twitch you know this is cathartic for me C3 equals C1 okay C3 equals C1 here C3 dot ID equals C1 dot ID and if we now run this because CTE are stupid we are now going to have three seeks into the users table CTE are not fun they are not good for you if I add another one just just just because I want you to see it if we join this as C4 all right we go the extra step out of the mile here on let’s just go back to C1 dot ID equals C uh for dot ID this will get a fourth seek into users so generally re-referencing CTE re-referencing CTE will not is not your friend man I need my dev team to watch this desperately good news good news Camaro I do developer training if you would like your developers to learn this and be able to ask questions then boy oh boy we can certainly do that so a CTE would not help us much more here and just to go and you know I’m going to leave this but leave this as is this is going to be the exact same thing as before so if we run this remember remember remember carefully this execution plan this sort was always in batch mode the only time this sort comes out of batch mode is when SQL server says oh you know what oh you know what I would like to run this in parallel and when it runs in parallel well that’s when things things get interesting now what kind of sucks about this is that we don’t get a window aggregate function here I was I was half worried that we would get a window aggregate function but we don’t screw you SQL server 2019 you are not my friend you are not my friend anyway so what could we tell people to do here like what would be what would be what would be the takeaway like we still have this query to figure out what to do like I don’t know the same thing happens if you use table joins I don’t know what that means alternative no sub queries have to execute all that syntax too if you want a stable result set use a temp table use a real table that’s it all you have to worry about so just remember that the query inside the CTE is not materialized anywhere the results aren’t materialized the expressions aren’t materialized anytime you re-reference that CTE you need to re-execute the query inside of that and that means you can do a whole lot of extra work so something like rejoining the CTE to itself would also mess things up tremendously but if you repeat a sub query then repeating a sub query will also re-execute the syntax doesn’t really get you anything it doesn’t really get you anything it’s unfortunate it’s quite unfortunate sounds like a connect item I guess thing is if you if you were to materialize a CTE in any meaningful way then you would need to account for what happens where that data gets materialized do you put an attempt DB do you have a local store for things like that per database how do you manage concurrency there how do you manage rollbacks there how do you manage space the inevitable concurrency issues that come from a whole bunch of queries now trying to use space Zane brings up a good point we don’t know what to do there we don’t know what’s right or wrong there so it would be up to users to or it would be up to Microsoft to give us a hint like option materialize CTE or whatever and it would be up to us to add that and use it there which still doesn’t help people who are on third party vendor apps where they can’t change the code and you know that hint would probably only be on you know the next of SQL server so it might not help people going back all that far and you know it’s just sort of like you add it but at the same time if you’re going to add a hint to materialize a CTE why not just add a temp table yeah exactly so like if you started doing that automatically if you started automatically materializing CTE in temp DB you would be in trouble the only thing I could think of that might make that tolerable is if you used something related to accelerated database recovery where you used a local persistent version store to materialize CTE instead it’s the only thing I could think of that would be neutral ground that would help that out that would have any user craze ifying problems with it you would have to have the database setting you would have to have probably not a server level setting would be dangerous but you have to have the query hint the database scope configuration probably a trace flag then a whole bunch of stuff to turn it off to disable it and like it’s a lot of work it’s a lot of work when people like to add all those hints and settings and everything when really if you just use a temp table you would probably get the equivalent experience of whatever Microsoft would do to materialize a CTE I get that people really want this magic thing but Microsoft doesn’t have a good record of applying any Disney magic to new things so you would probably just get a new thing that is just standing on the shoulders of a bunch of old things there’s no way to have that pan out for free there’s no way for Microsoft to implement materialized CTE without without just like using a temp table behind us yes yes like if you want to see something very funny like people got all wound up about table variables right but if you ever look at a table variable right we don’t even need to put anything in it oh I forgot the word table though nuclear t table there we go well that didn’t go well this isn’t my SQL no back ticks there and then we say select star from t and let’s set statistics io on all right and we we look at this you know this is this is just going to have a temp table behind it anyway so like everything Microsoft does it people are like it’s magic it’s fixed it’s in memory we did it Microsoft solved all the problems it’s not it’s just everything is backed by a temp table everything is tempDB what no one understands is it tempDB all the way down tempDB is the turtles of Microsoft SQL Server hope someone from the tiger watches your channel I’m pretty sure they only watch my channel to print out new things to put on their dart boards yes yes the villain is tempDB all along if you use a temp table with three no no so here’s the difference what’s a good way what’s a better way to show it so let’s say that our query is a little bit more complex right CTE are stupid so with the trivial example I gave you yes it would not be a big deal but let’s say it was users ID where u.id equals 22656 and now let’s do join posts on p.
owner user ID equals u.id and now let’s join badges on b.
user ID equals u.id so now we have a little bit more going on in here you know the same thing will happen if we look at this and if we run from as c1 right if we do this the same basic thing will happen except now as we add references to the CTEin there equals c2 dot id now as we get things a little bit more complicated we start to really see the repetition in the query plan being crappy right and if we add a third one in right we’re going to see that branch come in again right so as c3 on c1 dot id equals oops equals c3 dot id right so now we have a third branch of that so what I mean when I say CTE are garbage is because people what does everyone say about a CTE it makes my code so much more readable what do they end up jamming inside a CTE that 5000 line monster nonsense query that has a filter on the outside based on the four most complicated calculations inside of the CTE and they think that they have performed some active magic performance wizardry by sticking this thing in this query that is the hottest garbage on the hottest day of the year buried 10 feet down on Venus is magically safe and wonderful because it’s in a CTE it’s readable understandable now because I said with before I wrote this query so people tend to put very complicated things inside of common table expressions and when you do that and you start repeating yourself where you touch things from the common table expressions where you touch the code inside it multiple times you start ending up with these repetitions in your query plans and so what I mean by use a temp table instead is if you just said oops and then we said here you would only have to execute that first branch once and then you would have well yes you would have to hit the tables to do the self join you don’t need to expand all of these joins over and over again so like that’s that’s really what I’m getting at because people jam the worst things in CTE and it’s like well it just fixes it so like for putting a single query in there not a big deal right but if you have big complex things in there and you end up needing to execute that big complex thing over and over again you’re in tough shape you are not you’re not in good shape so anyway anyway ah this further off than I thought it would kind of funny but I’m okay with that I’m okay with that so we have about ten minutes left I do want to thank everyone for coming in hanging out watching me kick this queer I am going to have a blog post about this yes they do create a testy Eric and what you know just while we’re here as a thank you for showing up I have two more dates for my I have two more dates for my online performance tuning class Friday July 10th and July 24th if you as a thank you for showing up there should be floating above my head a coupon code that will get you 75 bucks off the cost of the one day training if you want feel like buying a ticket you can go over there and if you sign up and buy a ticket then you get all of the videos on my video training it’s a good 24 25 hours of performance tuning videos that I have available up on my site you get all of those for free if you buy a ticket to the class you get those for life you do not have an expiration date thank you Gino was in the class that I had last week so he is a valid unpaid witness to the things that you will learn in the performance tuning class Eric puts a coupon code above his head so he can flex when he points to it I wish I had anything left to flex here’s the thing I have not been to a gym now since March 5th 7th I forget exactly when I have nothing left to flex there’s zero flex left in me I am really good at flexing my mouse click finger but that is about the end of it I have very good mouse click muscles I have nothing else nothing else I have nothing left to flex I’m going to have to work on that eventually I’m going to have to either move to a state where gyms are open or buy a house in a state where I can afford a house and put a gym in the basement or garage or that’s like my only choices yes I am in New York City so we still do not have gyms open he says agreed class and video sets are legit highly recommended yes thank you Zane and he says 8 ounce chateauneuf de pop curls all of the chateauneuf de pop that I own is currently in my mother’s basement getting ready to go to the summer retreat NYC epicenter yes NYC did not did not do so well yes did not brought to you by Canada Dry I wish if Canada Dry sponsored me I would be so happy they are one of my favorite seltzers and if they sponsored me they would be my absolute favorite seltzer right now it’s between them and polar they are the only seltzers that have strong enough bubbles that get on the tongue and make it hurt a little bit Texas and Florida not doing so hot now hopefully they get things figured out I want to see everyone going back to a happy and healthy world that’s what I’m after let’s see do you ever use one of those soda streams no there’s the so no so I’ve had friends who had soda streams and they did not have very good luck with them they found that the bubbles did not last very long and they could get things quite as bubbly as they wanted to I have very high expectations for bubbles I want strong I want aggressive bubbles I want little scrubber bubbles for my tongue I want get in there get in there so I’ve not heard a review of soda streams that seems to indicate that I could get the kind of bubbles I want out of a soda stream but if someone can point me to how you get the strongest possible fizz into a bottle you can just use standard CO2 and load it up I do that for tonic water Jack Rudy syrup and spray this wow it’s very carbonated is there a good time to put questions into chat during the demos I always feel I ruin the flow of the point you’re trying to make but the delay on the chat doesn’t help no just whenever if I’m in the middle of something that I really want to finish it before answering the question I’m totally fine with questions showing up whenever I like I like having things show up over my head I like having things show up over my head because it lets people know that people are here when they see people are here and active then they’re more prone to being here and active too and I like having things be here and active I want someone to run SP who is active and just see an ASCII image of me pop up here doing it because that’s what’s fun right being here doing stuff talking to people talking to people who I wouldn’t get to see every day anyway you know I’m very grateful to be able to do these to have sort of a setup that works and people who show up regularly to watch me do goofy things it’s nice I enjoy it I enjoy having a bit of an audience alright any other questions anything else you all want to talk about ask about feel inclined to know more about be happy to answer something be happy to answer something stream setup is great thank you Arthur hopefully it stays that way hopefully I don’t end up looking sad and outdated too soon I’m still adjusting to SQL people streaming seem to happen all at once well I mean it’s just sort of circumstances right what else is there to do if you don’t hop on board you you miss out you don’t stream what are you left with you kind of end up with the same people doing the same stuff some people might just blog occasionally some people might blog constantly this does get recorded too this all ends up on YouTube I still record stuff I’d rather go live and talk to people than just talk to a camera I spent 48 hours talking to a camera to get the first round of recorded stuff in and I felt insane at the end of it because it was just like three or four days straight of me recording things and just talking to a camera and while it’s nice to be able to stop and do over if you make a mistake or flip something up still just talking to yourself no no mentions of that so nothing of the sort nothing about hats we’re all grateful for a lack of hat talk all grateful to not have to address hats good times alright so it’s been like an hour and a half wait a minute if you have a condition like this and field one modulus number equals number service yeah that’s not good so it’s going to depend a little bit on where it’s happening so like let’s say like let’s say that you have a query like select count from users where let’s say u dot reputation modulus 11 equals zero run this I mean this is relatively fast because there’s not a lot of data in there and we get like a not great guess here but like what’s even oops not seeing SSMS nope ah there we go I knew it was there somewhere all right so let’s just change that let’s say modulus 2 equals zero count this comes back pretty quick and you know we make sort of a crappy guess here right we make it we were off by a bit in the guess we’re going to have to read everywhere on the table because right now we don’t have an index on reputation but let’s do something so we can figure out let’s do something a little bit different let’s say id equals one actually let’s do 22656 because I know that’s going to come back with something so here we get a very bad guess and we end up scanning the entire clustered index because that’s our only option but if we change this a little bit now we have an index seek because we’re seeking into the id column and the residual predicate on reputation just really doesn’t make a difference so it really depends on what indexes you have what other predicates you have and what else is going on in the query people make a really big deal out of sargability no you’re looking at my SSMS now so I verified that you’re looking at my SSMS because that is what Streamlabs tells me so it really depends on where the lack of sargability is happening so if we have an index or rather if we have a query like this and we’re able to filter we’re able to seek earlier on right we’re able to seek to where id equals zero then the predicate over here on that that sucks it’s not sargable on the reputation column doesn’t make as big a difference if we were to say something like let’s see what other tables are in the post table what else could be doing there select top 10 from users what other columns do we have in there that might be interesting let’s say and display name like well a right well actually let’s make sure that we have our case sets and case sensitivity worked out so now we don’t have an index that’s helpful right so we’re back to scanning this thing if we create some indexes right let’s create index whatever on users let’s do this one on reputation and then display name and then we’ll do one on the opposite direction afterwards oops I didn’t create that I just went right back to the query didn’t I right so now with the leading column being the crappy predicate right we have to scan that index right so that’s not so great there but if we change the order of the index columns now because we’re only doing a trailing wildcard sort on display name it’s not going to be it’s going to be okay ish but now we’re able to seek to the a’s that we care about and the residual predicate on reputation isn’t that big of a deal anymore right so we have a seek predicate down there and then the other one is just not that great so yeah Andy’s right as long as that’s not a variable as long as it’s a literal value then you could totally create a computed column to get around something like that it’s kind of weird logic to me though anyway like why does the modulus math of a number have to equal something in order for it to be to like qualify for it’s like a very weird set of logic like it’s a very odd set of logic but you know I’m going to try not to kink shame anyone here I don’t like kink shaming because I have so many issues but yeah the computed columns are a very good way to get around that and then if you don’t have a computed column data around that then stargability really matters most when it affects the leading column of an index if you have good predicates on other columns and they lead in the index then having the non stargable predicate on a key column that’s later in the index because you were able to row reduction first and it just makes less of a difference let’s see and he says we did exactly this because the app developers do it modules tend to split work into 10 work queues yay app developers they see squirrels everywhere mr.
P Shaw says if reputation modulus one was the only predicate could you get the right query better or is it just going to be bad so the only way you would have to alter table users oops add call add uh chuckles as uh reputation modulus one and you might want to do some art and just to make sure things turn out the way you want it you don’t have to persist it but you would have to index it just like any other column you would have to index it in order for things to turn out well so uh let’s ha ha ha I’m having a good time typing drop come on dummy drop indexes get rid of all the indexes so with this column added but not indexed we’re gonna when we you know we’re gonna have to compute the scalar at some point we’re gonna have to scan the clustered index to get in there right we’re still gonna have that crappy predicate on there but at least sql server will be smart enough to say hey if you add an index to that column we’ll be in better shape so now if we actually just screw it let’s just take the missing index request because in this case sql server is not wrong and it’s missing index request right we add this index on our computed column and display name sql server is able to index let’s see a couple questions here vendors table and code and we can’t alter the table then we’re just stuck yes yeah you yeah like unless the vendor is yeah but if the vendor is any kind of reasonable vendor then making that change is not a problem is the drop index proc available I’ve seen yes you can find it on Brent’s site but now if we have an index on chuckles and display name we are able to seek that predicate on chuckles without anything so computed columns can be very useful can almost be very useful in these cases but just like regular columns they don’t really reach their full potential until they are indexed so if you have computed columns that’s great but you know whatever anyway we’re going to call it here because I need to I’m going to start doing a dance soon and it’s not not not the good kind of dance so I’m going to call it a stream here thanks everyone for showing up I will probably be back tomorrow to do what I don’t know yet I’m going to make something up today but I will see you all back tomorrow thanks for joining remember if you want to join me for a full day of performance tuning stuff you can go to one of those URLs that I am pointing to and you can use that coupon code up there in order to get 75 bucks off so you get a full day of performance tuning training with me and then access to all 25 quite a deal quite a deal thanks and I’ll see you back tomorrow
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
In this video, I delve into the nuances of query tuning and parameter sniffing issues in SQL Server, providing practical solutions for handling these challenges. Parameter sniffing can significantly impact performance when a stored procedure or query is executed multiple times with different parameters. To illustrate one approach to mitigating this issue, I demonstrate creating an index that helps in optimizing the execution plan based on the most common parameter values. This method involves writing a stored procedure that accepts a single parameter and uses it to filter data from the `votes` table in the Stack Overflow database. By counting records and formatting the result for readability, we can see how different parameter values influence the query’s performance and execution plan.
Full Transcript
Thank you. Thank you, Varis. I’d like to thank you.
Bye-bye. Wild. Wild stuff. All right.
Everything looks like it’s working there. That’s exciting. Everything looks properly in place. Minimize that. And let’s close the browser.
Let’s minimize the browser so that we don’t have that distracting us from the important work. That we need to get into. Make sure that we’re in the right database for all this stuff.
Because how else can we live if we are not in the right database? We’ll have to be stuck. Hello, everyone.
Let me… Oh, what the heck. Let’s see. This should no longer… Slideshow.
This should be… Pretty static and in place. There we go. Now we’re looking good. Cool.
So how is everyone today? What are we all up to? What is today? Wednesday? It is. It is Wednesday.
Fantastic. Fantastic. That means… The week is nearly over. The week is nearly over.
We are almost… To Friday. Which means… There are only… Thursday.
Let’s see. Thursday. Friday. Saturday. Sunday. Only four more days of work until Monday. Sunday. That’s going to be fun.
All right. So… I don’t know. Do some small talk. We’ll wait for… Wait for some people to show up in here. Wait for some more eyeballs…
To jump on in. He says… I have the next days off. Not sure why I’m broadcast. I don’t know.
Like… Like… Like… Like… You have the next two days off. And then the weekend, right? Or… Or… Or do you have the next two days off because you have to work the weekend?
Because I’ve… I’ve definitely run into some… Some people who have had that problem. In their life. It’s like…
Yeah. My boss gave me… Just like… Like… Tuesday and Wednesday off. Like… Oh. Cool. Why? Because I have to work the weekend. I’m like… Oh. That sucks. You didn’t really get days off. You just switched days around.
Four days. You’re just making… Hey. Thanks for calling the chat boring. That’s nice of you. And then…
Also… Thank you for dragging down the boring chat with your boringness. Let everyone just pile on. Do we have…
Do we have any other insults for the chat? While… While… While… While Lee is… While Lee is busy. So I’m going to need a couple other people to step up and volunteer to hurl insults at me.
While Lee is off of work. And probably not watching me do anything. So hopefully…
Someone… In the greater SQL Server community will be able to step up. Fill those big shoes. And call… Call my chat names. Today I’ve got proper seltzer back.
I mean… By proper seltzer I mean it’s not flavored. So I feel much better about myself. Much better about myself. Do do do.
Alright. Since I think everyone understands what we’re going to be doing today. I’ll stick this one up behind me for now. Let’s see.
Oh that looks pretty. That looks pretty. So I’ve got over 70 people slated to show up on Friday. And I’m mildly terrified now.
At first I was just like… You know what? I should pack in as many people as I can. And now I’m like… Man I better not screw anything up. No pressure though right?
No pressure. No pressure. Just recalling about it’s gold. Yes. I wish more things that I owned were gold. So that I could sell them.
I could sell them. I could buy gym equipment. And then I would not have to wait until… Maybe phase four of New York’s reopening.
To go see a gym. That would be all that I did. Now I’m curious like…
Now I’m thinking like you know… It’s going to be a lot of people… Or there’s going to be a lot of gyms that are closing. I wonder if I could like buy some… Some like going out of business gym equipment. But then I’d just be very tempted to just to like…
Like just open my own gym. Get the hell out of this computer thing. Computers are terrible. Have you ever used one?
Computers are absolutely miserable. I hate computers. I want nothing to do with them anymore. They crash on me constantly.
They don’t listen to reason. Let’s see. Lee says… Yesterday I learned that CX packet is not to be ignored. I love SQL Server.
Every day I learn something new. So Lee… So Lee… Like why would you not… Like under what circumstances… Should you not ignore CX packet?
I look forward to hearing about this. Let’s see. If you bought a gym with gold… Would you make it a gold gym? No. And I tell you why. Tell you why.
There was a brief period of time… When we lived in Austin, Texas. And I got a membership… At the Gold’s Gym in Austin.
And I paid for a year up front… Because I had some special on it. But we ended up moving out of Austin… After six months.
So like three months in… We were like… I’m out. We’re leaving. Just can’t do it. It was too much of a weird culture shock. Not like politically or anything like that.
But like… Just having lived in New York forever… Not being able to get like… Like real Chinese food.
And like pizza being served on Wonder Bread. And it being hot. And there being bugs this big. There was just a lot of…
Of reasons why it didn’t work. But I was like… You know, Gold’s… I’m leaving for… We’re out of here. We’re leaving Texas. We’re not going to be there.
We’re not going to be here. You know, I’ve… Paid for a year. Is there any way I can get any of that back? And… They said… Where are you moving? I said…
We’re moving back to Brooklyn. And they said… Ah… Well… We can’t give you a refund. Because there’s a Gold’s Gym… Within 25 miles… Of where you’re moving to.
I said… 25 miles? Where is this Gold’s Gym? And they pointed… And like… There was like… Some Gold’s Gym map. Where there is a Gold’s Gym… Like…
Like… Way out on Long Island. There’s one closer in Brooklyn now. But… It wasn’t open then. And they were like… Ah… There’s one… Out on Long Island. I’m like… No…
Do you know… Do you know anything about New York? Is there like… Like… You have like the slightest clue… How things work here. Because no one… Is traveling… From Brooklyn…
Out to like… Wherever on Long Island… To go to a gym… And then come back. Like… It was just… Like insane. If there was one in the city… Or if there was like another… Like a gym somewhere in Brooklyn…
That would be a different story. But they’re like… Like… It was like… 15 miles away on Long Island. I’m like… Well… That’s not good. Gold’s Gym…
Are they like… No… The Gold’s Gym that I was going to… Was more expensive. I want to say it was… Like… 600 bucks for the year or something. Like… It wasn’t a big deal…
That I didn’t get the 300 bucks back. I was just… Like… I was mostly annoyed… That they were like… There’s a gym within 25 miles. I was like… Yeah… That’s going to happen. That’s going to happen.
Let’s see… Uh… You know… I could buy a 24-7 gym. The problem with a lot of 24-7 gyms… Is that… They don’t have… Uh…
Good barbell equipment. So I would have to… Buy the 24-7 gym… And then probably… Import my own barbell equipment. And he says… I used to think it was a safe weight type…
But I found out… That… Query with uneven thread work a load… All… Get even memory grants… Since your memory just sat there… Doing nothing… Wazier…
Yeah… Um… So… I wrote a post a while back… About… That…
Oh… It was over on Brent’s site though… Hang on a second… But it was… Not… I mean… Not exactly about CX Packet. So…
A while back… Microsoft decided… To… Um… Split… CX weights… Into… Two different categories… CX Packet…
And CX Consumer. And of course… Uh… CX Consumer is… Like the coordinator threads… Waiting on… Things coming on in…
And CX Packet is still… Queries going out there… And running and doing stuff. So… Uh… There are… Times when you will have… A… Query…
With… Uh… With skewed parallelism. And on older versions of SQL Server… You will… Uh… You will see that register as… Uh…
CX… High C… You can see that register as… High CX Packet. Uh… Newer versions of SQL Server… You will see that register as… High CX Consumer. So…
Uh… Well, that can be… A sign that… Uh… You know… Parallel queries are… Skewed… In some way… In their row distribution. Um…
Yeah… I mean… Like… It’s certainly something that you could… Uh… It’s certainly something that you could… Uh… Look at when you’re dealing with a parallel query. Um…
But I think in general… If you see high CX packet weights on a server… It’s not necessarily a sign that… Every single query is terribly skewed… All over the place. There is…
There is a… There’s a chance. There’s a chance. You could also just have high CX packet from queries going very, very parallel. There’s also that.
Uh… Let’s see. Let’s catch up a little bit here in chat before we get started. We’ll get started in a couple minutes here. Um… Let’s see.
Ah, yes. Congrats on getting a call-up from Itzikbengan. Yeah, that was… That was a crazy… That was a crazy thing to happen. I was…
I was… I was just as shocked to have that come out of nowhere. I was like, what the hell? That was crazy. All right.
So, uh… Let’s… Let’s get started and talk a little bit about some query tuning. Oh, you know… Just really quick in case anyone who is joining today who hasn’t joined the last couple days. Um…
You know… Uh… Doing a thing on Friday. All day. Advanced performance tuning. If you feel like joining. Uh… You can get a ticket. You can get a ticket for very cheap.
125 bucks. Includes access to all of my SQL Server video training. Which is… 24 something hours of it. And, you know…
Well worth it. Well worth it. He says… It’s something on my list to look into more, though. Or also… Let’s see…
Uh… No… You’re… You’re getting ahead of yourself a bit, Lee. I think you’re just saying words that you’ve heard now. All right.
Let’s get the heck out of this thing. Let’s go look at demos. Because that’s where all the good stuff happens, right? When we start doing demos. Everyone loves demos.
That’s where you learn everything. So let’s… Let’s clear out… Everything. Oops. I didn’t highlight everything. All right. We’re going to create some indexes. And while we create some indexes…
We’re going to look at… Um… So this… This… This store procedure started off as… A… A thing that I wanted to show is…
Uh… One way of dealing with a parameter sniffing issue. So like… You know… You… Have a… Have a store procedure or something else that accepts a parameter. And…
What happens next is parameter sniffing. Because at some point… Despite all of your best efforts to… Reasonably index for things so that you have… Selective columns and…
You know… You… You cover all your bases. Uh… Even… Even if you… Even like… Not every value in every… Every column is going to be…
Selective. And… And… You know… Part of the whole selectivity thing is that… Uh… You know… Values and columns being selected… Or…
Being selective rather… Does kind of depend on how people are searching them. So… You know… If you have a string column… And every string is… Semi-unique…
That’s fine if people are searching inequalities. But as soon as people start putting wildcards in… Selectivity… Kind of gets… Kind of gets…
Can get hurt. The same thing with dates too. Right? So if you have… You know… Date ranges… And someone searches for like the last week… That can be pretty selective. If someone searches for the past five years… That’s not as selective.
If you have… You know… Uh… Prices… And you want to search a range of prices… Things that cost between… You know… Ninety dollars and a hundred dollars… Might be fairly selective.
But things that cost between zero dollars and a thousand dollars… Might be… Not as selective. So… You know… Selectivity… Not only depends on… You know… Uh…
Like… How unique the data is at face value… But also… Kind of how people search that data. Right? So… There’s stuff to think about there. And… Um… Parameter sniffing can really happen…
From… Either situation. Or sometimes it takes a combination of parameters for it to show its face. Like… You need to have like… Like… Like… Two non-selective parameters or something. But this is a store procedure that…
You know… I… I wrote… And I want… And like… I wanted to show one way of handling… Issues with parameter sniffing. And… You know… When I teach about parameter sniffing… I…
I try to keep it as simple as possible parameter-wise. So… This just takes one single… This store procedure just takes one parameter… Uh… For vote types over in the… Over in the votes table in the Stack Overflow database. And just to kind of give you…
Uh… An idea of what that looks like. Hoop… From… From… That’s a good job, right? Never trust a professional presenter. That’s to vote type ID…
Count… We’ll do a big count. Because we are big counters. And we’re also going to nicely format… Our count.
Right? Because… The only thing… More annoying… Than big numbers… Is big numbers without commas. Because they’re hard to read. Especially if you’re as dumb as I am.
And we’ll call this… Records… To hopefully annoy some people. Let’s see. D-back says… Is parameter sniffing something new…
Or it’s been there for years… Like dating back… It has been… It has been a problem… For as long as there have been… Parameters in databases. It’s… Going back to forever. Basically.
Since like… The dawn of databases. It’s… It’s called some different things… In different databases. In Oracle… I know they call it… Parameter peaking.
Or… Like… Bind… Bind… Parameter… Bind peaking… Binding parameter peaking. Because Oracle just calls it… Something a little bit different. But… In SQL Server… It’s been parameter sniffing…
Or parameter sensitivity. Is probably the nicer way… Of saying it. But it’s been around… Just about forever. The term itself… I…
I don’t know. I don’t know… I don’t know the history… Of it that well. I… I… It’s a good question. I don’t…
I don’t think I know… The etymology of that one. It’s not like Query Bucks… Where… We very much know… That it was Kendra Little… Who came… Who came up with the term…
Query Bucks. Because Kendra… Is one fantastically smart cookie. And she says funny things constantly. Oh!
Ha ha ha ha ha ha ha! I made my first big mistake. Does anyone see what I did wrong? Does anyone see what I did wrong? Someone in SQL Passes…
He invented it. Ha ha ha! You’ll have to tell me who that was. I would like to know who that was. But this… This… This… This result set sorted… Very… Very strangely.
And it sorted very strangely… Because I am converting this count… To a comma delimited string. And so now SQL Server thinks… That this is… A string and not a number. So we have to order by…
The plane count… If we want to get things back… Descending. Yes. Arch our ordering. Bummerino. Not my favorite thing in the world.
Let’s see. Do I have Zoom It turned off over here? I do. Wonderful. All right. Cool. We are limited to Zooming… Over here. That is just what I wanted.
So… When we look at… The Vote Type ID column… Over in the Votes table… We have many, many different… Vote Types.
Well, not many, many. We have about 16 vote types. But this is one of those… Selectivity things where… You know, up at the top… We will have… Vote Type 2 with 37 million rows. And down at the bottom…
We have Vote Type 4 with 733 million rows. In the middle… We will have some values… That are a little bit closer together. Like, you know… We will have some that are… Up over a million. And then we will have some…
That are under a million. But still a fairly good amount. And then some that are just… Kind of like… Less than that. Right? So there are some… There are like… Like three or four different… Like how are the categories like… Like three or four different categories…
Of selectiveness… Within this column. And when we… You know, when you think about… Trying to index for selectivity… This is the kind of stuff… That you sort of have to take into account. Because you really do need to…
You know… Look at how people might be… Searching these things. Especially if someone was going to… Search a range of Vote Type IDs. Like if someone… You know… Did not just do an equality on one…
Like someone… These like 40 million rows… 37 million are going to be Vote Type 2. So… Selectivity isn’t just a guarantee. Right? But we have… We got this store procedure.
And what this store procedure does… It was it will search on Vote Type IDs. And that’s what… Sort of this first part does. Alright? We get some data from the Votes table… Where Vote Type ID…
Is equal to Vote Type ID. And we want to find… Votes… Where… I don’t know… We have…
Posts… That… So… I’m going to tell you a funny thing about this demo query. It does not make… The most sense in the world… Given the…
The stack overflow schema. But… It works really, really effectively as a demo. So I’m not even going to try to explain… What this thing is actually looking for. What I’m going to do is just show you… The monstrosity…
That is the parameter sniffing that goes on here. So… For these queries… All of these vote sniffings… Vote Types 1, 2, 3, 5, and 10…
I’m not going to run these in front of you… Because they run for a pretty long time. If we go look at the saved query plans I have for them… Vote Type 1 runs for around 15 and a half seconds.
Alright? Vote Type 2 runs for around… 35 seconds. Vote Type 3…
Another 15 seconds. 12, 15, 14… So like 13 and a half. So… These are all fairly long running queries. And these are all… Ones that I run with recompile.
So there’s no sniffing here. These are just plain slow. These just don’t do so hot… When SQL Server comes up with an execution plan for them. And that’s sad because…
A lot of the times when I talk to people… About parameter sniffing issues… A lot of them think that recompile… Is just a straight up… You know…
Golden ticket to solve the problem. Sometimes it is. Sometimes you can… You can go pretty far with a recompile hint… Placed in the right… In the right… In the right spot. And you can avoid… Dealing with…
With parameter sniffing… Because SQL Server is just going to come up with a… Good plan each time. But you can also run into just weird stuff… Where SQL Server… Like you know… Goes and just picks a bad plan.
Even with recompile… SQL Server is capable of picking a bad plan. Even if you compile a query… Specifically… For a parameter.
You can have a bad plan for that. For all these vote types… So 4, 6, 7, 8, 9, 11, 12… We have… Fairly good and fast plans.
These ones I do feel… Pretty safe running in front of you. Right? So all of those finish in just about 2 seconds. Right? We are on… Oops.
Didn’t go over quite far enough. There we are. About 2 seconds. So we’re in good shape there. Right? And if we look at the execution plans… These are going to get much different query plans… From the ones that we saw over here.
Right? These are all going to… These are going to get… Like you know… Slightly different plans than we saw… From like the plans that recompile.
Right? There’s a lot of like hashing… And craziness going on over here. And like big parallelism… And scans and all that. And over here we have something… A little bit different.
TZH said… SQL Server picks a bad plan. Certainly not. Yes I know. It’s insane. You know… But that’s the thing about working with databases. Is that… You’re not special. Your query isn’t special.
Your indexes aren’t special. Your schema is not special. I mean… Maybe it is special. But here’s the thing. Is the optimizer is a Swiss army knife. It is a general purpose utility.
And… It needs to be good… Across a wide variety… Of hardware… And indexes…
And schemas… And selectivities… And… And target… Like… It has to be good across all these different things. And that’s tremendously hard. And most of the time… It does pretty okay. But there’s all…
I mean… There’s all sorts of stuff that… You know… Like… Like you and I can do… To mess with the optimizer. To like make it… Like make it pick something bad. But then there’s… There’s just… You know… Blind spots.
There’s… Things that the optimizer… Is strong at. And… You know… There’s… Just sort of… Weird edge cases where… You know…
It… It makes some funny… Inference… Where like something is… Just cost it all wrong. So… You know… There’s that to consider. You know… It’s not like the optimizer is… Designed to come up with a perfect execution plan…
For every possible query. It’s sort of a general purpose thing… To find a good enough… Cheap enough plan pretty quickly. And… I’m… I’m cool with that. I’m cool with that because…
Uh… People still have to call me to tune queries. So… What we’re going to do is focus in on… A couple… Vote types.
We’re going to look at vote types 4 and 1. We’re going to look at 4 and 1 because… These… Two queries… Have… Fairly different run times. But also…
They have very very different distributions. I don’t want to sit around waiting for vote type… ID 2. Because vote type ID 2 runs for about 40 seconds. And I don’t want to sit… I don’t have enough to say… To kill 40 seconds every time I need to run this.
This one runs for about 15 seconds. I can… I feel very comfortable filling 15 seconds. With either… Um… Badums… Whatever’s…
Uh… Humming… Asking how you’re doing… Uh… Telling you what I ate for breakfast… Uh… Complaining about… Not being able to go to the gym. And just various other things. There’s like…
Fun stuff that I think… You know… I think… I like talking about weather. Weather is a big one. Weather is a huge one. So what I’m going to do is… Even though we ran this with recompile… And there’s nothing really sitting around in the plan cache…
To make this thing useful… Or to make this… To be useful to us running this. What I’m going to run… Is the… Store procedure for vote type ID… For…
Just alone by itself. And this is going to finish really quickly. And we’ll get this… This nice kind of… Like… This is like a wonderfully… OLTP-ish… Execution plan. We have…
Nested loops joins… And we have a little… Little tops… And little seeks… And just all sorts of nice little things going on. I also want to point out… Something very, very annoying…
About… Uh… Execution plan warnings. If you notice… This nested loops join… Right here… Has this red X over it. Right?
The sassy red X. And if we look at the… We look at this operator… We look at the tool tip for it… It’s going to tell us that we don’t have a join predicate. And this is so absolutely wrong… Because we have a seek here…
And the seek predicate… Is looking for… Is seeking to a very specific… Owner user ID… In the post table. And…
This is searching for… A very specific user ID over here. So any rows that come out of this seek… Because the seek is going to be coming from… User ID values over here. So we’re going to pass out…
One user ID at a time… To the nested loops join. That nested loops join… Is going to go down here. And because this is… An apply nested loops… Right? We have this outer references… Marker in the tool tip.
Which means it is apply nested loops… Not a regular old nested loops join. What they… What some might call… A naive nested loops join. Because we have this… Outer references thing here… We know that we are doing…
What’s called apply nested loops. Which means we’re taking… Basically one… Like one user ID at a time. We’re taking… We’re putting that through the nested loops. We’re going to seek here… And seek here for that same…
For that same user ID. And then we will… Whatever we join together here… In this nested loops join… Is going to be a match. Because we are searching for one at a time…
From these two things. So this happens very, very quickly for us. Right? And that’s pretty good. And now we’ll actually see… For vote type ID 1… Things be a little bit better than 15 seconds…
Even though we’re using an execution plan… That was not… That did not… That SQL Server did not optimize… Specifically for vote type ID 1. Amazing, right?
When we use a plan… That was created for a different parameter… This actually finishes a little bit faster… Than it does when we come up with an execution plan for it. Specifically for that vote type ID.
Now… This… The operator times here are probably going to look a little confusing. He says, sorry… But why does it say no join predicate then? Because the warning is very naive.
The warning is not aware of… The fact that we are doing apply nested loops… And it’s just kind of dumb.
Sorry. That’s all it is. It’s just not smart. I wish there was a better reason… But it’s just stupidity. Probably something just…
It got implemented by a summer intern… And the summer intern did not… Think about all the marvels and miraculousness… That can occur within an execution plan.
It’s just not terribly well thought out. Most of the time you can ignore it. There is… Like… I think when it first got added… People used to freak out about it.
I think a lot of why it got added at first… Was back when people used to write old style joins… Where they’d write from table, table, table… And put the join condition in a where clause.
Where we’re… Like, you know… It was fairly easy to… Like… Forget a join condition… And sort of end up with like a crazy Cartesian product from things. But, you know…
And I don’t know… Maybe apply nested loops wasn’t around… When this thing got added as a warning. I just don’t know. But it’s pretty poorly done. But, you know… We have this no…
We have the no join predicate warning… Even though… Anything that we seek to here and seek to here… Is going to be a match… Because it’s the same user ID that gets brought out here. It’s just not very smart. So…
Looking at this execution plan… It’s a little confusing… How things go. So… If we look… If we look at the properties of the plan…
We look at the query time stats… We’ll see that… Let’s see… Question… What compat level do you run that DB on?
This is 150. 150. 150. We’re on SQL Server 2019. You don’t mind going to look over here. Oh!
That’s SQL Server 2017. I’m in there… I did not… Get rid of that database. Or I did not get rid of that server connection. Now SSMS is going to make me wait. Stupid SSMS.
If only Azure Data Studio was any good at anything… Other than developer eye candy… I would like to use something other than SSMS someday. I’ve tried other IDEs…
For SQL Server… Like… What’s that? JetBrains 1… Or like… Beaver DB… Or whatever it is…
None of them had the same flavor. So let’s see… There we go… There’s 2019. So let’s go look at… Stack Overflow… Properties…
Options… This is going to be… Compat Level 150… There we go… There we go… Oh, don’t worry… It was my own stupid fault for not… For not disconnecting that server…
When I switched over to use 2019. Yay! Alright? So looking at this execution plan… We can see that… So like… When SQL Server… Runs…
Queries in batch mode… Right? We can see a lot of these… Operators are going to be run in batch mode… Even though this is… This is all rowstore. This isn’t columnstore stuff. This is a new SQL Server 2019… Engine feature.
It’s only for Enterprise Edition… But me being… Me using Developer Edition… Means I get… All the wonders of Enterprise Edition… For free! Ha ha ha! Go take it live to prod!
But because we have so much… Batch mode stuff going on in this plan… A lot of these operators… Are just going to be… Tallying up individual times… That’s a big difference between…
Row mode plans… And batch mode plans… Now… This query plan is going to have a mix… Of row and batch mode in it… We can see that this nested loops join… Is in row mode…
So what we’ll see is… You know… Like all… Pretty much all of like… The accumulated stuff… From here… Here… This sub tree… Kind of rolled up to this nested loops join…
But this hash match aggregate… Which is in batch mode… Does have… Sort of the majority… Of the 8-ish seconds… That this thing ran for in it… Now I know it’s spilled… And that’s not…
That’s not nice… But you can see that… In total this thing ran for… About 8.5 seconds… And if you want to see… Another cool engine feature… With SQL Server 2019…
Batch mode… Oh… Did we still… We still spilled… Let’s give this another run… Wow… Oh… That’s a batch mode spill… Maybe it’s just never going to get better… Are you ever going to figure it out?
No… You’re never going to figure it out… So much for that… So like what I was going to show you is… Under memory grants… What we should get… Is this thing…
Adjusting memory grants… And saying… Ah! I didn’t give you enough… Let me give you more… So… We are just not… We are just… I think just not moving up fast enough…
I wonder how many… Runs… I wonder if I can do this like… A few different times… And actually get… The memory grant… Yay! It only took 4 executions…
To get the memory grant… Right… But now this finishes much faster… Doesn’t it? Now this finishes in a reasonable amount of time… But I want to show you a downside of that… If we go back and we use…
Vote type ID 4… Now we are going to have a different warning over here… That says… We have an excessive grant! No!
And now if we run this again… That will probably go away… And we will use… We will ask for far less memory… And if we go back to this one… We will go back to spilling… So… Nice try!
I guess… But this is going to go back to being slow… Is there a way to tell Dev Edition… No there isn’t… If I wish there was… People have been asking for it… For as long as… There have…
There has been Standard and Enterprise Edition… But Microsoft has not budged… Don’t know why… Don’t understand why… So like the… Like the… I think the… The most compelling theory that I have…
For why… There is no… Button… To make Developer Edition… Act like Standard Edition… Is because they want developers to go out… And get all these secret performance features…
And be able to use… Like fully… All of the programmability features… And they want… Yeah exactly… They want you to taste the good stuff… They want to get you hooked…
On Enterprise Edition… And then by the time… And then if you try to go live on Standard… And everything falls apart… Then…
Well… All of a sudden… Your CPU cores are worth $5,000 more apiece… But anyway… So we just saw… One of SQL Server 2019’s fancy features… So actually this is a 2017 feature…
Batch Mode Memory Grant Feedback… Was a 2017 feature… But with Batch Mode… Being available on rowstore in 2019… It is sort of new to rowstore… You could do all sorts of things…
To fake SQL Server out… To make it think that queries were… Going to get like fully… Like Batch Mode… Batchy Modey on 2017… Even if they weren’t… With like…
You know… Empty temp tables… With columnstore Indexes on them… But… Not here… Not here… We just get it for free… And by for free… I mean with Enterprise Edition… So not really for free at all… Right?
But so… That kind of stinks… Let’s see… The cost jump… Isn’t a small one… Can’t think of how many people… Do that and just think… Okay… I’ll spend… Yeah… I mean… It all depends on the organization… Right?
Some people… Some people might… Find that out… And just switch to Postgres immediately… I wouldn’t blame them… So let’s run… So let’s re… We recompiled vote sniffing… Right?
So we looked at what happened here… When… When vote type ID 4 runs first… And then we run vote type ID 1 next… Right? What happens… Vote type ID 1 uses the plan… For vote type ID 4…
And… What do we get? A plan that runs for about… Seven, eight seconds… And then… Now let’s turn the tables… Let’s run… This query for vote type ID 1…
And we get this plan… Which is a pretty decent plan… On 2019… The plans that I showed you over here… Were actually for 2017…
I should need to… I need to re-screen cap those… Because things are a little bit different… Lee says… We’ve had issues of late… With new performance improvements… For 2019… On our managed instance…
I would love to hear more about those… Please tell me more… And now when vote type ID 4 reuses… So this one… So this actually is a 2019 improvement… So one thing that’s actually very cool…
With SQL Server 2019… Is… We get… These handy dandy… Adaptive joins… Right? I love it…
So let’s look at… What happens… When we post this for… When we run this for a truly… Villainous vote type ID… See vote type ID 5… Is going to get a very very similar plan…
To… What happened… For vote type ID 1… We’re going to have this same sort of… Adaptive join thing going on… Except this one just doesn’t go as well…
So that… When we ran it for vote type ID 1… What happened? Fast. Right? When vote type ID 1 got its very own…
Gym jam plan… Everything was great. Now… I don’t know. We’ll see what happened. Microsoft support turned off…
TempDB recompilations… Which stopped our instances falling over. That is a very bold statement. I would like to hear more about… How they turned off TempDB recompilations.
Do you mean recompilations from temp tables… Or from table variables? Because… Because table variable deferred compilation… Is a new thing in SQL Server 2019.
I would love to hear more about this one. That is a… That is a big sentence, Lee. That is a big sentence…
Some advancements, huh? Okay. Around…
Around table variable deferred compilation… Or something else. Inquiring minds. Still trying to get… If you’re still trying, Lee… You may never… Your efforts may be in vain. I don’t know. It’s all craziness. Ooh.
Ooh. We have… We have a… We have a blog post. Let’s…
Let’s actually bring this up… In the browser… So everyone can see it. Let’s be nice. Let’s be nice people. Ooh.
Joe Sack. Handsome Joe. Oh. Don’t you just love when Joe Sack blogs? I love when Joe Sack blogs. I get so excited when Joe Sack blogs.
He’s like one of my favorite bloggers. So let’s see. Reduce recompilations for workloads… Using temporary tables across multiple scopes. Ooh.
That is a mouthful. Let’s see here. Create or alter outer proc that creates a table and then executes an inner proc. No, no, no. This is fine. This is the kind of railroading that I live for.
And then inner proc will insert into outer proc and select ID. Okay. Let’s see.
We create a temporary table. Ooh. CU5 included a fix for that feature. Yes. It sure did. Lucky CU5. Thanks.
Thanks for that, CU5. The CU5 stuff for the scale UDF inlining was especially troublesome. Temporary tables across multiple scopes. Who would do that?
If you have to ask that question, you have not lived the nightmare life of a consultant who has seen what many, many independent software vendors do to SQL Server. Where you’re like, have you used a database? Do you know what to do with a database?
So let’s see here. The end result is a reduction in unwarranted recompilations and associated CPU overhead. The number of occurrences with the blue line representing batch requests a second and the green line representing SQL recompilations a second.
So that is quite a bit of recompilations up here and quite a low number of batch requests a second here. It’s funny because they share very similar spikes and peaks and valleys in those. And this one over here, wow, you push that way up.
The feature was enabled after we saw improve throughput. Wow. Thanks, Joe Sack. Everyone say thank you to Joe Sack.
Everyone go on Twitter and say thank you to Joe Sack. Let’s see. There we go.
Let’s thank you, Joe Sack. I love Joe Sack. But yeah, they turn that off.
And suddenly our post-deployment scripts would work and the instance would stop falling over to the other node. Well, that sounds like a win to me. Sounds like a big win to me. I would like it if that stopped happening.
But now I have to ask, Lee, what are you doing with temp tables that made your managed instance fall over during deployments? Now I’m fascinated. Now I need to know what’s going on with these deployments.
All right. So when we run this stored procedure now. So we saw vote type ID 1 get a fast plan. We saw vote type ID 4 get a fast plan.
We even saw vote type ID 1 use vote type ID 4’s plan and be okay. But what struck me, what caught me out is just so crazy and odd. Just so bananas.
Is when I run this query with vote type ID 5. This thing takes 2 minutes and 17 seconds. Now the blog post that I wrote about this, I was using a full-size version of the Stack Overflow database where this thing would run for like 15 minutes. I’m using the 2013 version for this because, you know, I just don’t want to make you wait 15 minutes.
All right. That’s bad news. Lee says, nothing special.
I checked this section of the script. It’s the Wild West with those managed instances. Okay. All right. I mean, I’ll believe you on this one. I’ll believe you on this one. If we look at where a lot of the time is spent in this query plan.
This index seek is not slow. This compute scalar is not slow. This index scan is not slow.
I know everyone freaks out when they see index scans. But this index scan is 129 milliseconds. I’m pretty hip to the speed on that. And I’m pretty cool with this one taking 167 milliseconds.
Now, since this join is adaptive, we’re going to see a second potential join down here. But you can kind of tell by the width of this line that it didn’t do any work. A lot of the time in this query is going to get spent here and here.
All right. You can see that pretty well. If we go look at the total execution time on this, we will get a long time.
Long time. Why are you linking to other people’s Twitch streams in here? I’m going to ban you for spamming Coyote McD.
I’m going to kick you from the chat forever. Dead to me. Dead to me. So what happens up here? Something kind of interesting happens where this hash join is running. And let me just bring up the properties of it.
Because the properties of it is where we get all of the information kind of happening at once. So the execution mode over here is batch. And if we look at what it’s up to, we can see that it is a bitmap creator. And it is true that it has created bitmaps.
All right. So we created a bitmap and we use that bitmap down over here in this part of the plan. This index scan and this index scan.
Now, you can see that there’s a fairly bad estimate from one of these. All right. One of them is pretty good.
The other one is pretty bad. But if we look a little bit closer. Oops. There we go. Look a little bit closer.
We have a predicate that wants to probe with this optimized bitmap filter. What are we even doing here? What are we doing here?
We are trying to apply a bitmap filter to this index scan. It is not going well. And actually, you know what? I take that back.
It might go spectacularly well. The problem is that we get a very, very bad estimate because of that. Now, I’m going to stick a link into chat for a very, very smart post. If I can learn how to type.
By the patron saint of SQL Server Performance, Paul White. It’s about batch mode bitmaps. And you can kind of get a feel for just how naive a lot of the cardinality estimates for batch mode bitmap filters are.
And since this hash mode semi-join over here is a bitmap creator and we use a bitmap, we get a pretty bad bitmap estimate. He says, I still don’t fully understand bitmap’s role. Yes.
They are. They can be rather difficult to grasp. If you might help you understand a little bit. Let me grab another link for you. Do, do.
Where are you? There you are. Ha, ha, ha, ha, ha. Where is? Yes. Yes. I just need to make sure to mute myself from there. So, I have a video, an old style video.
An old style video. Over on YouTube. About useful and useful, useful versus useless bitmaps. That might, might help you get some understanding on that.
Don’t watch it now though. Because it’ll just be distracting. And if you hear, if you hear me talking from two different videos at once, your, your head might explode. It might not be the most fun time in the world for you.
So, this is not a particularly good plan for, for vote type ID 5. And it’s not a particularly good plan because of the bad estimate that we get from that bitmap over here. Where way, way, way, way, way more rows come out of this operation than expected, right?
We expect 6,000 and we get, let’s see, 3, 0, 4, 9, 3, 4, 1. So, we get back 3 million. And worse, when we join the 3 million rows from posts to the 8 million rows from badges, we get just about everything.
All right. So, we have another bad estimate. What’s the CPU time on what?
Coyote McD. Be specific about on that. And I will happily answer you. So, we get this adaptive join. And this adaptive join is a join just like any other.
You want to know what the CPU time on this is? Let’s look. Why am I, why am I not saying where you go? There we go.
Yeesh. I don’t know why that took me so long. There you go. So, 11,000 seconds. 11,000 milliseconds, rather.
So, that’s fun. But the elapsed time on that’s a stinker, right? What happened there? What happened to you? Let’s look at it. Oh, that’s not too bad.
It’s not so bad at all. You could do far worse than that. So, we’ve got this adaptive join. And this adaptive join spills because we have just some bad guesses going on over here.
How much it spills? Not terribly bad. There are hash spills, though.
So, hash spills can get kind of weird. But really, and what struck me, I think, most while I was trying to figure out what was going on here is that if we had a better guess, SQL Server might do things differently. If SQL Server had made a good guess about how many rows might come out of, like, one of these, we might see an aggregate over here somewhere.
So, we see an aggregate over here. SQL Server decides to smush a whole bunch of rows down to one row here. But I think if SQL Server understood that we were going to end up with, let’s see, 217292920 with a nine-digit number of rows here.
Because remember that we have to take all the rows that come out of this index seek. We build a hash table here. And then we have to probe the result of this join.
Which, when you have a guess that’s off by 605,000%, becomes quite a chore. So, all the results of the index seek on the votes table, right? Which is correct, right?
That’s an accurate guess, right? That’s 100% there. SQL Server was spot on with this one. SQL Server was spot on with this one. But when we get here, and we have to all of a sudden take the rows from the votes table, and we have to probe into the results of this adaptive join, probing into the 217 million rows, yeah, the 217 million row result of that adaptive join is unpleasant.
Now, it’s unpleasant because that’s just a ton of rows. Like, all of a sudden, like, this thing running for two minutes and 20 seconds makes a lot of sense. Because that’s just a lot of work to do.
That’s a lot of probing to do. That’s an unhappy amount of probing to do. What I thought was very, very funny, kind of about these circumstances here, though, was if we take the recompile out of the equation, right?
Let’s just take recompile out. Let’s leave recompile out of it for now. Let’s run for vote type ID 4, and let’s get this. Wait, no, we do have to recompile the proc because I used it for something else.
There we go. Let’s get vote type ID 4, and let’s run that. So now we have the vote type ID 4 plan. And let’s get the vote type ID 5 plan.
Let’s parameter sniff on purpose. Let’s have a parameter sniffing party, you and me. Let’s all get together and do that. When we reuse the plan for vote type ID 2, what happens?
It finishes almost immediately, right? That runs in about two seconds if we look at the query time stats on that. Two seconds.
So let me ask you a funny question. If you had a query that started showing up on monitoring is running for five minutes or two minutes and something seconds, and you saw that maybe the compile time parameter and the runtime parameter were different, you were like, oh, we got a parameter sniffing problem.
But it’s not quite that, is it? Because if we run this store procedure for any of these queries except vote type ID 5, we get the exact same execution plan that we get when vote type ID 5 runs.
There’s no real difference between them. And these all finish relatively quickly. It’s the same execution plan over and over and over again.
And we’re recompiling all of these. So we’re coming up with an execution plan specific for 1, 2, 3, and 10. But when 5 runs, whoo! When 5 runs even for itself, the execution plan for 5 sucks.
When 5 uses another, even any one of the other tiny little plans, 5 does fine. We almost have reverse parameter stuffing because the plan that we get for vote type ID 5 sucks for vote type ID 5 very specifically. If any other query uses a plan specific to vote type ID 5, it’ll do just fine.
If we recompile this, and we run for 5 first, oops, you know what? We’re not going to run for 5 first. We’re going to run for 1 first because 1 gets the same plan as 5.
It gets the same adaptive join plan. We get all that stuff. And we rerun this for 4. 4 does just fine with this plan. 4 just shrugs it off.
4 is like, you know what? I got this. It’s when vote type ID 5 gets that really, really bad guess. Everything just goes to crap. So how can we fix vote type ID 5?
How can we remedy vote type ID 5? How can we get in there and start messing with things? Well, one way might be a temp table.
All right. So if we create a temp table called votes, and we put that initial part of the join or the initial part of the query that filters down to the vote type ID. Right.
So because remember, Lisa has a query hint. Sure. What query hint? Tell me which query hint to use. So if we filter down to just the vote type ID we want first, what we can do is take the results of just vote type ID 5, isolate that, isolate the cardinality involved there, and then maybe we can do a better job with this query or with this execution plan. Maybe stabilizing that will be a good idea.
Let’s sacrifice one of these things to be vote type ID 5, and let’s see what happens. Now, my computer over there is humming, so I know we did some work. I know we did some work.
And what happens here? Well, that’s pretty all right. Oops. That’s pretty all right. Do an index seek over here.
Do a couple of stream aggregates over here. We insert the results into our temp table over here. The whole thing takes about 1.5 seconds. And now then we have a pretty quick query over here, too.
Now, notice something. We still end up with the exact same execution plan that we had before the temp table. Right.
So what happens in here is nearly identical. We start off with the votes table up here. Here we compute a scalar. We have a hash join. We have an adaptive join. And then we have posts and badges over here.
So we make just about all the same mistakes, but we just don’t have that same terrible performance. Pretty crazy, right? So this is another place where paying too much attention to costs and estimates and all sorts of other things like that can sort of be detrimental to query tuning.
The estimate isn’t as wrong. No, it is just as wrong.
That is off. Well, I mean, okay. So, yeah, that is slightly less wrong, but it is still wrong. It’s not as wrong, but it is still pretty wrong. So it went from 6,000 to – so it went down by – I don’t know.
I’m not exactly sure what an order of magnitude is. I hear it’s a big number. But, yeah, this went from 605,000 to 6,000. So it’s still wrong by a big chunk.
But I don’t know. Like, what would I fix in here taking 1.9 seconds? I just don’t know what I would do in here. And if we go look at the query time stats over here, what would I fix?
I don’t know. I don’t know what I could fix in here to do better. This thing up here is still up to the same nonsense with the optimized bitmap.
The optimized bitmap is still the reason why we get this not good situation here. I don’t think it occurs down here, though. Oh, it does.
Interesting. So I didn’t notice that before, but the optimized bitmap actually gets applied to the badges table this time, too. In the previous plan, we didn’t get that. We didn’t have that extra bitmap-y goodness. So that’s actually a fun new thing that I just noticed in here is the bitmap gets double applied.
I wonder if we have a bad estimate here. Yes, we do. Now we have a bad estimate here. Now we have an estimate of 490%.
In the old plan, this was spot on. So we actually got two bad estimates from the same bitmap. Isn’t that sweet? It’s so nice when bitmaps just work out like that. It’s so nice.
It’s so nice. So let’s look at something a little bit different. So we looked at a couple of possible different ways, or we looked at one way to rewrite this using a temp table up here. I think my main beef with this, though, is if we had to do that for vote type ID 2, if I run the same proc for vote type ID 2, we have to put kind of a lot of rows into a temp table.
Probably more like if this was a highly concurrent store procedure, if this was something that was running a lot, it was like really just like, you know, like a critical part of the application, we could end up, you know, like kind of having to do a lot of work, right?
Like in some cases, like we would, like we might end up having to put a lot of rows into a temp table. This also takes about 10 seconds total, which I’m like not thrilled with either. No, and it’s just, and it’s all spent up here, right?
It’s all up in this top part. So like, I don’t know that I’m thrilled with this. Like, I don’t know that this is like, like, I don’t know that I’m really psyched on the, like, like that for the temp table. I don’t know that I just want this thing like pounding around on temp TV.
So let’s look at a couple different ways that we might be able to rewrite this. Now, this first one was all my idea. This one was mine, I think, at least as far as I know.
I’m going to show you another one from a smart friend. But this one here, we’re going to, so what we’re going to do is rather than, you know, use the votes table to drive the temp table.
We’re going to use the post table instead. So we’re going to use that first join between posts and badges. And we’re going to have an exists back to the votes table to make sure that we really narrow down the number of rows that we care about, right?
So let’s, oops, that’s F4, not F5. And that ends up pretty quick. Oops, I didn’t turn on execution plans there.
Let’s try that again. I’m going to have to drop this P table, right? Can I get an expert witness on dropping a temp table? We’ll just say drop table P.
You know why? Because we can do that. We are live. We are live in dev. We can do whatever we want. We can do what we please. All right.
So that takes about 2.7 seconds. And that’s a pretty reasonably small number of rows, right? Like I’m not going to cry over a 200,000 row temp table. And then if we run this query, just looking for what’s in that temp table instead.
And I’m going to, actually, no, I have to redrop P, don’t I? So I’m going to run that all at once now.
I wanted to make sure that we had the temp table insert isolated to see what that looked like. So now when we run this, that’s about, boy, that varied a little bit, didn’t it? Yes, select 1, 0.
And then this part runs relatively quickly. All right. So we simplified this part. I don’t know that I’m thrilled with, like, this part, this temp table insert. I don’t know.
Maybe I’d stick with the votes one. So, like, I don’t know. Like, so thinking about, yes, select 1, 0. It doesn’t do anything. It doesn’t exist.
So thinking about, like, what I would do with a situation like this, where if I knew that if, like, at some point, like, I could have a query that runs about a second faster and uses potentially more tempDB or have a query that takes an extra second but uses a reliably small amount of tempDB, I might just opt for losing a second. And depending on my system, depending on, like, sort of, depending on, like, you know, the, like, what I care the most about. If we’re just going purely for time, I don’t know.
Maybe I would pick the slightly more abusive to tempDB query. But since we have a choice, we can figure it. Maybe we don’t need to do that at all.
So this was user submitted by my dear friend Paul. My dear friend Paul from New Zealand. And he came up with this query, which is insane and typical of Paul outdoing me in every possible way.
And this doesn’t need a temp table at all. All right. So we’re going to create this.
We have to create a slightly different index in order for this to really shine. But it runs pretty well. Lee says, I realized I’m guilty of getting it fast rather than thinking about cost. Well, you know, don’t think about query cost.
Query cost is a not good metric to think about. You know, the cost that I was thinking of was more related to, you know, resource usage with tempDB. Which, you know, tempDB is kind of made for that.
TemDB is, like, kind of made to take a beating. But, you know, you can certainly run into strange contention up in tempDB. You know, if I really wanted to spend a long time on this, I might try to run, I might try to use, like, O-Stress or something to run a whole bunch of copies of this all at once. And then, you know, kind of, like, you know, see if, like, I could hit some, like, like, what kind of tempDB contention I could hit.
Sort of, like, you know, just, like, running, like, 20, 30 copies of this. Option max.80. Coyote McD, here’s the thing, man.
You have servers where you could use, well, you can’t use max.80, can’t you? You can use max.64. You could use max.64.
TZ says, are the differences between temp tables and table variables any different in newer versions? They are only slightly different in SQL Server 2019. If you, you know what, if you tune in tomorrow, I’ll talk about that.
I think that’s a good topic for tomorrow. So, tune in tomorrow, and we’ll talk about the difference between temp tables and table variables in SQL Server 2019. That seems like a good, that’s, you know what, that sounds like a winner.
Now I’m mad I didn’t think to do that one today. It’s talking about this stupid blog post query. All right, so, with this, let’s see how this goes.
Let’s turn on execution plans, though. Let’s make sure that we get that. And once again, Paul has absolutely wrecked every single thing. He’s a madman.
So, this finishes in 700 milliseconds and doesn’t require a temp table at all. It is kind of strangely written. It is kind of strangely written.
And we do have to force the index here. I forget exactly what happens if we don’t. Yeah, it goes back to using the other index. So, you know what, let’s get rid of that one.
Come on, Pally. Let’s put index on votes. There we go.
Now let’s see what you do. There we go. So, even without the index, so without the index and with just that index in there, we actually, we do pretty well.
And this is without a temp table at all. We do still have this annoying warning on the nested loops join, which is completely wrong, but that’s okay. Okay. But that’s okay.
What we don’t have, though, or what we, actually, more importantly, what we do have. What we do have, it’s very, very important. And this is, I think, what makes the biggest difference in here.
If we think logically about all the things that we’ve looked at with this query and not liked, the biggest one is that SQL Server was not choosing to aggregate any of the join stuff prior to a join. None of the join columns are getting aggregated before we went into the join.
Like, logically, like, you and me thinking about it out loud, like, there’s, like, if we know that a column is not reasonably selective, a column is not reasonably unique, the column is going to have a fair amount of duplicate values in it, we would probably want to aggregate that down to as few values as possible to go into the join.
And that’s what happens here. We seek into the votes table, but then we also pre-aggregate our join column a little bit. If we hover over this, you will see that we aggregated the user ID column from the votes table down to however many, however few rows we could reasonably aggregate it down to.
So let’s see here. We started with, let’s see, 3, 5, 1, 1, 7, 3, 3. So we started with 3.5 million rows, and we were able to aggregate that down to 267,000 rows, which is a substantial reduction in the amount of work we would have to do at join time.
And then this has to do a lot of work. Let’s see. Coyote McD says, that’s a lot of seeking.
Does RCSI make a big difference in lock overhead on this one too? Yes, but let’s see. What would be a good way to…
Show that. You know what? We can just come back over here to this one. We need 4 and 1 and 1 and 4.
So what Mr. Coyote McD is asking about is sort of a follow-up blog post to this, where if we run this, what we’ll get is… So this is one that I think went out yesterday.
It was about how read queries need to take locks too. Right? Read queries take locks.
Unless there’s a lookup in the query. They don’t accumulate locks the way modification queries do, though. They don’t build up over time. They just kind of get taken and released.
Again, unless there’s a lookup in there. If there’s lookups in there, you’re screwed. Locks can hold on for a while. But if we run this query between 4 and 1, the vote type ID 1… Actually, I’m not sure which…
Did we? Yes. We’re going to do the same thing. So looking at this now, this ends up taking a whole lot longer to get those rows in there. Even though it takes 7.5 seconds to put one row into this temp table versus it taking nothing for this one.
Right? And now we could play with it a little bit. I don’t think we have any batch mode operators in here.
I want to double check, though. Because we might get enough of a memory grant connection to help with that. But I don’t think so. No.
So this two stream aggregates aren’t going to be valid for batch mode. Right? They’re not going to be batch mode eligible. The compute scalar is in row mode. This compute scalar is in row mode.
This index seek is in row mode. And this sort is also… So this is all row mode stuff. So we’re not going to get batch mode memory grant feedback on this. We would just get the same crappy 7.5 second plan over and over again.
At least I think… Pretty sure we need that batch mode stuff. Oh, it was a little faster. Did we? Oh, no.
I guess it did. Let’s go look. Oh, yeah. Yes, adjusting. Good. Oh, that’s nice. I wonder what we’re getting that from. What a nice touch.
Thanks, Joe Sack. Thanks again, Joe Sack. I’ll draw another heart on your head later. But what’s interesting, though, is if we run this for vote type ID 1 first… Well, this is faster.
I don’t want to go parallel there. But vote type ID 1 and 4 run much more quickly. And so… But what Coyote McD is getting at was sometimes you do have…
There can be overhead. Let me grab the blog post that he’s referencing so that everyone has it. You don’t have to go searching for it.
The last thing I want anyone to have to do is go searching for things. It is that under some circumstances, the locking overhead of reading data from a table can be particularly loathsome. So one way to test that is to, let’s say, add a page lock hint here.
And we will get… So long as the demo gods are smiling upon me. Well, that could have gone better.
Highlighting was never my specialty, folks. I apologize. I apologize. Demo gods are not smiling upon me.
This is what happens when you go off script. Thanks, Coyote. But at least this part… At least for this one, the index seek was a lot. It was 1.5 seconds before. It was only half a second this time.
So thank God for that. Thank God for the little things. Oh, yeah. That’s fun.
Triple click for a single line highlight. Yes, I know. But I don’t… I’m an old-fashioned guy. And I just…
I just highlight things. I would have messed up the triple click and just… And done something silly there, too. Anyway, it’s been like an hour. And I need to go hang out with my kids, apparently.
So I’m going to get going and do that. If we have any final questions, anything… Anything you want to ask about, know about, SQL Server stuff, you can…
Now is an okay time to do that. Let me go back over to… This one here. And let’s go look at… This.
All right. I’ll hang out here for a minute. See if anything comes into chat. Let’s see.
Thanks to one of your videos, I found a deadlock in a database, which I solved with an index. Nice. All right. Mr. P, you’re welcome. Mr. Pshaw, you are absolutely welcome.
Lee says, thanks to the stream. No, leave. You can always ask more questions. That’s what I’m here for. If you don’t ask questions, I don’t have answers. Isn’t that sad?
Just all these things locked away in my head that I don’t have answers for. That I have answers for. That I just can’t use.
All right. I will try to get on a little bit earlier tomorrow so you fine folks in Europe don’t have to stay up past drinking time to hang out with me.
But I’ll announce it on the old Twitter and whatnot when I want to go live. So I’ll see you all tomorrow. Thanks for joining me. Take care. And, you know, be excellent to each other.
As a wise man once said. All right. adios. Audrey. So, see you.
I don’t know.
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
In this video, I found myself navigating through various challenges and learning moments. Initially, the technical issues with PowerPoint and SQL Server tools like SQL Prompt took center stage, but as we hit the live stream’s 15-minute mark, things began to settle down. The community started to engage more actively, and it was a delightful shift from being the one asking questions to having an audience ready to share their expertise. The discussion around querying XML versus JSON highlighted some interesting points about how Microsoft supports these data types in SQL Server. While JSON is gaining traction, XML remains deeply embedded in many core functionalities of SQL Server, making it a more necessary evil for certain tasks. The conversation also touched on spools and their limitations, with a particular appreciation for the window aggregate spool as highlighted by Coyote McD. Overall, the stream was a great opportunity to both learn from others and share my own experiences with SQL Server.
Full Transcript
Thank you.
Do-do-do-do-do. Do-do-do-do. Do-do-do-do. Everyone can see me trying to hastily figure out how to get this slideshow working the way I want it to. For some reason PowerPoint is fighting me at every turn.
Constantly fighting me. It’s fun. It’s so much fun.
I am fun. I am so much fun. I wish I was more fun.
I am so much fun. I wish I was fun like I used to be fun. Well, that’s sort of working. Yeah.
Woo-hoo indeed. So that’s just happening way too fast. That is aggressively fast. I don’t understand what… Hang on. Make sure that’s safe. Let’s try that again.
No, that’s way too fast. Well, what are you doing? I don’t know. That’s five seconds, right? 05. Let’s try it for… I don’t know. 20?
Maybe 20? I use Excel instead of PowerPoint. Yes, if only I had… No. What are you…
This thing is bonkers. All right. Let’s… Oh, I’m not recording this one.
So you have to stay. I suppose I could record it. I do have a record button. But I’m going to wait…
Timing? Uh, I’m going to wait and see… I’m going to wait a couple minutes because right now I have… I have two eyeballs, but… Without some more eyeballs, I don’t know what I’m going to do.
If you want the slides to advance using the same speed, click Apply to All. Apply to All. Transitions.
Good morning. Good morning, indeed. The beautiful people are here.
My goodness. My goodness. What am I going to do with all of you? You’re all too much… You’re all too… You’re just too much better looking than me. It’s painful.
All right. Let’s see. Do I… Do I look normal? I do look normal. Wow. I do look normal. Great. What time zone are you in?
I am in… Eastern Standard Time. It is… 11.05 AM. As God intended. I am streaming head to head with Brent.
Oh, boy. I am streaming head to head with Brent. Well, can’t win them all. I think he saw me tweet yesterday that I was going to go live and he decided to sabotage me, I guess.
His ended. Whew. Well, I got lucky then. All right. I take it all back. He did not decide to sabotage me. Well, I hope he wrote a really great post while everyone watched.
I hope it was life fulfilling. I hope everyone learned something. All right.
So, the purpose of this here… Well, this isn’t slideshowing at all. This is doing the opposite of slideshowing. This sucks. I don’t understand why…
Is that minutes? All right. Let’s do that to zero. I think that was 20 minutes. Let’s try this at 10 seconds and let’s apply to all. And now let’s… Let’s see.
I’ve been putting your stickers all over bathrooms in Columbus. I hope that you use the ones with my phone number on them. And preferably the ones with my headshot. Because those are the ones that are the big draw in bathrooms.
Zeus, once again, this is something you have to fix on your end. There’s buttons where you can adjust the quality. I’m not going to stop streaming in 1080p.
Because you can’t push a button. I’m sorry. If you need to watch it later, if you need to watch the recording later, I totally, totally understand. But that is on you to do, my friend.
You’ll have to take a heroic action of Zeus-like proportions in order to look at a lower stream. He seems famous, but who is this Brent? Well, Brent is someone who can figure out how to get a slideshow to play on repeat.
So that’s nice. Slideshow. Let’s see.
From beginning, custom, or it’s record. I don’t want to record. I just want you to… I want you… Loop continuously until escape.
That is beautiful. That is what I want. There we go. Let’s try this all over again. Let’s also turn this down from 10.
That might be a little excessive. Apply to all. Yes.
Yes. Yes. Yes. There we go. There we go. Now we’re cooking.
Five seconds seems a little fast, though. I’m going to get this one day. In the meantime, if anyone has questions about SQL Server, you know, general fun… If anyone wants…
How about this? If anyone would like to tell me what it’s like to be able to go to gyms or restaurants or bars or enjoy being outside, I would also appreciate that. I would watch that stream.
I would watch that stream happily. Happily watch that stream. Food is amazing.
I know it is. I know. Food is wonderful. I remember when I could eat food. But now I’m old and gymless and thinking about calories seems to make me fat. Say something nice about querying XML.
You sure do it a lot. The nicest thing, Michael, about querying XML is knowing that I am in your good company. That is the nicest thing.
Have you done a stream on human events? I have… So, over on YouTube, I have a bunch of recorded stuff about SP human events. Underscore.
Thunderous underscore human events. And earlier this week… Geez, time is so… Fungible. Right now. Yeah.
I think earlier this week, I did a quick live stream of working through a few issues in SP, thunderous underscore human events. But I haven’t done one on using it. The only reason that I haven’t done one on using it is that a lot of the times, getting the demos set up to properly show you how things work is a little time consuming.
You know, you got to create indexes and, you know, set up the blocking and all this other stuff. So, I mean, it would be…
I would have to… I would really have to figure out a way to streamline it in order to make that sort of a compelling stream to walk through it. You know, it’s not like a monitoring tool where you can, like, pre-bake all the data in there and then just click around through it and be like, look how awesome it is.
But, you know. I’ll work on something because that is a fun tool. That is a fun one.
Let’s see. Are there any SSMS plugins you would recommend? Geez. I don’t really use… I don’t really use anything.
I guess the biggest one for me is SQL Prompt. And, you know, I love SQL Prompt for like a very specific few things. But, you know…
And it’s not like I think it’s a bad tool, but man, like the more stuff they add into it, the more things just get very, very strange with it. And there’s also a lot of stuff.
There’s like these shortcuts in SQL Prompt. And if you are in the middle of typing something else and you accidentally auto-complete a shortcut… Yes, Red Gate stuff.
If you accidentally insert a shortcut and you try to hit Ctrl-Z to get rid of it, it won’t Ctrl-Z and leave. You have to like stop and then like delete this whole script that popped up to like create an index…
Create a user or create an index or something. It’s very strange. The one that lets you search schema. Fortunately for me, I only have one schema. So, I don’t really need to…
I don’t really need to search through too many of those. There’s like 10 tables in it too. It’s wonderful. I have almost no searching to do. Double escape would allow to Ctrl-Z out of it.
Yeah, but it doesn’t… As far as I know, that doesn’t undo the text that just popped up on screen. But you know what?
I’m willing to try it. So, let’s see if I can recreate this fiasco. Let’s go into SSMS. Let’s see if I can figure this out. If you…
Because if you have a solution for me, I will… I will give you all of the free streams for the rest of your life. You will have all of my streams for free. My family and I will be eternally grateful.
Let’s not recover that. Let’s start with a new one. Start with a brand new. Brand new. Well, I didn’t…
I didn’t really want you to show up. But here, we’ll start with this one. We have many things going on. Many, many things. You can all see SSMS, I take it. And you can all see the fact that I have SQL prompt installed.
So, let’s buy ourselves a little real estate over here. And let’s say… Well, let’s use a database that has something useful in it. Let’s say use stack overflow.
And let’s say create index whatever on. And then… Where I usually get messed up is with something like this. So, this is a good example of…
Of a shortcut script that they have. Where if you type in… If you type in C or whatever, You’ll get this thing where it says create clustered index. And they have this weird thing in SQL prompt now.
I’ll show you that afterwards. But let’s say that I hit tab to auto complete that. I get this whole thing, right? And if I hit control and Z. Which you can’t…
You can’t see me hitting. But I am furiously hitting control and Z right now. That doesn’t go away. So, I’m going to see if double escape actually does it. No. So, I’m hitting escape all over the place.
And I still can’t get out of what this thing just popped up. So, control Z doesn’t do it. I have to go and delete it. It’s very, very strange. Right?
Very, very strange. So, that’s fun. Wait, maybe that did work. Let’s try it again. Ooh, so the… Oh! Double escape then control Z. There we go. Alright.
Now, see, thank you for solving that problem. I will now give you a lifetime membership to my free live streams. That is wonderful. I’m glad we have that cleared up. Alright. Let’s get back into… Let’s get back into our slideshow. It’s enough management studio for one day.
Apparently, this is a live stream where I ask you… I ask you all SQL Server questions. And you give me answers. This is great.
This is totally just turned the tables on you. Now you’re all the live streaming stars, right? Beautiful.
Beautiful. Alright. So… What I’m gonna do… Is since we are about 15 minutes in, we have a decent spray of people in here. I’m going to hit record.
I’m going to hit record. And… We will begin. We will begin with things. Now that I have PowerPoint figured out, and I learned something new about SQL Prompt, I feel like…
I feel like we’re in a great spot. We’re in a great place today. You and me, all of us. We’re in a great place. So… Who wants to ask questions about SQL Server? Who has questions… Of any kind?
Really, I’ll take anything. What do you think is worse? Querying XML or querying JSON?
Yes. So, I think… You know… JSON is a tough one.
Because… I don’t… I just haven’t… I just haven’t had to use it a lot. So, it’s really tough to say.
I don’t… Like, when I look at JSON, I’m like, I don’t mind you. Like, looking at it. But, you know, when also at the same time, like… You know, for all the talk that Microsoft has about like, JSON’s the future.
We got all this JSON. We got all this JSON stuff. We got JSON, JSON, JSON. We support JSON. You know, it’s like… Nothing that they use internally is in JSON.
Like… Like, query plans are still XML. All the extended event crap is XML. The DTS package stuff is in XML. The way that SQL Server Server’s maintenance plans is still in XML.
And I got… Like, that’s just never going to change. So, for me, like, natively working with SQL Server, I just have to use XML. If I don’t use XML, I got nothing.
Right? But if I… Like, JSON, it’s just like, you know… I just haven’t run into anyone like… Eric, we have a tough JSON problem. But, boy, oh boy. Do I run into a lot of people who are like, we have an XML problem.
Like, I don’t know. Are they just behind? No. They just got support for JSON in 2016. And, like…
How can you, like, fundamentally change query plans and extended events and all these other things? And… Like, you can’t backward… Like, just automatically make, like, SQL Server versions going back over a decade.
JSON compliant. But I don’t know. Like, I just have to use XML for stuff. I find myself having to use XML.
But I don’t find myself having to use JSON. The one thing that I would say I think JSON really wipes the floor with XML on is around indexing. So, like, you can have a…
Like, at least the last time I messed with it, I remember that I could have a computed column that was like a JSON expression. But you can’t have a computed column that’s an XML, like an XPath expression. You have to create a scalar valued function and put the XPath expression in there and then you can do it.
But then you have a scalar valued function in a computed column and you break so many other things on your table. And, like, I see people offer this as a solution on, like, blogs and other stuff quite a bit. And I’m like, that’s…
Like, with no warning. With no warning about all the other terrible things that can happen. They’re just like, eh, you can totally do it. Go ahead. Go crazy. Coyote McD.
Coyote McD. I’m sure you are a pretty coyote. Ask, what’s your favorite spool? The window aggregate spool is my favorite spool. That is the batch mode version of what windowing functions use.
And I think that’s my favorite one. All other spools must die. I hate them all.
I don’t hate them. They’re just, you know… They don’t keep up with the times well. There’s, like, some very important optimizations in TempDB that spools don’t… Stools aren’t…
Stools aren’t governed by. Like, and I know Paul White has mentioned a few times that, like, some of the work that spools do behind the scenes is row by row. So, like, there’s no, like, bulk loading into spools, I think, or something like that.
But, yeah, it’s, you know… Like, I understand why they’re there. I understand the point of them. I just wish that spools would get the kind of optimization love that, like, the rest of the SQL engine has gotten.
And… And… Alternately, or alternatively, depending on how much plaid you wear, where in the country you live, I hope that as SQL Server moves into the future…
And I know this is a tough one, because so many people are going to be stuck on older versions for a while. Uh, whether it’s vendor lock-in, lazy, like, you know, lazy places of business or whatever. But, uh, SQL Server 2019, which at some point will be an older version…
At some point, SQL Server 2019 will be the older version. Uh, I think that accelerated database recovery is going to, um, hopefully… Hopefully offer some engine improvements where we could get rid of spools.
Because the way it works… And accelerated database recovery is really cool. Like, I was… Like, uh, my friend Forrest has a blog post about it. Uh, let’s see if I can…
I’ll go find that. And… Because I want to show that to you. And I… I believe… At least the last I checked, uh, Google Chrome is safe here, because I don’t have it synced for anything. Uh, but let’s just check, uh, Forrest McDaniel Acceler…
Oh, I did that all wrong. Data… Database…
Uh, recovery… I apparently need recovery. But, yeah, there we go. So, the nice folks at Redgate, uh, had my friend Forrest. And Forrest, I want to point this out. Um, Forrest, if you…
Like, let’s… Let’s… I want to open this image in a new tab. And I want to show you… This is Forrest. Forrest is the nicest human being on the planet. For…
Like, I have no business being friends with someone this nice. He is the sweetest person that I know. He also looks like a very young Connor Cunningham. So, what I want to do is, uh, show you Connor Cunningham. I think Forrest might be Connor Cunningham’s, like, illegitimate son or something.
Uh, but let’s just look at Connor Cunningham’s SQL Server. Where are our images? There we go. Where is a nice… Where is a big picture of old handsome?
Let’s get him up there. Get up on the screen. Come on, don’t be shy. Let’s open image in new tab. Let’s zoom in. So, I think Forrest and Connor could be related. I think there’s, like, a definite, definite chance.
They even have the same bangs. It’s amazing. I think there’s a definite chance that there is, like, some shared lineage here. Like, I think they could be the same person.
They could be… They could be family. Right? Look at that. They could totally be family. But, uh, Forrest wrote a great article on accelerated database recovery, how it works. It’s over on Redgate.
Let me stick the link into chat for everyone. There we go. You all have that. You can read that at your leisure. Don’t start reading it now, because you won’t pay attention to me. And, uh, well, you don’t have to pay attention to me anyway.
You miss relatively little paying attention to me. But, um, yeah. So, uh, accelerated database recovery is very cool. And what it…
The way it works is, uh, it takes the, uh, the tempdb pressure out of opt… Like, when you have… Normally, when you have an optimistic isolation level, like recommitted snapshot isolation or snapshot isolation, all of that stuff goes to tempdb.
The rows get versioned to tempdb rather than in user databases. With accelerated database recovery, we have what’s called a persistent version store. And the persistent version store is local to the user database.
And what’s really nice about that is that when you have a version store, when you’re keeping committed, like, like, you know, in terms of transactions in flight in this persistent version store to allow, like, very quick rollback, you also do a lot of the work that spools are doing.
So if we think about what spools do either by, you know, um, like, uh, for Halloween protection, having a certain set of rows, uh, available to read from, like, like, we, we spool, we, uh, we take, uh, we take rows that we’re going to modify, and we spool them to tempdb.
Uh, and we read from that, that source of rows rather than just reading the base data over and over. So we don’t run into, like, weird race or loop conditions where we keep, keep reading the data and, like, accidentally updating the same rows over and over again.
Uh, so if, like, having that stuff local, we could actually re, like, replace needing to spool the tempdb with the data that’s in the persistent version store. Um, so I think that’s, you know, that’s, that would be a really cool use of the feature, uh, which means that it’ll never happen.
Anything that I think would be a, is a good idea for accelerated database recovery or for anything in SQL Server, it means it’ll never happen. It will never get implemented.
Like, my best idea was if you have an eager index pool, you should get a missing index request for it. Nothing. I’ve been saying that for years. What did I get? Nothing. Book kiss. No one listens to me.
Let’s see. Chris asks, in a Greenfield project. Ooh. I don’t know. I did it. I think I did it a girl with the last name Greenfield once.
She was nice. She was from Long Island. Uh, would you go for 2019 with the latest compat level or something else? Uh, yeah, I probably, I would probably go with, uh, two.
Yeah, I would probably do that since then. Like you have nothing to compare it to. I would probably do that. And, uh, at the very least you would be able to properly prepare your workload for, uh, all the cool new optimizer stuff that SQL Server 2019 has.
Um, you know, you would be able, like if you don’t have legacy code that might just blow up in your face, you know, you can, you can really, uh, like starting fresh is where I would definitely want to do this in the same way that, you know, when people ask, you know, about starting fresh, uh, fresh application, like for a fresh, you know, absent anywhere, you know, like, I think really that’s, that’s where, you know, if you want to use like Azure SQL DB or something to take all like the sort of management crappiness out of SQL Server, that would be, that’s good for it.
Azure SQL DB doesn’t like, like, like back fit to a lot of existing applications. And it doesn’t because it takes a lot of the really crappy features out. Like a lot of like the, like those awful, like I’m a developer, I see a squirrel buttons that they want to press to do terrible things with SQL Server with, and then cry about performance later, Azure SQL DB is just like, no, you can’t do that. Nope. No, you can’t do it.
No, you can’t have that here. Nope. Sorry. You’re cut off. You can’t do it. So there’s a lot of reasons why I like Azure SQL DB because they’re just like, you can’t do that here. You know, we don’t want you here. You’re not allowed.
Uh, so like, I like the way that it limits people and like sanity checks them. It was like, but I want to do this. I’m like, no, no, you can’t. It’s not allowed. So I like that about it.
Uh, yeah, Chris, but look, Stack Overflow, they are a bunch of very, very smart, smart kids. They are very, very smart. They are like just incredibly gifted, smart, talented developers. But what they remind me of is when like, like the gifted class at your school, when they would allow them to like have a day without a teacher and do their own thing, they just don’t have anyone saying no to them. They do a lot of crazy stuff behind the scenes that most people wouldn’t normally do.
They do a lot of stuff at scale that most people just wouldn’t normally do. They do crazy and thing, insane things in the background. And a lot of, and a lot of the stuff they’re hitting is a result of that.
A lot of the weird edge case stuff that they do and they’ve done is a result of that. So it’s not stuff that I think most people are going to hit or see with SQL Server 2019. I think that a lot of the people who start, who start using SQL Server 2019 from scratch and are able to, you know, or, you know, hopefully have some sanity checks in place about what they’re doing aren’t just aren’t going to hit the problems that Stack does.
Like, you know, I, I love them. You know, Nick Craver is an incredibly smart person. My friend, my, my, my dear friend, Taryn, who is not just a gifted DBA, but also a gifted woodworker.
She makes the most beautiful cutting boards I’ve ever seen. Like they, they do, they’re, they’re great. They’re fantastic.
But man, like they have a very, very tough, tough infrastructure to manage and to deal with. And the scale that they’re at are just not what most people are going to be at. Like if you like, like, if you want to talk about web, web scale, Sack overflow is web scale.
Like they are, they are big. They are burly. And, you know, um, well, I, I, I sympathize and empathize and every other thighs. I mean, not, I mean, maybe not my thighs, but lots of other thighs is, uh, with what they’re going through.
Cause it, it does suck. You know, it’s like a lot of people that aren’t going to be there. Um, this, they’re not going to hit that point, not going to get that big. So, I mean, I wish you all the, I wish you that all the continued success in the world that you will get that big, but I don’t know that you’re going to get that big, at least big enough to hit stack overflow problems.
Cause like, you know, it’s crazy. When would you expect, Ooh, that’s a good question. When would you expect row compression to be better than page compression? So this is a, this is a good question. And, uh, fundamentally what it comes down to is data uniqueness.
Uh, so wrote, so the funny thing about page compression is that, uh, it will first try to apply row compression and then it will go through some other steps to try to further compress things at the page level, uh, using fancy things like dictionaries.
And, uh, I forget what the other thing is called, but, uh, what it’ll do is it will try to go and replace do like re like repetitive, uh, parts of data with expressions. So you can, you can, if you have very, very repetitive data, you can, you don’t have to store like say, you know, a million zeros.
You can just say, I have the value zero a million times. So row compression works really well for, um, you know, like dates, numbers, uh, to a certain extent, some, some strings, depending on, depending on a few things that I don’t want to get into, but, uh, row compression typically works well for more unique data.
Whereas page compression tends to get better, um, as you have more repetitive data. Uh, the other, the other crazy thing about page compression is that at some point it might give up trying to compress pages and just fall back solely to row compression.
Uh, so, you know, really, you know, take a good, hard look at your data, look at, um, you know, kind of how unique or not unique things are. Um, take a look at, I don’t know.
I don’t know. Sometimes testing it is just the best way to do it. Right. Uh, but let’s see my friend, my dear friend, another dear friend of mine, not quite as gifted at creating cutting boards, but very, very gifted at SQL Server things and making cocktails.
Andy Mallon. Uh, where is his GitHub? Where is Andy’s GitHub?
Does he have a link to it here? No, he doesn’t have a link to it here. Andy Mallon SQL Server GitHub. There we go. So Andy has a presentation.
Look at that handsome fella. I know drew is over there drooling if he’s still here, but Andy Mallon has a wonderful presentation on compression. Let’s see.
Where are you? Automation. Blazing performance. Ooh, I should read that. Shortcuts when to use. Where is the compression one? No.
Try to keep it family friendly. Ah, there we go. Demystifying data compression. There we go. There we go.
So there’s a link to that. Uh, Andy, uh, does a great job presenting about it. If you just look at the PowerPoint, you are doing yourself a disservice. You should definitely, definitely, uh, catch him do it.
Well, I mean, I don’t know. I don’t know if live and in person is going to be an option anytime soon. But Andy does speak at user groups pretty regularly. If you don’t already follow him on Twitter, uh, and there’s not enough dogs and food and cocktail making in your life, well, Andy’s a pretty good, pretty good choice to go and follow.
That’s why I follow. He’s my fashion icon. I just can’t afford those shirts.
Um, really, yes. Yes, Drew. Really good.
Really good. But yeah, so that’s a, that’s a good presentation on it. Um, you know, it’s a shame that, uh, the only place to get, uh, so this, uh, this guy, Lynchie Shea, uh, actually used to be part of the SQL Server user group. Um, uh, or rather, actually used to be the organizer of the, uh, SQL Server user group, uh, in New York City.
Used to blog over at SQL blog, which is like permanently offline now. So I’m gonna try to find the link. So I can put it into chat.
But I have, I have to, I have to go through. Oh, do I even have it anymore? So the only way to get to, uh, Lynchie’s stuff is on, um, the, the internet archive. I’ll have to go and dig that up.
Cause I don’t, I don’t think I have it bookmarked anymore. Yeah. I don’t. Darn it. Man.
Man. All right. I’ll have to go back and find that. So like the only way to get to, um, the only, only way to get, uh, to his stuff. He goes, he, he wrote about a lot of stuff. So Lynchie, uh, works for a big bank and, uh, Lynchie used to, um, run, have like, like at the time, very, very big servers and could run all sorts of crazy load tests with all sorts of crazy, all the crazy features that SQL Server was coming out with.
And just had access to like stuff and his company let him blogged about all these things. Um, so, and like, he just had like really cool stuff about, um, ways that compression helps, hurts, like, you know, when it’s good, when it’s bad. Uh, I’ll have to go through and dig that up somewhere.
Cause that, that’s, that was, those, those are still, uh, because compression hasn’t really changed since like 2008 or 10. So that stuff is all pretty reliable. So I would, I would definitely, I’ll, I’ll, I’ll, I’ll, I’ll, I’ll, I’ll dig up links to that through a web archive and, uh, I will post them along with the video content since I can’t find them quickly now.
And no one wants to sit here and watch me go through archive.org looking for stuff. Let’s see. Do I have some words to say about file stream?
I have terrible words to say about file stream. Don’t stop putting that stuff in your database. You can’t performance tune that stuff. Stuff is not, not good for you.
Um, don’t put your blobs in the databases, put stare, store links, store like paths to blobs, and then have the thing go find them on, on discs. And I know that, I know that makes some stuff difficult. Like you, like it’s, it’s like if you back up the database at a point in time, you don’t necessarily have the files backed up at a point in time, but man, gives me the, gives me both the heebies and the jeebies thinking about file stream in the database.
It is, you know, it’s again, it’s just developer squirrel stuff. It’s like, God, why, what are you doing to me? Like we have a query that’s going slow.
It’s touching file stream. I’m like, good luck. Good luck. Go. Show me. What’s the query plan for that? Just skulls.
It’s a bunch of skulls. Someone at our place did yuck. Surly dev, I understand why you’re surly now. I understand the surliness. I would be surly too, if I had to deal with file stream.
Yes. Just store a reference or path to file. That’s the way to do it. Oh, everyone should judge Microsoft. Microsoft is there to be judged.
When you’re paying $2,000 to $7,000 a core for a piece of software, you should, they are there to be judged. You’re not getting coupons from them. That is, that is the ultimate judge.
Like, people pay small sums of money to see my training and they give me feedback. And I am perfectly comfortable with being judged because they pay for a product and I want them to have the best possible thing. And, you know, I think the next round of training will be even better because I have an even better setup.
And, you know, I learned a lot of stuff from the first round of training, like, you know, recording it all nonstop over the course of a few days at the beginning of a pandemic. It’s probably not the ideal recording circumstances, but, you know, it’s okay. It’s okay.
Am I a Blackadder fan? No, I don’t, I don’t, I’m not, I’m not very big into a lot of the humor that gives people credibility in IT circles. I, you know, and you know what, it’s not because I watched it and didn’t like it.
It’s because I heard references or like people quoting this stuff so much that by the time I went and tried to watch it, I was like, oh, I know it’s going to happen. It’s like, oh yeah. Oh, yeah, look at that.
I know that joke. So it’s like, like, not that I didn’t like, not that I don’t like it. It’s just, I, the, the joke got ruined for me. Right. It’s like, it’s not bad.
It’s just, man. It’s like, I, I, like, like Doctor Who, Monty Python, Blackadder, Mr. Bean. Like, all of the, like, all like, like the, like the, like the nerdy, like, you know, like the nerdy fetish humor comedy stuff that like, you know, was very, I don’t know.
Like, like pointed commentary and sort of like a little bit transgressive. It’s just like, by the time you watch it, you’re like, oh yeah. Seen it.
Know what happened there. I don’t think it’s bad. It’s just, I wish that I, I wish that I hadn’t heard all the jokes ahead of time. Yes, I am showing all of Andy’s source code.
Mr. P. Shaw says, have you done anything with policy based management? Not, no. And no one else has either. It is, it is a pretty underused feature.
Like, I understand what it’s there for, but, so like, my story is, my story is with, with SQL Server is, I was mostly a developer for my career. I didn’t have to do a lot of DBA type stuff. And then, my, my big DBA job, which I didn’t have for a terribly long time, because Brent hired me, was at a relativity shop.
And if you don’t know what relativity is, it’s eDiscovery software. It is like the eDiscovery software. Like, if you’re not using relativity, you are probably doing something wrong.
But I was a DBA overseeing, I don’t know, like 100, 150 terabytes of data. I was the only DBA. It sucked.
But, yeah. And there wasn’t, there wasn’t a lot to do with policy based management there, or, or other things like that. And, you know, so like, I mean, most of what I did was, you know, making sure that the servers were alive, doing, doing like, you know, making sure like backups, like boring stuff, like stuff that DBAs just shouldn’t, like, like the reason why DB, like the boring stuff that DBAs are going away because of, where it’s just like, you know, like, like backups restores, setting up new servers, all that stuff. And that like, and like, I realized that that wasn’t really my love, like, like, like managing the high availability, all the sort of like infrastructure stuff, I realized that that wasn’t my love.
I loved, I love performance tuning stuff. So I would, you know, every chance I got, every chance I got, I would, you know, I would go back into index tuning, I would go back into looking at like the queries people were running and trying to tune those. It was like, that was always what I was drawn to, was never the infrastructure type stuff.
And so things like policy based management, well, I’m not like against them, I’m sure they have uses. I just haven’t seen a lot of people use them, like even from on the client side, like people who have DBAs who do love that stuff are like policy based what? A policy says what?
So yeah, I mean, no, I haven’t really done anything with it. I don’t really know anyone who does. I don’t, I don’t, like one way to really judge, I think the usefulness of a feature is to go and look at how many blog posts there are about it. If you’re just not seeing a lot of blog posts about it, then it’s really not, it’s probably really not catching on all that much.
Because when people get their hands on a feature that they either love or hate, you’ll see a lot of writing about how much they love or hate that feature and like, you know, various like good things or problems with it. But like policy based management isn’t something that I saw a ton on. So, I mean, not me, sorry.
So Lee Dev says in series four, there’s a character called Captain Darling. So this is a good example of things. Rob Farley, the most famous Australian in all of Australian history. He’s actually the first Australian to be born outside of a prison.
God bless Rob Farley. He yells Captain Darling or something about, yeah, how are you darling at me? In an Australian slash Englishy accent when he sees me.
And I miss seeing Rob Farley. I want to see Rob Farley live and in person again. So he can say that.
And then I can skip watching Blackadder because I’ve heard Rob Farley say that line to me. But you can say that to me too. I don’t think Rob would mind all that much.
Rob would probably be okay with it. Good old Rob. Good old Fob Farley. What a guy.
Let’s see here. Cool. So, yeah. So stuff going on with me. I don’t know. Maybe I’ll fill some dead air here rather than just thinking fondly of Rob Farley.
Next Friday. Next Friday. The 26th. I will be live streaming an online class. That’s going to be my advanced performance tuning material.
It’s going to be all the stuff that I was supposed to do for my SQL Saturday Chicago pre-con. It was supposed to be, I don’t know, three months ago now that obviously for reasons, got postponed and then canceled. So it’s canceled now.
There’s no thing in August anymore. But you can catch me live and in person doing it next Friday. It’s going to start at 10 a.m. Eastern. You can buy a seat for it. There’s a slide coming up.
Excuse you. That was a very big truck. There’s a slide coming up that has a link to it. And you get free access to all my videos, trainings, along with that purchase.
So if you want to come spend all day next Friday with me, you sure can do that. Coyote McD says, if you were hiring a junior DBA, what would you look for? Well, you know, junior is a funny word.
Um, because it’s sort of a loaded word, I think. So when you’re hiring a junior DBA, you’re not really, you’re not really hiring a DBA, right? You’re hiring someone who is curious, who is database curious.
Someone who is interested in databases. You can’t, like most of the time when you’re hiring a DBA, it’s a junior DBA rather. You’re hiring a junior DBA.
It’s, it’s, it’s like you just, you need someone who is smart and curious and responsible. And, you know, uh, let’s see some other, some other HR words, dependable, reliable, trainable, all that stuff. So, yeah, there’s, you know, there’s stuff that I would look for in the person.
There’s not necessarily something that I would look for in the qualification. Uh, you know, if, if, if they are like an intentional, Mr. P. Shaw has a good point. There are many, many accidental junior DBAs out there.
And, um, you know, by the time they’re getting hired, they’re not, they don’t, they don’t want to be junior anymore. They usually like kind of grow into that role. Um, yeah, yeah, there we go.
Meeting bingo. I love it. Proactive. That’s a good one too. That’s a good one. That’s a beautiful one. Uh, but yeah, so most of the time, you know, if I’m, if I’m looking for someone who I need to, or if I was looking for someone who I would need to fill junior DBA responsibilities, I don’t know what that I would ask them much about SQL Server. You know, I would probably ask them like, you know, uh, what, what they’re currently doing, what they like about databases, uh, you know, like what their current skillset is, how they think about it.
I think that might apply to databases. I’d ask them if they’re like, you know, if they, if they currently read, uh, you know, any of the, the vast, vast many SQL Server blogs out there, uh, things like that. You know, just like, you know, I would probably just want to get to know them as a, like, is this someone, like, is this someone I can work alongside and teach things to easily?
Is this someone who will go out and explore things and come to me with like questions? Not like, and not like, like spoon feeding questions, but like, you know, like good questions, like, Hey, I read about this and I got this far with it, but I’m kind of stuck here. What’s next?
Like, like, those are the questions. Like, those are the things that, uh, that I would want to like get to know, get to know about a person if I was going to hire them as a junior DBA. Um, no, I don’t see a ton of, of junior DBA job listings out there.
I don’t know. Maybe they exist. Maybe they don’t. I’m also, I’m also not, also not proactively looking for them. So there is my lack of proactivity.
Uh, but yeah, so, you know, uh, like I, it’s, it’s, it would, it would really be more about the person than about, um, than about if they had like any sort of SQL skills. Like, I don’t, I don’t care if they can, if I don’t care if they know what cross supply or filtered indexes or like what a B tree is or any of that stuff. I doesn’t like, do you, do you want to learn?
Cause I can teach you, you know, I can give you, I can give you that like sort of, uh, I don’t know. What’s the, um, the word for if you’re, if you, when you join a union, they call you a journeyman, but I’ll, I’ll say journey person. So if you, are you a good journey person to, to take on this role, to like learn about database?
Because it really is, it really is like that. You know, um, when you, when you get into the DBA world, uh, you, you have, you know, a few, there are a few different ways that you can, that you can hop in. Right.
There are a few different paths you can take. You know, if you want to just do pure development, if you want to do performance tuning, if you want to do sort of the infrastructure type stuff. And it, it takes a little time to figure out really what you’re into. Like I used to try, like, I used to think that like, it was important to be very, very good at both the infrastructure stuff and the performance tuning stuff.
But then like the more I worked with the infrastructure stuff, it was just kind of like, that’s not where I want to live. You know, that’s, um, those are the people who get called late, you know, weekend nights because the server is down. I don’t want that call.
I want the, we want this query to go faster call. Cause I can, I can sit there by myself and work on that. I can make it faster. Um, so like I used to try to, you know, think that like I had to fill, you know, all of the shoes. Uh, but I, I really just was drawn totally to the perf stuff.
And that’s going to happen with junior deep with people who you hire to be a junior DBA too. They’re going to start looking at stuff and they’re going to be like, I need everything. Like maybe I need to be an enterprise DBA and power show everything.
Or like, maybe I want to be really good at like this one thing or this other thing, availability groups or failover or whatever it is. And, you know, it’s going to take time for them to, uh, to learn, to settle on a path. And it’s going to kind of depend on what the job role entails too.
You know, if, if you’re hiring a junior DBA because you want someone to, you know, uh, hit play on a run book for when your AG goes down or something, then that’s, you know, that’s, that’s going to be what the path that they start on. But, you know, who knows if they’re going to stay on that forever. So, and then like, you know, even like once you choose between like whatever you want to do with databases, then you have to like, like dedicate to that and then, you know, get better at, at that.
It’s, and it’s, you know, anyone, anyone who tries to do two or more of those things is going to have a tough, tough time because there is just so much to keep up with. Um, things change so, so quickly, you know, even, even just like on the perf side, like keeping up with all the, all the new stuff and all the new changes and, you know, features and whatnot. It’s tough.
It’s, it’s difficult. Um, you know, you’re always going to have the, the evergreen, like sort of performance, duh stuff, right? Like you’re always going to, you’re always going to have to, at some point, teach people fundamentals, some point teach people, uh, what they need to grow into like a good full on DBA or whatever they want to call themselves.
But, you know, it’s there. Hiring, hiring juniors is, is hard though. So, I mean, I don’t know if we all kids these days, but I would imagine that it’s hard to find someone who wants to work on the database.
Everyone wants to learn to code, right? Everyone wants to learn whatever language is sexy on Hacker News this week or whatever they, whatever they found. Like everyone wants to learn Rust.
Everyone loves Rust. Go, whatever it is. Python. R. Snickers. I don’t know. It’s crazy.
Like, you know, people, people, people all want to, all want to learn the code. No one wants to learn the database. So I’d imagine it’d be tough to find, uh, a database person. You pretty much just have to like, you have to find a sysadmin and brainwash them.
You have to find a sysadmin and be like, you know, Windows is boring. Windows. SQL.
Okay. Look at this bright, shiny thing. Woo. Yeah. Want to be responsible for this? Yes. It’s expensive. Let’s see.
Someone with a very blue name. Um, gola boom. Go zero. I hope I, I hope I pronounced that right. If I got that wrong, you’ll have to give it to me phonetically in chat. But it says Python with a heart.
And, uh, yeah, you know, if I, if I had to go and learn a programming language, I would, I would probably go. Um, I would probably start with Python because I’m an idiot. And, uh, so far as I can tell, Python is a bit like coding with crayons.
And I think that’s where I would have to begin before I got into anything else. Botsco says, can you post those links in chat? I, you’re going to have to be more specific about which links you’re talking about because I don’t know.
I don’t know which links. You’re talking. I don’t know which links. I’m sorry. You’re going to have to tell me. About the event. Yeah, sure.
Actually, they’re right there. They’re going by. So let me pause the slideshow. So, oops. That didn’t do what I thought it would do. So if you go to that bit.ly link, there we go. All right.
You should be able to, let me, let me click on that and make sure that you get what you’re supposed to out of there. Yes, you do. You go right to event bright. And, uh, just like the wonderful slide says, if you, you buy a ticket over here, you will get access to all like thousand dollars worth of my video training.
For free. So it’s a flash sale. It’s crazy, right?
Crazy. And the, the, the, uh, I should, I should probably be very specific that the, uh, the online, the recorded training does include the material that we’ll be talking about during the, uh, during the performance tuning event.
So you will have a bit of a replay on that if, um, if you want to backtrack or if you have any questions. Um, so there’s, you have that to look forward to. If that’s, if that is the kind of thing that you look forward to, I don’t know if you do.
People have all sorts of strange kinks and fetishes and interests. I feel, I feel like unlike, unlike SQL Server job roles, it is, it is my, it is my job to fulfill as many of them as possible.
Uh, I have a, I’m, I’m ordering a firefighter, uh, outfit for the next, next, uh, live stream. So I’ll be hanging out in some cool hat and big suspenders. So if anyone has a firefighter thing.
No. All right. We’re silent on that. Silent. Oh, you’re not changing. You’re just sitting still. I hit the wrong button.
I think that should be the right button. This is rotating slide things. Interesting. Wait, no, you’re still not doing it.
Maybe that button is it. Who knows? I, I, like, don’t judge my, my SQL Server prowess by my PowerPoint prowess. Uh, SterlyDev says, I always have to remember that suspenders is American for braces.
Yes. Uh, do not try to put suspenders on your teeth. Um. Yeah.
And also don’t wear a belt and braces. You look foolish. In England you would be given, oh, I know.
Oh, I know. I know all about it. Yes. I’ve, I’ve listened to enough, I don’t know, uh, specials and madness and all those other scotch bands to know, to know darn well what my braces, my braces are.
Braces for your trousers and all that. Ha, ha, ha, ha, ha, ha. Uh, maybe out of context, but how well are your, my tattoos, my tattoos perceived as a consultant?
Uh, no, no one’s ever said anything. Uh, I think, I think some people, I think a few people have said that they, they look cool. But, no, no one said anything about it.
Uh, and if they did, I would be perfectly comfortable not working with someone who, who is like, ah, I can’t work with this tattooed fella. I would be like, I understand. I look like I’m on work release.
It doesn’t, it doesn’t, it wouldn’t bother me if someone said, ah, you look scuzzy. Why? Uh, do you have, do you have a lot of tattoos? Are you, are you heavily tattooed in some way?
Um, because I’m gonna, I’m gonna level with you. At some point, at some point in my life, I am going to get, uh, tattoos that are on my, my head area. I’m not gonna go hairline because I’m, I’m pretty sure that I’m gonna not, my, my forehead gets a little bit bigger every year.
So I’m not gonna go hairline. I’ll probably do like something like temple or maybe like corner of eye, but, um, but you know, uh, I, I, I would do that at some point. I just don’t care anymore.
I don’t know what I, I’m not gonna get like a middle finger or something, like something gross, but. We’ll get some dude ads up there. Get some dude ads.
Yeah, no one’s ever said anything. Uh, I think the only, and the only time I’ve ever, I’ve ever judged a client because of, of, of their lifestyle was, uh, I was on the phone with one guy and he was vaping the entire time. Excuse you, Mr. Truck.
He was vaping the entire time and not just like, like I have a vape pen vaping, like a, like a little, like dude ad. It was like this, like a shoe box, a shoe box full of liquid. And he would like take this, like, like this pull that just like went on.
It sounded, it sounded like I, like he was like, like unsticking something or like this huge pull. And then he would like do this, like dual exhale through his nose and mouth and you have this like, like beard and mustache smoke. And then like, it would just like cloud around him and he would disappear for a few seconds.
And then he would come back and be like, I am judging you. I am judging you with what you’re doing with that, that vape box. If it was just like a pen and he was just like, yeah, you know what?
No big deal. But it was just like this, like a dragon getting ready to like fry an army. It’s just like, all right. And like the worst part is that you watch that big cloud of smoke pop and you know, it’s just like, like cherry coconut fruit loop, double mango expression.
You’re like, come on, man. Like extra pineapples. I smell, I smell that on the street all the time.
I smell it. I know that you’re not, you’re not smoking anything that’s like, that smells like smoke. If you were just like smoking a cigarette, I would, I would judge someone less for smoking a cigarette than I would for a giant vape box of like 3X cherry nonsense.
Of course, my retirement plan is to live in France and Paris and in Montmartre and wear a lot of black Hermes and smoke Galois blonde blues until I, until I croak. That’s my retirement plan. That’s all I want to do.
Just wander around. Occasionally eating cheese. That’s my big retirement plan. I’ll never be able to do it, but that’s my plan.
That is what I’m going to do. But yeah, no one’s ever said anything about tattoos. And, you know, like I don’t, I don’t go out of my way to be like, look at my neck tattoo. Look at my hair.
Like I don’t, I’ve got out of my way about it, but it would be hard not to notice. And then what’s funny is like when I first started consulting, I was working for Brent. I think the first, like two or three calls that I was on where I was on camera. You know, like I had just gotten out of like, I don’t know, like 15 years of office jobs.
And so I was very used to just wearing like a button down. And so I would, I would wear, I would, I was wearing a button down for the first few meetings. And then I like, like I caught a glimpse of myself in the button down.
And like it had like, I would have like a small pattern on it. And like, I just had this like weird, like psychedelic effect on the camera. And I just was like, screw it.
And I, I stopped wearing them. If this, I used to have a lot of button down. They’re mostly just donated or something now. But yeah, so I used, I used to like try to, you know, be a little bit covered up, but. Let’s see.
What’s a button? That’s a button down shirt. It’s a shirt that has buttons down the front. You’re, you’re in England. So I don’t know. I guess you might recognize it as a, as a, as a Ben Sherman or a Brutus trim fit, maybe. Button downs.
There you go. Mon Mart is a bit expensive. Yes, it is. And that’s why I want to be there. That is where I want to live. Uber douche. If you don’t score a job because of your tattoos, you’re probably dodging.
Yes, absolutely. Absolutely. If I, if, if, if there is, you know, they don’t, they don’t call them job stoppers for nothing. And so if there’s a, if there’s someone who’s just like, ah, I see him. I don’t like him.
I only had one person ever say that to me in an interview too. And it was funny because he was, he was very specific about it. He was like, you know, the neck tattoos, not a big deal. The hand tattoos.
I think, I think people wouldn’t like them. And I’m like, they’re not, not like offensive. It’s not like I have like, like, like, you know, I wish I had Beavis and Butthead on my hand. Now that I think about it, I’m going to go get these removed. Go get Beavis and Butthead tattoos on my hands.
But, um, like, it’s not like I have anything offensive. But, uh, he was just like, yeah, you know, the hand tattoos, people would really not like those. The neck tattoo is not a big deal. And I was just like, okay, no problem.
Hmm, I understand. I get it. Yeah, so a shirt or a dress shirt. Button down, button down shirt. Uh, button down pants would be a little bit silly. Maybe.
Kind of depends on, kind of depends on how, how many bathroom emergencies you have. Die Bart, die in your fingers. Yes. Do I have enough fingers for that?
E-I-E-B-A-R-T-D. Oh, I ran out of fingers. Yeah. And I can get that somewhere. I would, I would actually happily get that somewhere.
Happily get that somewhere. I have all sorts, I have all sorts of like, I guess the nice thing about, uh, having all this time inside to think is, you start thinking, my knuckles are full.
I got no more room on my knuckles. They’re covered. Uh, the, the nice thing about endorsing is that I have lots of time to think about all the things I’m going to do when I get to go back outside.
And I’m excited because New York is, uh, in, in phase one now. And we will be finding out today if we begin phase two on Monday. Uh, Governor Cuomo and, and Mayor Blah, uh, apparently some disagreement on it.
I’m going to have to check the news when we’re done here. Our mayor said that we’re going for phase two on Monday. And Cuomo said, uh, I’ll tell you on Friday if you are.
So, um, got smacked a little bit on that again, again. Like the, like the crazy thing about the last three months, like, like, like I’m, I’m not a terribly political person.
I, I find politics, uh, quite dull and boring. Um, you know, I spent a lot of my youth going to, uh, punk shows and meeting a lot of very political people.
And the one thing that struck me about all of them was that they were very fundamentally unhappy. They were just always miserable. And so, um, I just, as a kid, I got like this weird, like, like, uh, like, uh, clockwork orange response to anything political.
But like the craziest thing about, um, uh, all of the, the, um, the, the pandemic stuff is just watching like, like the mayor of New York city and the governor of New York, like just clash constantly.
And the governor is just like, no, I, I, I have the bigger hammer. And the man is just like, uh, let’s see. I know a guy that tattooed an execution plan on his forearm, a pretty well-known SQL MVP.
Wow. Uh, that is certainly commitment. I don’t think I’ve ever had an execution plan. Um, well, clearly I live in the part of New York that has festive outdoor music.
Um, but like, I’ve never, I don’t think I’ve ever seen an execution plan that I would want tattooed on me. Anytime an execution plan has struck me in such a way, uh, it has been because I found it deeply, terribly offensive.
Uh, many of them have been parallel merge joins. It’s usually a good sign. Um, but yeah, uh, I am in Brooklyn, New York, David P. That’s about as specific, that’s about as specific as I’ll get.
Jeez. I can’t imagine getting an execution plan tattooed on me. Not even as like a cheat sheet.
Uh, let’s see here. Uh, did you try out the graph database in SQL Server? Do you advise it?
Do you think Microsoft, uh, will it follow this path? I don’t know. Um, you know, Microsoft is just so famous, uh, especially in SQL Server for giving you V1 of a feature and then, you know, just kind of abandoning it.
Like not, not a lot, there’s not a lot of movement on it. Um, you know, um, I think, uh, the spatial data is a pretty good example of that. Uh, there’s a lot of stuff that like even Postgres just wipes the floor with, uh, with SQL Server on like, oh, like the geography stuff.
Like they just have so much better support for it. Um, so like Microsoft just gives you such like V, like, like everything still has that V1 smell. And, uh, it just never really progresses on past that.
So, yeah, I don’t know. I don’t know. So I, no, I haven’t messed with it. I haven’t messed with graph because graph is not my thing. It is not anything that, uh, that particularly calls to me.
Um, I don’t think it’s bad by any stretch. Um, I haven’t seen anyone, uh, really use it to do anything all that cool or interesting yet.
Uh, maybe someone much smarter than me will, um, or someone who, you know, spends time with it. We’ll figure out some things. Um, you know, it’s, it’s something where like, uh, if you start using graph and graph does not catch on and, uh, you run into any unfortunate limitations or, uh, you know, bugs are issues.
You might have a tough time getting Microsoft to take care of stuff because you might be a very, very lonely voice in the wilderness asking for these things. And when something is not, uh, an immediate priority or concern, it’s very difficult internally to get developer cycles, uh, dedicated to fixing or improving things.
If you found like a big security flaw with it or something, that might be a different story. But if you’re just like, you know, I really wish it did this, but it doesn’t do this.
You might just get someone to be like, oh, you know, that will be really hard to implement. Like they’ll BS you all day about, uh, it’ll be really hard. I don’t know if we can do that, which is really just code for, yeah, I don’t know if I can get, I like, like no one wants to put time or effort into this thing.
No one’s using it. You know, um, we look at the, we look at the customer experience improvement data and we don’t see anyone using this feature. So we’re just not going to concentrate on it.
And I feel bad for people who, who, you know, uh, wait and wait for these features, wait and wait for these things to get implemented in SQL Server. And then they come out and they’re like, well, you know, it’s our initial thing.
We’ll, you know, get work on it more later. And like, you just have like a handful of people who use it. And then Microsoft is like, that’s good enough. Let’s leave it there.
Like, you know, there’s so many things that like came out and like not like nothing improved about them. And then, you know, you, you stand the risk of Microsoft saying, well, we’re going to do this different thing and you’ll have to use this different thing.
If you want this other stuff, it’s like, take it, like take, take availability groups, right? You had mirroring, you had mirroring for years, right? Like Microsoft could have just made mirroring better, but no, they went and made availability groups and they deprecated mirroring.
So now everyone using mirroring is like, crap, we got to use availability groups. Like Amazon RDS behind the scenes, some years used mirroring. I’m pretty sure they’re going to have to switch to availability groups at some point. So it’s like, you know, like, like all this stuff that like people get, you know, uh, very invested in and then they get nothing else out of it.
It’s sad. Like, I think, you know, stuff like, uh, you know, big data clusters and, uh, some of the other new stuff that people are just like, push, push, push, push, push on. You know, if, if no one, no one uses it, if no one’s out there seriously using it, you’re just not going to see like the improving, like not going to see like the, the dedication to making something better.
And like, I totally understand why people don’t use things at V1. And I totally understand why people don’t use new versions of SQL Server until a certain number of cumulative updates of, or well, now nowadays cumulative updates have passed.
I get it. Like I totally understand. I totally understand. Unfortunately, V1 smell is not nearly as good as new car smell. You are right about that.
Um, I also like the smell of freshly cut wood. And, uh, I, I, I, I enjoy that smell. Drew has sent me three dogs.
Is that, is that, are you, is that what you would rate this live stream? This is a three dog live stream. I don’t know.
You’re going to have to explain that one. That’s a very cute dog though. Is that, is that a dog meme? I don’t know.
I’d make a, I’d make a CrossFit joke, but no one does CrossFit anymore. Everyone does something else. I don’t know if it has a name, but I’m, I’ve been assured it’s not, it’s no longer CrossFit.
They’re doing, uh, exercises of the day. Group of exercises for today, which is totally different. Wow.
A hundred messages. Ooh, we think only a few of them are mine. I feel like that’s a real, it’s a good benchmark. It’s a good benchmark. How long have I been recording? Is it an hour? Where is, there it is. Wow.
Eh, not quite. Go a little bit longer. Make sure, make sure I have a solid 60 for you. Not like Drew’s sad half mast for Randy. Give you a solid 60% mast.
60 minute mast. 60. I don’t know. Maybe.
Or an operator. What operator would it be? Well, it’s funny because I don’t think it would be a single operator. I think it would be, uh, I think it would have to be, uh, a combination of operators. I think it would have to be, uh, like clustered index scans and a hash join.
I think it would have to be that. I don’t know. I don’t know.
Maybe it would be a hash aggregate. And then squats could be a hash join. Yeah, because I guess if you’re, if you’re squatting, you’re, you got your legs out a little bit further. Right?
Right now. And you go, right? Like my hands aren’t in the right place. Don’t judge me. I have a green screen behind me. So I can’t really, and it’s also tough to get into position without A, having a bar and B, without having gotten to do a squat in almost four months. Uh, so my hands aren’t in the right place.
So don’t, don’t think that I do high bar squats like some Olympic lame-o. Uh, I’m kidding. Olympians aren’t lame-os, but high bar squatting is dumb. Um, so I guess a squat, your legs are further apart.
So that your feet separation kind of looks like, you know, what you would see from a join. And then with a deadlift, your feet, unless you squat sumo like a cheater, your feet are closer.
So that would be more like a hash aggregate. So I think squats are like a hash join. Deadlifts are like a, like a hash aggregate. Um, and I guess, and that’s that. I don’t know.
I don’t know. I think overhead press would be a stream aggregate because you really have to make sure that you are streamed in line. Get that thing up.
Bench press. I don’t know. I have to think about bench press. Don’t want to call bench press a nested loop join.
Even though maybe, maybe bench press could be a lazy spool because you’re laying down while you do it. Sounds right to me.
Bench press is an act of laziness. Laying there. Counting on the bench to do all that work. Pshaw.
Then what else? What else? What else? I don’t know. I don’t know.
I think, uh, I think that all this talk just makes me miss going to the gym even more. Like I didn’t, I didn’t realize until I couldn’t go for, uh, for months on end for a reason that was not injury related.
I’ve had, I’ve definitely had injuries that have kept me out of the gym for a bit, but I’ve never just like been in, in perfectly good health and, and not been able to go to the gym and I didn’t realize, um, how much of a nice, uh, mental break it was from, from work stuff and how much of an, like how much of a, of an outlet it was to like go and just like blow off steam and think about something else and concentrate on something else.
I didn’t like, cause I knew, but I didn’t like, like I knew I like that I felt good for, for having gone and done things, but I did not realize, um, just how, just how much of an effect it had on my life.
And, uh, I have not been able to, to replicate that with any of the, the, the things that I’ve been doing at home. And, uh, I just have no interest in like going for a job. It’s not my jam.
So, you know, it’s, it’s tough to, it’s, it’s, it really, it really is difficult to find a, a replacement for that. Cause I really just don’t think there is one. Like I realized it’s not everyone’s thing.
Not everyone cares about it. You know, other people might have other things they want to go do. They want to go do gymnastics or suspension or TRX or, you know, yoga or whatever it is. But you know, it’s everyone has their thing.
That’s my thing. It was apparently a big thing. And once it was gone, I was just like, huh, huh, looking around uncomfortably, like, what can I do?
What can I do? I don’t know. Anyway, anyway, uh, the flow of questions seems to have slowed down a little bit. So, uh, I’m going to call this one here.
Uh, thank you all for, uh, for joining me today. It was a pleasure. Uh, since, you know, uh, this, this seemed to go pretty well. There was some pretty good, uh, pretty good stuff in here.
I, I’ll, I’ll probably go back to doing this once a week. I don’t know if it’s going to be every Friday, but I’ll, I’ll, I’ll do a, I’ll do one or two of these a week probably as long as I, as long as it fits the schedule, if it fits your macros, uh, I’ll do it.
I’ll do a one or two of these a week. And, um, yeah, if you, if you find yourself, uh, out in the world, uh, watching this video and you, you enjoy it or you enjoy any of the other videos you see on my various channels, uh, you know, throw, throw, throw me a subscribe so that you can find your way back for, uh, for more content, like more SQL Server content.
And, you know, maybe, maybe I’ll do exercise. Maybe I’ll just do film myself doing some jazzercise, some step-ups, right? Getting a nice butt.
But, uh, yeah, uh, I’ll come back. Love to have you. Love, love questions. Love, love seeing eyeballs down at the bottom. So come on back, join me again. And, uh, I don’t know.
Thanks for, thanks for watching and all that. All right. Catch you next time.
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
In this video, I delve into how indexes can significantly enhance query performance by providing SQL Server better join choices. We start with a simple query that joins two tables: `posts` and `users`, where we count the number of posts made by users with a reputation over 100,000. Although the initial execution plan shows a quick scan of the `users` table, leading to only 613 rows, it highlights how SQL Server reads about 2.4 million rows from the `posts` table to retrieve these results. Despite this, the overall query takes around 1.86 seconds, with most of the time spent on reading those additional rows. As we progress through the video, I explain that while creating an index might not drastically improve this particular query’s performance, understanding how indexes work and their impact on execution plans is crucial for tackling more complex scenarios.
Full Transcript
Thank you. Beep.
There we go. We are unmuted. live and unmuted I had to wait to unmute myself because there was this really really terrible honking going on outside it was because as soon as anyone was allowed to do anything ever again in their life everyone started honking again everywhere it’s terrible it’s disgraceful absolutely disgraceful absolutely disgraceful alright here we go some people starting to file in thank you far too kind hanging out with me today this afternoon I hope it’s not too late for anyone in Europe I know you have very strict schedules about when you need to start drinking I appreciate that about you I really do I really do do do do do a little bit longer longer than they have to it’s no fun waste of time waste of time sitting here listening to me blathering banter on hello Kapil how are you always happy when when there’s some chat message that way I know that like there are actual live people out there and not just bots not just bots because if I’m just getting watched by a bunch of bots then I don’t know they’re going to be like I think bots would finally like figure out a way to kill themselves like that’s enough end end they’ll figure out how to quit them and that’ll be it I’ve heard that’s a funny joke getting rid of some stuff getting rid of some stuff so how’s everyone doing today hey how’s it going what’s different today today’s stream is well yesterday was me working through the deck and demos for a future presentation it was it was me working like just trying to figure out what I want to do rehearsing a little bit today is a presentation that I’ve had I’ve had done it in the books for a while that I just really liked it’s about indexes it’s not not quite as I don’t know it’s a little bit more advanced than yesterday’s stuff it’s going to going to dig into some more interesting things with query tuning not just kind of like what indexes are you know not just just that today’s going to be a little bit a little bit more advanced I have to figure out how to follow people on twitch whenever I search for people I can’t find them it’s craziness craziness out there alright let’s see here do do do do do do do yes it will be an adventure it will be an adventure of sorts we’ll see what happens hopefully it’s a an adventure free of failing demos that one yesterday is still bothering me I want to know I want to know when I made that change it messed everything up it’s like huh what happened what happened to you what happened to you you went all cuckoo on me it’s just me and brent on twitch yeah that figures figures trying to be I don’t know boldly go where no dba has gone before I don’t know if this doesn’t work out then I’ll stream me being terrible at video games on twitch which I don’t know maybe that would be more interesting to people I’m not sure I’m not sure I don’t know a lot of other I mean other people who are supposedly good at SQL uh stream things and do things I don’t know I don’t know if they stream on twitch or anywhere else but apparently apparently things happen I don’t know apparently things happen it’s it’s crazy it’s insane people keep wanting to learn things good for you good for you alright we’ll give it one more minute here and then we’ll get started I think there are there are just about enough people for me to say thumbs up let’s go I wish I was I wish I was good at more things like whenever whenever I I talk to people who are uh good at SQL Server they always have like all these other interests that they’re like like very like very much into very good at uh like just like profoundly talented people in many ways and I I feel like a one trick pony a lot of the time because I’m like I know kind of a bit about databases like yeah but what do you do for fun and I’m like I don’t know fun forget what that is I don’t know it’s like this and like uh this and like lifting weights back when back when gyms were allowed I I was pretty good at that too but I don’t know if that’s really a talent that’s it’s just insanity all right it’s 10 past we’ll get going uh we will start talking about one of my favorite subjects in the world that is indexes and the reason why uh I am I am so profoundly attracted to indexes in SQL Server is because um I love being able to uh get performance better without having to change code or more importantly not without having to change the logic of code whenever I have to change the logic of code I get very nervous about getting incorrect results back because you know despite the fact that every query in the world I see has no lock on it already I’m worried about results being wrong so I’m like look we’re gonna try this we’ll see what happens but I don’t know it’s very very tough to write logically equivalent queries sometimes right when people are just like we need to rewrite the query and I’m like okay to what like like what are you gonna do like what’s your big plan for a rewrite it’s like it’s like a query with a few joins what are you are you gonna reorganize the joins you’re like what are you gonna do what’s your solution here for rewriting the query now there’s all sorts of domain knowledge stuff that comes in there too right like like you might find a query looking at someone’s server and be like this query is a piece of crap who wrote this we gotta fix this immediately and they’re like oh that should have gone away we don’t even use that module anymore and they’ll like like spend a few minutes looking through source code and be like delete it and be like gone and like to me that’s like a perfectly tuned query is one that just never executes right it’s just gone it’s never gonna run that is the fastest possible query you can ask for they’re like I hate making like big structural rewrite changes to queries because I’m like I don’t know if I’m gonna get this right and then like there’s it’s always very difficult and confusing when you’re doing that because if you get different results back you’re just like what did I what happened it’s very frustrating so I love indexes because usually adding indexes or you know even not just adding a net new index sometimes just changing the way an existing index is arranged can just have such a profound impact on performance make things a whole lot better and that’s the kind of thing that I love because I’m a consultant and the less time I have to spend actually doing something the more my time is worth which is awesome so if I can make quick index changes or if I can identify indexes it’ll help like a bunch of queries and I’m like sweet I don’t have to I have to do far less work a lot of the times when I come in and start working with people the situation will end up being something like no one has ever really looked at like SQL Server as index DMVs for anything and I can identify like a couple few indexes from there there’s like like they may not be perfect because the missing index requests aren’t perfect but they might be good enough to get like a like a whole bunch of queries to a better place so if I can add in like you know somewhere between like you know five and ten indexes and I can get like an entire workload to be better off then I’m psyched because I don’t have to go in and actually start tuning code and things I’m very happy when I can just like adjust indexes a little bit and have like the workload overall be better right yeah and people love that’s the kind of stuff that end users are like wow like it has like a good effect on people like you know like working with people when you know they like they have no interest in databases they have no interest in SQL Server indexes anything like that they’re just sitting there pressing a button they’re like I just want to know why every time I press this button I waste 30 seconds of my life I want to know like if I have to press this button ten times in a day those 30 seconds start adding up right if I have to press this button a hundred times in a day forget it I’m never going to leave work all I want to do is press this button and not waste 30 seconds of my life and sometimes indexes really can do that there’s like all those like you know like consultant like glamour stories or just like let me tell you about this one time sit down everyone sit down there was this queer there was this report and it ran for 48 hours it would take all weekend I came in I added an index and it finished so fast everyone thought that the process was broken because it finished so fast and you’re like wow cool what was the index and it’s just like like the most boring index in the world but that’s how good they are that’s how much indexes really do help things that’s how like important indexes are to a workload when I talk about indexes and databases you know you do have to spend some time getting like the right amount in there because indexes to databases are a lot like salt to food right you want to make sure that you have enough salt in there that you can taste it but not so much that you end up like pre-hypertensive right because it’s not a good look either right just getting getting sweaty and out of breath constantly is not not a good look for databases so they are in the same way it’s very easy to tell when you look at a database if there is too much or too little salt in there because it’s the same way when you take a bite of food and it’s just like like this doesn’t taste like anything or if you take a bite of food and you’re like like I I just had a heart attack thinking about it it’s wonderful wonderful Wes says I’m so glad that I don’t know the data model for the databases I manage I get to look at the indexes and not the bad queries that the reporting team writes yeah absolutely like the less you know but the big like if you know nothing and you can still have a big impact that’s awesome because you can spend like the rest of your brain like the rest of your brain space on more important things right it’s like I don’t know people’s birthdays like non-SQL jeopardy facts it’s great it’s great to have so anyway let’s go and we’re gonna so the way this thing is the way this talk is set up we’re gonna start on the easy side and we’re gonna work in and things are gonna get a little bit more challenging as we go along and we’re gonna solve tougher problems as we move along in this right so we’re gonna start off with like some pretty bit like a couple some basic stuff to make sure that everyone kind of understands what where we’re at and then we’ll get on to harder stuff so don’t worry if you feel like the first demo is not really like the most advanced thing you’ve ever seen in the world you’re right it’s not it’s just kind of a warm up just to make sure that we’re all cool here so let’s get going and let’s talk about how indexes can give SQL Server better choices for how we join tables together right so let me actually just go back up here let me make sure that we are starting from fresh because I don’t want to start from not fresh so if I start from not fresh then demos are going to get confusing when I run them so what we have here is a pretty simple query it’s just one join in there and just one part of the where clause we’re going to join a table called posts to a table called users users make posts and based on how good posts users make they get higher reputations if you know anything about Stack Overflow Stack Exchange if you post questions and answers on there you’ll know that it’s really really hard to get a high reputation like you have to really post a lot in order to get a lot of upvotes or you have to have like really good posts to get a lot of upvotes rather so it’s not it’s not an easy task to have a reputation over 100,000 if I stick a comma in there that is the right number that very rarely happens to me I’m very proud of myself for that so what we’re going to do is we’re going to get a count from this join just for how many posts do users with a reputation over 100,000 have and that’s not a whole lot of people but this query is a little weird this query takes a little bit longer than I would want and if we go look at the execution plan we go look at the details we can zoom in a little bit here let’s look at what happened well we started off with a scan of the users table and this didn’t take long at all this was pretty quick right we scanned the users table we get the 613 rows that we care about again not a lot of people have a reputation over 100,000 if we go and highlight over this arrow and I will zoom in actually do I have to kill that this is crazy I don’t remember if I restarted my computer yesterday that’s how much of a goldfish I am and I didn’t know if I still had zoom it running which it doesn’t look like I do so I should be able to just zoom inside of this VM for free so if we look at this SQL Server did a pretty good chunk of reads here we didn’t pass on all the rows but we had to read about 2.4 million rows just to get 613 out of there but this was fast this was fast this was okay at 47 milliseconds even if I created a great index there this wouldn’t fix the overall performance of the query because this query if we go over here and we look at how long it took we can see that it took about 1.86 seconds if I cut 47 milliseconds out of that I’m no hero right this is not where the index kicks in and it’s just like you did it no that’s not where it is where it is is down over here and I love new versions of SQL Server and Management Studio where we start to get this kind of feedback back from execution plans otherwise people just like they get all caught up in costs and like you know just like weird metrics and they’re like oh we gotta fix this we gotta fix this but like the real root problems become much much more obvious when you have these operator times in there these operator times if you’re new to this stuff it’s just these numbers here that come up under the operators in newer versions of SQL Server when you go ahead and get the actual execution plan so all these things now a couple little differences here if you if it’s a query that only has row mode operators in it remember there’s like this batch mode thing that happens with column store and on and sometimes on SQL Server 2019 the times are going to accumulate going from right to left so if we look across here this was 47 milliseconds this was this didn’t take any time this didn’t take any time and then if you look down here that was 1.78 1.78 and then we spent like we didn’t spend another 1.8 seconds here it was the like 1.8 minus the 1.778 down here so like the times accumulate going from right to left so that’s the that’s the way this thing kind of works there are there is some weirdness with it but and it’s not like totally perfect but for the most part that’s the behavior you can count on so this takes 1.8 seconds and we can see looking at this a lot of the time was spent in this clustered index scan on posts right and that we have this here because we don’t have an index on the column in the post table that we’re joining to this I know is rudimentary stuff but let’s think a little bit more about why there’s a hash join here right because that’s because really the root of it is is not exactly the like like that there’s a scan over here the root of it is kind of like why a hash join why SQL Server would you choose to hash this well think about the SQL Server’s two alternatives the other types of joins that we can have is that we could have is a merge join right so if I run this and we look at what happens when we tell SQL Server to give us a merge join oops I got a little excited there but we’re telling SQL Server give me a merge join here remember the other query finished in 1.8 seconds with a merge join we finish in 5.7 seconds right so that’s that’s that’s not an improvement SQL server was right about that merge join a key difference in the execution plans when we add when when she when if SQL Server chooses a merge join is it needs sorted input going into the join I kind of messed up on the zoom there there we go that’s what I wanted so this merge join over here is going to expect sorted input from both sides the users table is already in a useful order for us because it’s on the the ID column that we’re joining from the users table is indexed it’s a primary key it’s a clustered index so we have that data in order we don’t have the owner user ID column in order so SQL Server has to sort it and prior to sorting it SQL Server is like well if I have to sort all these duplicate values the first thing I’m going to do is aggregate them down to the smallest possible list I can this adds a bunch of overhead and we actually end up spilling out to disk a little bit I’m not saying the spills here are like the cause of the performance problem but you can see that SQL server had to do extra work to implement a merge join here the other option would be a loop join and loop joins really make the most sense when you have both sides of the of the of a join indexed on the join call like with like the like the the join columns in the index somewhere kind of depends on what your where clause might be up to but let’s just say that you know your join column should be indexed at some point if we look at what a loop join does it’s not really any prettier than the merge join or the hash join right like this is kind of bad news this is taking this is taking a while too this took nine seconds what’s up Lee how’s it going so this took a while too and if we’re looking at what happened here like this isn’t like this is about what we expected but then you know SQL Server starts picking up a whole bunch of steam on here and then things just don’t go so well so SQL Server in order to do a merge join or a loop join would have to do a lot of extra work a lot more work than it does then it we’d have to do with the hash join right the hash join actually turns out pretty well comparatively but the hash join does require a scan on both sides and you know it’s it’s a lot of work I think because like going back to this a little bit it’s a lot of work for a for a tape for a join that we know is only going to produce 613 rows here so if we have to give SQL Server more choices if we want to give SQL Server easier choices about using different kinds of joins then we need to make sure that the date that the columns that we need to relate from one table to another have indexes on them and like again I know this is pretty rudimentary stuff you know very smart people out there but you know everyone everyone has to start somewhere and so if there’s anyone in there who who maybe is not you know like the absolute of it like like you know hasn’t been tuning queries and indexes for I don’t know a while like it just needs a little sort of basic guidance on this stuff usually you want to have columns indexed and once we add an index and this is again very simple index just because our query is very simple this isn’t the kind of index that I would go and create in real life because it’s just a single column non-clustered index that’s not going to be helpful to a ton of queries but with but for this demo with this index in place if I just have that index right there are known or user ID SQL Server all of a sudden has lots of choices and lots of cheaper choices for coming up with the join that it wants so now not only do we have a much faster query with this thing taking 343 milliseconds rather than you know 1.8 seconds or you know darn what six seconds or 10 seconds with the it with it without the index and the other joint types this ends up much better we still scan the clustered index of the users table but now we’re able to to use a nested loops join and we’re able to go and seek into the post table for just the 613 rows that we care about that come out of the users table remember that they’re like even though the users table is pretty big at around 2.4 million rows there are only 613 rows coming out of this that we care about that makes it very easy for SQL server to say I have 613 of these yes I am going to seek 613 times but boy is it going to be a lot faster than 1.8 seconds are there any questions on the joins part before we move on it’s totally fine if there’s not I’ll give you a couple seconds to uh to say something just because I know there’s a little bit of lag here and I I don’t want to like get started and have like a great question come up to go back because boy is that embarrassing boy would that be embarrassing be sad right sad I would be sad I would be sad if I had to do that all right so indexing uh indexing join columns pretty pretty normal thing to want to do um without the index really hash was the only sensible join strategy merge would have to sort and aggregate and then nested loops would also have to do some pretty ugly stuff with the sorting and aggregating too because there’s really no other way to get those joins to be fast without doing that work and especially for merge where you need that sorted input not having an index there just really makes it suck actually I I should show you the difference when I when I force the merge join with an index on owner user ID this here will be a lot better choice too like it’s not going to be like the fastest thing in the world but if you remember the other query plan notice that we no longer have to sort any data coming out of the post table we have that we have the data in the order that we want it in right so we don’t have to hash that data and we don’t have to to sort that data but we do still choose to aggregate that data just to make the joint a little bit more efficient all right cool so let’s move on to the next bit the next next next thing is one of my absolute favorite demos in the world because it deals with one of my least favorite query plan operators in the world and that is an eager index pool and rather than like try to talk to you about it first I’d much rather just talk through exactly what an eager index pool is and what it does so let’s clear out our old indexes because we don’t we don’t need these anymore and what I want to do is run this query with a top 38 here all right so I’m going to get the top 38 rows from users and I’m going to cross apply to badges to get the everyone’s most recent badge right so I’m getting the top one name from badges correlated on user ID and ordered by date descending so I’m going to run this query with a top 38 and this isn’t going to be too bad it’s not spectacular it’s not spectacular but it is it is not too bad comparatively so just think about just memorize the shape of the plan memorize the shape of the plan a little bit we don’t need to memorize the entire plan we don’t need to make a big fuss out of what exactly happened but notice that we have the users table we have a sort we have a loop join we have a sort down here and we have a clustered index scan down here too all right so just the sort of general shape we scan users we sort it we go into a loop join we can we sort stuff coming out of the badges table to pretty nice pretty simple now let’s look at what happens when we bump that up to a top 39 when we bump this up to a top 39 things are going to slow down pretty considerably and while things are slow let’s let’s let’s chat a little bit let’s see stefano says nice ascii art thank you oh you know what i’m going to put a link to where i make all my ascii arts into chat so that if any of you want to also ascii up your presentations or whatever you can do that let’s see here lee says my nemesis of late you have a very easy job because you can those are problems you can solve real quick uh hi david nice to have you here great to catch you live too beats the alternatives right anyway so this took 22 seconds 22 full seconds all right 21.884 seconds but you know what this is horseshoes this is hand grenades this is close enough to 22 for me i’m not going to split too many hairs here now we’re going to go back to using our old friend operator times and we’re going to remember that reading the query from right to left operator times aggregate from operator to operator so we can see that this part here was quick right this was not slow and we can even see that this clustered index scan on badges was not slow that took about a second what took a long time here what 21.829 seconds was building this eager index spool now eager index pools are interesting for a couple reasons one they uh will they represent sql server calling you a very lazy person they’re a very passive aggressive operator because sql server has chosen to make an index for us while the query ran sql server has chosen to take the entire badges table spool the columns that we care about to tempdb into if what’s effectively a temp table with a clustered index on it but it gets more interesting it gets a little bit more interesting because when we if we get the properties now one of the most important things in the world one thing that i cannot stress enough to you about how important it is always get the properties of these different operators if we get the properties of the clustered index scan even though sql server is telling us that this went parallel we have our little parallelism badge we have a little erasing stripes there even though sql server is telling us that this went parallel all eight million rows are going to end up on a single thread they might like which thread they end up on might change but the fact that all of the table gets read single threaded to make create the index is always true this is eight million rows and this takes 21 seconds so uh really the big the big thing here is that even in a parallel plan this scan before an eager index spool is going to be single threaded and that’s that’s just kind of bad news now i used to think that this was microsoft like really just kind of enforcing a weird limit because like when you create indexes in enterprise edition or developer edition what do you get you can get parallel index builds right good stuff standard edition you don’t get that so i thought this was like microsoft being like uh-uh standard edition people you get nothing nothing like that but it actually turns out um but i would talk to a very very uh smart person at microsoft who told me that uh there was a very very high likelihood of deadlocks if we build indexes in parallel on the inner side uh or within an eager index pool so apparently there’s a good reason for it but you know who am i to judge now we can read from the index pool in parallel if we look at what happens here it is maybe not the prettiest most even spread in the world but it’s not terrible this isn’t the end of the world here so we can read from the index pool in parallel but when we bring data into the index pool that’s going to be single threaded the good news sort of is that there is a weight type that gets associated with this if you have a parallel plan like this and an eager index pool gets built if you again this is why it’s always important to go looking at the properties and the properties of on newer versions of sql server we can see the weight stats that a query generated while it ran well not all of them not all of the good and important ones but we can see a pretty good chunk of them and if we look at uh weight stats that got generated for this query we can see like some pretty pretty normal ones that we might usually see on a sql server sql server memory allocation cx packet but then we have this sort of oddball one down here this oddball one down here is called exec sync now there are other things in sql server that can cause exec sync weights to happen but normal like normally when i go and look at a server and i you know use uh it doesn’t matter if it’s paul randall script if it’s uh sp blitz first whatever weight stat script you like if i see exec sync weights on a server that are you know like fairly high and especially if they have an like a long average duration like if you look at this one this one this this this this this weight actually generated 65 seconds of wait time because remember it’s generating in parallel there are multiple threads waiting on that eager index pool to get built there are this is a dot for a query so there are four quid four threads waiting on that so we have this exec sync weight coming up if i see like this is a pretty long weight on average if i had this query running a lot it would always be waiting 20 seconds on the the index pool to get built because remember they get thrown away as soon as the query is done sql server doesn’t keep them around for anything but if we have this exec sync weight and it’s we see that like it has a pretty long average duration then i might be paying special attention looking uh for looking at poorly performing queries for eager index pools now if this plan was sick was serial if this was a single threaded plan we wouldn’t have a weight that was helpful to us but in parallel plans that thing shows up and is a pretty good uh pretty good red flag about what might be going on now if we want to fix eager index pools we can’t count on help from sql server there’s no missing index request here there’s no sql server like sql server is not sitting there saying oh green text green text we we need help danger will robinson uh there’s nothing there and it’s not like this this is just sms ssms being broken there’s no missing index in the xml either i’m not going to spend a lot of time scrolling through that but you get the point sql server isn’t telling us that it needs an index sql server is just hauling off and building this index and it’ll do it every time the query runs it’ll toss out the result the the the the index data later it’s up to us to look at what’s going on and kind of figure out a good index now the easiest way to do it if you don’t want to spend any time on it if you look at the pro if you look at the eager index pool right and i’ll zoom in here there are going to be a couple different parts of the eager index pool well one part is optional one part is always going to be there the part that’s always going to be there is going to be a seek predicate and you can think of the seek predicate as sort of like what the key of the index would be uh would the sort indicate help i’ll cover that in a second so the seek predicate here is going to be what sql server built the key of the index on now uh sql server of course when it creates an eager index pool the object up in tempdb is pretty much like a temp table with a clustered index on it we already have a clustered index so we would have to build a nonclustered index to satisfy this query but we don’t right now on the badges table we don’t have an index on this user id column and the user id column is what sql server wants the key of the index on we also have two other columns involved here we have the name column and we have the date column because remember what we’re doing is selecting the name of the badge for a user ordered by date descending so we’re getting their most recent badge so we have three columns that we would need in an index in order to make this thing go away so if you wanted to do the like the easiest most basic thing in the world it would be to look at this look at this tooltip create an index with a key column on user id and then create uh or then add name and date as uh as included columns that would be very easy but remember something remember what the query looks like we’re ordering by date descending so what we might want to do and this is only something that you can do if you if you look at the query and you look at the execution plan what we might want to do is also have date as a key column so that we can have the date column in order for free when this runs and i’ll show you what i mean we don’t need to have the date column first in the index we just need we need to have user id first in the index because that’s going to be what we seek to and then what we’re going to have next is the date column this doesn’t even have to be descending what i’m going to show you but then we’ll have name included here so what i’m going to do is create this index and the nice thing about creating this index is that it doesn’t take 21 seconds to create does it it doesn’t take 21.8 something seconds no creating this index nice fast in parallel takes 1.7 seconds what the hell was sql server doing for another 20 seconds when it created it on its own i don’t know apparently there’s a whole bunch of stuff about spools that just like didn’t get the message about certain optimizations that the rest of sql server did i’m not going to get into it here because you know we only have so much time but this is a like they’re just that like they kind of fell behind a little bit like when like we have like the no child left behind thing in america we should have the no operator left behind thing because some of these operators were left very far behind so now that we have this index on user id date and include name if we run this query asking for the top 39 we’re not going to have that index pool anymore sql server already has data or has the data that it uh it wants in the right order right so when we we seek into the badges table this takes nothing and when we look at the top right again we don’t need to sort we don’t need this isn’t a top end sort it’s just a regular sort the only sort that’s happening is actually on the user’s side kind of kind of shocking kind of shocking i don’t know why it’s shocking but it’s kind of shocking it’s a little shocking we have to up here we have to order by reputation descending because that’s part of that’s what we’re doing there right so it’s no no no funny tricks that’s that’s ordering by reputation but now this finishes a lot faster and now this is actually something that i was i was trying to trying very hard to write a demo to uh to do yesterday but um now i have one magically today sql server now we have a missing index request right when this query took 22 seconds and we were building an index in like while the query ran no missing index request now that we have this query down to like under 200 milliseconds sql server is like oh i got it i got the solution i know how to fix it i can do it i can do it it asks for an index on on the reputation call on the users table it says give me an index on reputation and include display name what is that gonna fix like it like cool it’ll take off i don’t know what 100 milliseconds 85 milliseconds we already did all the work screw you sql server why why are you chiming in now with this nonsense so whenever you see uh eager index pools and execution plans they are a giant red flag that we have that we just have some yet there is some very obvious index for this query that does not exist uh on the table currently and that adding and though sort of and remember always use as much feedback as you can before you go and make these changes like for for this query was very very obvious that we needed an index because it was taking 22 seconds and most of that 22 seconds was spent building the eager index pool if you see eager index pools and plans and you’re able to get the actual operator times but the eager index pools aren’t the thing that’s taking a long time to like build they’re not they’re not like really the reason why the execution plan is slow then it might not be worth it to fix them but in general when you see your index pools and plans that is something that you should focus on at some point in your investigation because i guarantee you that there’s an index in there that could help especially if you’re dealing with a long-running query and especially if the table that the eager index pool is being built from is a rather large table i think that’s probably the best rule of thumb think about the size of the table that uh the that’s being fed into the eager index pool and if that’s a big table then you then that’s probably something that you’re going to want to fix because the bigger a table that feeds into an eager index pool is the longer building that eager index pool is going to take so uh it doesn’t look like there’s any questions so i’m going to move on and we’re going to talk about a slightly different kind of spool of course if you have any questions just chime in and chat i’ll i’ll backtrack and answer them but uh for now i’m going to move on and we’re going to talk about table spools table spools are sort of like index spools except that they don’t have any index on them they’re just sort of like where where uh an index pool is sort of like a temp temp table with an index on it table spools are like a temp table with no index on it um they get used for different reasons but uh you know again implementation details are kind of boring to get into but table spools you know they they get they happen for different reasons and they sort of have a different uh sort sort of have a different usage pattern now i’m going to well i’m going to create these two indexes and while they create i’m going to talk a little bit about the query and i’m going to talk a little bit talk a little bit about why uh the last query for eager index pools and this query uh for table spools have some things in common now uh one of my absolute heroes in sql server is a guy named adam mechanic and i used to always see him writing cross supply queries and i said man those cross supply quits are awesome i get to write cross supply queries and whenever when i started doing that i started running into very adam mechanic problems i started understanding the things that he would talk about more and more uh and like like whenever i would see him talk about it’s like oh that makes that makes total sense now thank you adam uh but this is a this is a cool one uh so the reason that cross supply tends to work well for table for uh demos that have spools in them is because cross supply is just about always optimized as a nested loops join whenever you have a nested loops join you have a loop and whenever you have a loop you have something that is going to happen repetitively that is what a loop is you have the part of the query that’s like you have what’s called the outer side of the loop right which is up here and then that is you know kind of like the thing that happens once and feeds into the loop then you have the inner side of the loop and the inner side of the loop is a thing that needs to happen over and over again spools as spools usually happen because sql server wants to do something less repetitively if we think about the last query that we ran that uh where the the tipping point between 38 and 39 rows in the top at 39 rows sql server said i don’t feel like scanning the badges table a 39th time i’m going to build an index once and i’m going to use that index 39 times for this query you’re going to see something kind of similar you’re going to see sql server use it like we’re going to have a nested loops join because of the cross apply and sql server is going to try to cut down on repetitive work by using a spool to only get data only get new data sometimes and i’ll explain to you exactly what that means uh when the when we look at the execution plan ronald says do you ever use live execution plans uh occasionally occasionally i’ll use live execution plans only if um i am completely dissatisfied with how long i’m i’ve been waiting for a query i might kill it and run use a live execution plan to see where things are getting gummed up but a lot of the times if you turn on actual execution plans and you use like sp blitz who or sp who is active they’ll give you a snapshot of the live execution plan so you can kind of see where things are at anyway live execution plans are totally fun to watch just sort of like you know as trivia but they’re not something that i rely on for query tuning regularly so what we’re going to do here is uh we’re going to stick some data into uh this this temp table and this temp table doesn’t have any indexes on it’s just a single column and what we’re going to do is we’re going to stick in user ids for anyone who has this badge called popular question the thing about this badge is that you can get this badge many times and we’ll look at that in a second but now let’s run a query that uh takes data from the temp table and we do some work to figure out like someone’s like the most popular uh question by score that someone asked who had a popular question right so it’s a pretty i don’t know kind of a useful query right so we we we we take people who have this popular question badge and then we do some work to figure out what their most popular questions are right so it’s a pretty good thing to do we say okay you have a lot of this badge what do you got what’s in there sport like what what do you got going on what’s what’s so great about you this will run for about 11 seconds all right so again 10.8 it’s close close enough for me it’s close close enough to 11 for me i’m not gonna again horseshoes hand grenades and eight i’m gonna round up a little bit and you know again backtracking reading execution plans from right to left or at least at least looking at the the operator times from right to left we can see that we build up a lot here right and we spend a lot of time in here remember this is 1.126 seconds and this is 7.429 seconds so like the majority of the query time is spent here now we talked about eager index spools last time lazy table spools are a tad different and they’re a tad different because where eager index spools or rather where eager spools in general are different from lazy spools is eager index spools will read the entire result set into the spool like at the get-go lazy spools are different because they only go and get data when something changes and i’ll show you how you can look at that whenever you look at the properties and again always be looking at properties a b c always be looking at properties if you look at the properties of a table spool which is especially helpful and actual again especially helpful in actual execution plans uh we’ll have these two things here we’ll have rebinds and rewinds the thread spread on them isn’t really the most important thing what’s important is understanding what they mean so if we have a rebind that means that we reused data inside of this spool we went and got data from all from all the way over here we populated the spool with it and then we reuse data in that spool when we have a rewind that means oh i’m sorry i have that backwards and we have a rewind when we have a rewind that means that we reused data inside of the spool you can think of that like a cache hit when we have a rebind that means that we went and got new data and put it in the spool you can think of that sort of like a cache miss lee says i noticed the estimates are out of whack that’s connected to the table spool too right uh you know i haven’t really looked at that so much but yeah generally you know um the since the table spool is an operator that executes multiple times it’s i think when you get into situations like that it becomes more difficult to sort of forecast exactly how many rows are going to happen from one to the other uh so you know sql server might make like a best effort estimate based on the uh the distribution of values that it comes up with when it looks at the um the uh the histogram for the temp table so yeah generally it’s going to be connected to the spool but uh you know it’s a very i would say it’s a very it’s a very difficult thing to figure out uh for the optimizer and it’s like i wouldn’t focus on necessarily the the um the estimates being way off for it i would more focus on why the spool is happening in the first place so we can see that this spool is doing a fair amount of work so every time we need to rebind we had to rebind 109 000 times we need to we needed to take the data that was in the spool truncate it and then rerun all of these operators to fill it back up this happens because there are a bunch of duplicate values in the temp table sql server if like let’s just say that this had the numbers one through ten and the numbers one through ten each happened ten times so we had ten ones ten twos right on down to ten tens sql server takes the number like let’s just say that the first one first id that comes out of here is a number one so sql server says i’m going to scan you i have the numbers one through ten and i have them ten times i’m going to put them in order so i have my ones and i have my ten ones in a row my ten twos in a row and so on then we go into this nested loops join sql server says i have a one table spool what’s in you the table spool says i’m empty the sql server says go get all the values for id one the table spool executes goes and does all this stuff and it brings back all the data for id one and then for the next nine times that the the nested loops join takes the number one like from from the from the sort it’ll just reuse data inside of the spool so it’ll hit this spool ten times in total then the number two will come around come along nested loops join will say i have a two index pool or table spool what do you have and the table spool will say i have all the values for one and sql server will say nope go back and get me all the twos and then sql server will come over here get all the twos come back repopulate the spool with all the all this all the twos and then the the data in the spool for the tools will all get reused nine more times so that’s why spool that’s why spools like this exist the thing is there is almost no reason for us to have duplicates coming in here because the purpose of the query is to just get a sum of scores for people based on their high scores right it’s we don’t need to look at someone to look at a single user’s high scores over and over again now if we look at what’s actually in the temp table so we’re going to look at like what got in there we’re going to look at user ids and how many exist and then we’re going to look at a count of distinct records overall we’ll see that you know for the number of records that are in there or the number of distinct like the number of user ids that we have in there versus the number of distinct records are in there it’s like a lot of these a lot of the reason that we have 368 000 rows because we have hundreds of entries for other user ids right and that’s that’s not something like we don’t need to know user i the sum for user id 4653 623 times you just don’t need that this is not going to do anything for us so what we can do is rather than put all that like additional data in there is we can stick a primary key on our temp table and we can only distinct only select distinct user ids into it and we’ll end up with far fewer rows in the table overall right so i’ve dropped that old temp table i put new data in it and now when we run this query it’s maybe not going to be the fastest thing in the world like there’s probably still some index tuning that we could do but i think three seconds is a lot better than 11 seconds and that’s that’s 3.3 verse 10.8 and if we go and look on the drag that over there bring that plan back if you go look there is no eager there is no lazy table spool on the inner side of the nested loops seagull server just goes over here scans the clustered index and we do a very simple loop and we just get the rows that we need so well the spool does help us with not doing repetitive work between you know the theoretical here and here we do have to touch that data inside of the spool over and over and over again which is kind of a bummer so with uh just like you know not even sticking a different index on the post table just sticking uh the right index on the temp table we can have a much better query we don’t have to use that spool we don’t have all those duplicate duplicate values in there we can solve a lot of problems uh if there are any questions on this go ahead and stick them into chat uh i’m gonna you know i’m gonna i’m gonna move on but at the same time if you have questions i don’t mind i don’t mind backtrack backtracking a little bit it’s always always a pleasure to answer questions so now let’s talk a little bit about how indexes can help solve blocking problems all right so if we again clear out clear out our indexes here and what i’m going to do is run this update here now i’m going to use begin train to exacerbate things i know that begin train isn’t like i know that like begin train and waiting a while isn’t the most like uh um you know realistic thing that you might see in production maybe it is if it is i’d love to come help you out there’s a contact from my on my website we could chat about that i’d love to help you with that but let’s just say that you know this this was a long-running update for other reasons so we’re going to run this update with the begin train and we’re going to come over here and we’re going to try to run two queries right we’re already using the right database if i run this query this query finishes instantly all right good stuff there so we have this data back this this query was not blocked if we run this query though this query will start taking a suspiciously long time this query will not finish instantly this thing is still down here spinning away if we go and look at again if we go look at sp who is active we can get some we can get some interesting information about what locks got taken here again well first off we can see that this query has been blocked for about nine seconds and it’s still going it’s like because that begin train is open this thing is just going to sit around waiting all day long and i know this is exactly why people use no lock who the hell has time for this but if we go and examine things a little bit come over here the query plans really aren’t all that important here but what is sort of important are the locks that get taken so right now sql server has taken an intent exclusive lock on the object which if you were here yesterday you know that this does not mean that the object is locked this just means that uh we can oh hello party time this just means that sql server has taken an intent exclusive lock at the object level so that it can lock uh things at a more granular level david says is there anywhere we can grab the sql that you use in your streams um sometimes uh this stuff not really uh uh it’s i mean if you have the stack overflow 2013 database it might be interesting but a lot of the times people don’t have that and don’t feel like getting it uh if you really want it i can publish it somewhere but uh you know a lot of people just don’t like i i have bitly links to this stuff and i look at the download from them like before and after i give presentations and they hardly go anywhere you too so i mean if you really want them i can i can give you a link to them but uh yeah so we see here is um that sql server did take some page locks and those are exclusive locks right so that did happen and we can see that there are nine of them so we just got very unlucky that the the id that we wanted 1317729 was just happened to be on a page that was blocked by that update if we go and run sp who is active again we can see that i mean i don’t want to figure out what that number is but it’s a it’s a long number so let’s kill this off and let’s think a little bit about what’s happening all right we should probably we should probably roll this back before we go and do anything else right so what we have is an uh is an update against the uh the badges table now if i run this and i just get the query plan for it we can see pretty simply that this thing has scanned the entire badges table uh and then we have to update the badges table based on that so uh what we’ll see is that this thing we have to scan the badges table and now something kind of quirky now this isn’t i want i want you to understand that this is not like an always and forever like pinky swear sort of rule in sql server but sort of generally if you have a modification query and you start with a scan you’re going to have either page you’re going to start with page locks if you have a modification query and you start with a seek you are most likely going to start taking row or key locks right this kind of the same thing but some people call them row locks some people call them key locks there’s not a lot of not a lot of other terminology out there for pages that’s sort of a general rule it’s not a perfect rule but it’s something that you can keep in mind if you see a scan uh where the data is coming from in a modification query before you come over to the right you’re most likely going to start taking page locks either one of them might escalate to an object lock right you might go from like the row slash key lock to an object or a page lock to an object you don’t go from row to page keep in mind that doesn’t happen but if you uh if you go from uh you can go from like the row or key locks up to object or the page locks up to object so in this case we didn’t escalate locks the entire object wasn’t locked that row just happened to be on a page that got locked because sql server said i don’t really know where this data is i don’t i don’t really have a good way to find this data even though even though i’m searching by id like sql server is like i don’t know where to find these dates these dates could be anywhere but with a good index on the date column what we’ll do is create that so now sql server has a very good way to find dates and since we’re updating user id we’re not updating the date column we can begin tran over here and when we run these two queries now they both finish instantly the difference of course is the type of locks that sql server took when this thing was rolling along now if we go look at the locks column things will be a little bit different we’ll see intent again we’ll see the intent exclusive locks on pages and we’ll see the intent exclusive lock on uh the object but the only thing that actually gets exclusive locks it only gets this x are the keys of the primary key right so only key columns there were 1447 of them which is more than you know the page locks that we got but that’s okay because it it finished really quickly and if if we weren’t you know being knuckleheads and doing a begin tran then we wouldn’t we wouldn’t have a problem and if we go look at the execution plan now we’ll see that we have done a seek into that index to find the right dates and because again general rule of thumb like there’s a lot of sort of like nice sort of cloudy stuff around this because we started with the seek we most likely started taking row slash key locks rather than taking page locks so that’s a nice thing to do there so always whenever you’re trying to make whenever you’re trying to solve locking problems one thing that i always want people to be looking at is uh their modification queries if those modification queries have a join or a where clause it might be a very is a very very good chance that we are just missing an index to help those queries find data david says i always use a stack overflow database when following run streams yeah so just to make sure that you understand this is stack overflow 2013 this is not the full-size stack overflow database so these might not translate totally fully over to you but uh if you have 2013 then they should work pretty well yeah so let’s see mr shah says so is proper indexing the correct answer to what i should use instead of no lock uh it really i mean it depends a bit on the situation um uh proper indexing is generally a very good place to start uh for these things uh or another thing to consider is that you might have you might just have modification queries that uh are just doing too much at once and i’ll i’m gonna what i mean by that is if you have a modification query that even if it has a perfect index so it can find the data it needs if it’s updating like tens of thousands or 20s of thousands or millions of rows that thing is always going to try to escalate and there’s always going to be blocking kind of like the more stuff you have to change in one go the longer that query is going to take a friend of mine he’s canadian don’t hold it don’t hold it against him too much he’s he’s nice uh let me get the url uh but he wrote a wonderful blog post about scripting batches to um to uh to reduce the amount of locking be nice here to transaction logs not have like that specter of lock escalation uh popping at you so this is a very good blog post about that i would say generally when i’m trying to solve blocking problems one of the first things i’m going to do is a i’m going to figure out if the good if the database is a good fit for an optimistic isolation level uh like read committed snapshot isolation or if i just need to target specific queries and maybe snapshot isolation second might be trying to figure out if my modification queries uh are could use an index to help them find data third might be okay how much like how many rows are we typically modifying should we rewrite this process to batch the modification query so that we’re not we’re not taking uh like as excessive locks for as long uh and then after that i would be totally cool with you using no lock hints because you have exhausted all your sort of sane and rational options so there is that uh chris says i’d also love the data love to have the database well if uh if you want the database uh you can go uh let’s see i know i have that somewhere give me a minute if you want the database why are you asking me to log in oh you knucklehead uh i forget how i log in here there we go all right give me a second let me grab uh uh i i have to warn you it’s not going to be a fast download because it’s it’s it is a decent sized database so let me copy this link and let me come back over to chat so uh if you want the database you can go there and i think i have i do oh that’s an old version though yeah i have an older version i have a link to an older version of this in bitly let me see if there’s a newer one because then i might be able to just throw you the scripts real easy oh you know what uh i can’t find it quickly so i’m going to move on but uh yeah if you want to grab the database that’s right there uh if you want the script so i will i’ll put it out on twitter or something when i’m done or i don’t know if i can add a link to like the the data like the the description of this thing and i’ll do it there but anyway let’s move on from this and let’s talk about uh something else that indexes can help with now this is where problems start getting a little bit more difficult this is where problems admittedly start getting into like the oh crap the server’s broken type of problems like these are like not just like oh i have a locking problem oh the query’s slow oh we could fix this oh this is no this out of the other thing this is where things this is where things really start to hit the fan this is when like you start getting alerts about like like red alerts from your monitoring tool users start calling you there’s all sorts of like like like like you’re like your big important line of business application is down people like i can’t connect like nothing will run these are the kind of problems you can sometimes run into so um what i’m going to do let’s see here oh there’s a question my environment application takes rollox and another update query needs that row so there’s always blocking is that solvable by indexes uh if you if you need the row then no so if you have an update query that’s locking let’s say id one and another query comes along and needs id one then no that’s not solvable by indexes that’s that’s only i would that’s only correctly solvable by using an optimistic isolation level either read committed snapshot isolation or a snapshot isolation those are two kind of big big big areas uh they’re big topics to talk about so i couldn’t really i couldn’t do them i couldn’t do them right by talking about them here uh because there would it’s a again it’s a very very big topic but uh it would be that would be what you would want to do it’s better than no lock they’re better than no lock because what you get back is the previously committed versions of values in that row so those values were correct at some point you don’t subject your application to the uh like the like i if it’s not a word it’s a word now to the potentiality of dirty data so you skip over like the phantom reads stuff you might see like if a transaction is currently in flight that’s kind of the better way to go there if you if you start falling into using read uncommitted or no lock which are effectively do the same thing no lock is a terrible word for the hint no lock no lock really should be no respect because what it does it doesn’t no lock doesn’t mean that you don’t take locks no lock means that you don’t respect locks taken by other queries so whenever you have a right query that takes out locks and says i need to modify this data please don’t read it because i don’t know what it’s i don’t know what it’s going to look like the re-cray is just like whatever pal i want it i’m going to take it so uh yeah it is i think drop indexes is the very fast or procedure it’s it sets a record but yeah so if you want to if you need to if you have a problem where you know you truly have modification queries that are touching the row they need but another query needs that row your only really good valid option is going to be an optimistic isolation level all right so let’s look at uh how indexes can affect memory we don’t need these windows open anymore so i’ll clean those up a little bit nothing nothing in there would uh we let’s see uh john wouldn’t it be possible that problem roll lock queries are tunable if they have poor plans uh no because the problem that he’s he’s having or that sorry that they are having is that uh the row that another query needs is locked specifically right so if you have a update that’s taking row locks and another query needs to read those rows it doesn’t matter if your other query has a good plan or a bad plan it matters that those the rows that you actually need are locked and if you need rows that are locked your really only valid uh uh option is to you know uh use an optimistic isolation level sure you could tune the if you have a very very bad plan for those modification queries and they’re taking longer than they should you could tune those queries to be faster but that sort of that that that infers that the that the queries are a bad that they’re taking longer than they should and that this that the the modification queries that are going in and taking those locks aren’t taking them and holding on to them for a reason there’s a lot of processes that people have written into databases that that rely on locks like that to set up a proper queuing of things and it’s not always possible to say oh if we just tune this query to be faster or you know release this lock earlier we can you know we can we can resolve blocking problems because a lot of the time those when people are write things that specifically take row locks and they need to modify this row but something else needs to work with it that’s always like every time almost every time i’ve seen that it’s been some like some weird queue that someone has written into the database yes no i understand if it’s if it’s locking them for too long then yes you could tune a query to do it but that doesn’t sound like it’s a situation here if if if they had asked a different question if they had asked about tuning the the queries but it sounds if it sounds very much like this is a pretty simple situation where uh that’s not it’s like like the query is not going to get any faster we’re taking that lock and holding it for other reasons so i agree there are there might be a time when uh if the lock was being held on for too long because the query was long running that’s one thing but it doesn’t sound like that’s it yeah exactly some some type of queuing all right so let’s talk a little bit about memory we’ve got we’ve got indexes cleared out here and i’ve got this store procedure now the gut of guts of this store this this store procedure does not take any parameters and i don’t want it to take any parameters because that would ruin the fun people get all caught up talking about parameters and parameters have nothing to do with this now we’re going to do a couple things let me crack open oh yeah yeah every time i do this sequels are windows is like i don’t know where rml utilities are i can’t find rml utilities but meanwhile if i go right here i can find the rml command prompt and everything is fine it’s like i’m being messed with i’m being messed with constantly if i say rml like oh i can’t find it but it’s right there like stop being stupid windows like like every time i do this i’m like why why not linux windows is such a dummy such a dummy i can’t take it can’t take it some days but i’ve got this uh store procedure and the guts of the store procedure run this kind of big goofy looking query and what i want to do is stick this into a new window this is my store procedure uh sp pressure detector and i believe everything’s spelled right and it should run good stuff but what this does is uh two very specific things it is not meant to compete with sp who is active or any of the blitz scripts it is sort of its own thing and it and you can choose to run one of two queries or both all right so what you can choose to do is uh what you can choose to do is either look at memory pressure or like things that might cause memory pressure or things that might cause cpu pressure we’ll do both here but uh right first we’re going to look at memory so what this what this gives you back when you look at memory is if we had any queries running that were asking for memory they would show up in this top space if we had any queries that were or rather sorry if we hadn’t if we had any queries or asking for memory we would see some of the numbers down here start to change a little bit we can see that looking at some of these numbers going across sql server says right now i am willing to give out just about 38 gigs of the 50 gigs max server memory i have this is a vm with 64 gigs of memory uh i’m willing to give out just about 38 gigs of memory right now two queries that might need it for memory grants okay fair enough sql server fair enough let’s see just to keep up with chat uh it’s already rcsi so if it’s already rcsi in the and you have queries taking roll locks and they’re kind of getting held on to there um i would also suspect to see i would also suspect like or rather i would also expect to see other locking hands like maybe hold lock or something in there uh so that you know things are kind of held on to but not sure and i don’t know uh yeah fun stuff but we can see right now but we haven’t given any out right so sql server is like i would give out about 38 gigs i haven’t given any out now nothing’s going on that’s totally cool if i go and run this query and all i need is the guts of the store procedure i don’t need to execute the entire store procedure but if i go and run that and i look at what sql server does i don’t need this to keep running we’ll let that let that die gracefully since i just executed it we can see that this query has asked for about 9.4 gigs of memory that’s 9 474 megs of memory which is just about 9.5 gigs right that’s a lot all right that’s a lot now ideally or rather um what we see down here is where sql server has taken as total memory or rather available memory there we go available memory is now down to 28 because we have granted out 9.4 gigs right so the total memory now is still the total memory is still the same total memory is like we’ll still get about throughout 38 gigs but we we have much less of it available because we gave some out now i don’t know if any of you are good at math i’m not good at math but i’m going to tell you what happens if we try to run a bunch of copies of this query all at once so i’m going to use this i’m going to use the the o stress uh utility or rather the o stress uh program from rml utilities if you want rml utilities you can go over here and get them it is a pretty neat spiffy fun tool i like it um i also like sql query stress but uh sql query stress kind of crashes a lot sometimes especially if you ask it to use a lot of threads so just kind of for safety i uh i like to use i like to use uh o stress uh narav says let me guess bad things happen yes indeedy duty so what i’m going to do is i’m going to run four copies of this store procedure all at once we’ll get that going over here yeah no whammies excellent come over here run this and while that happens i’m going to kill this off because i don’t want my laptop to get too angry with me so we we have the we have the information we need we don’t need any more information right now so what we have is three copies of this query that run and run pretty well or rather they they run they sql server gives them the memory that they need or that they ask for whether they need it or not is complete completely besides the point but uh sql server is just like yeah for these three go ahead you can take it that’s all you you can have it i don’t mind but you but you session id 57 you get nothing the grant time down here is null the granted memory is no right it is still asked for nine point well it’s about 9.5 gigs of memory but it hasn’t gotten it right now this query is off waiting in a queue waiting in a queue to get memory so that it can start running while it waits in this queue you will generate this very very silly weight up here remember that all the queries that have gotten their memory grant and are off doing things have cx packet weights but our poor query down here that has not gotten memory that is waiting for memory is getting these resource semaphore weights notice it doesn’t have any workers it hasn’t doing anything we still have we have a query plan for it that’s not really the point but we what we don’t have is enough memory for this query to run which is kind of funny because if we look at how much memory this thing has asked for that’s exactly how much memory we have left to give all right so we we have nine point four nine nine four seven four point seven five lots of zeros left but and we have we have this query asking for but it’s not it’s not getting it it’s not getting it because our query would need nine point nine nine point five plus half of nine point five in order to run right so you need to have not only when a query wants to run this asking for a memory grant the available memory not only has to cover that memory grant but also another half so that if anything else comes along it needs a memory grant so you’ll sort of be like yes you can have that memory well this thing waits because it is terrible so yeah this is this is not a good situation and you can run into this when you have a like either says something like this where you have a few queries that ask for very big memory grants or you have lots of queries that ask for kind of smaller memory grants and they all sort of add and stack up now this very simply this is three queries that have asked for about 28 and a half gigs of memory you could totally write a query that wanted like one or two gigs of memory and run like 14 or 15 of them and have the same hell break loose it doesn’t matter all those memory grants have to come from the same place query memory grants uh come from typically there are of course a couple few outliers nothing nothing like nothing that i think is so constant that you need to be concerned about it but query memory grants typically come from two places or two specific operators in a query plan they come from sorts and they come from hashes this query has a little bit of both in them all right we have a hash join up here and we have a sort right about here the thing is hashes when you see a hash they typically build a a hash table based on whatever input goes in the hash table over here isn’t all that gigantic right it’s only for a couple million rows and if we uh i forget if this is going to be completely accurate if you look at the memory fractions here uh the closer you get to the number one the higher the the higher the fraction of memory you get is so this this hash join actually got a very very small amount of memory rather got a very very small amount of the 9.4 just about 9.5 gig grant that sql server gave to this query the majority of the memory will and in most cases will always go to sorts sorts can sorts can really just ask for a size of data as far as memory goes it’s pretty crazy what sorts can ask for if you look at the memory fractions for this sort this memory fraction is very very close to one so you can see that the sort got almost all of the memory now operators and query plans can reuse memory like if they finish they can pass memory along that’s why memory fractions are often kind of weird and don’t always line up perfectly it’s because memory might get like you know reused and shuffled along but it’s a little bit more complicated than i want to cover here because this is after all about indexes this is not about memory of course so stuff to keep in mind now let’s go look at what or rather before i close out let’s look at what was sorting we have an order by on user id ascending and score descending and we have an output list that is just about every other column in the comments table most of these columns are harmless and by harmless i mean they are numbers and they are dates dates and numbers don’t really have a big memory footprint now you might have a very very long data set right and we have a very very long data set sure you might have a bigger memory grant because you have more things to sort but what really really starts to chew into memory grants and like get sql server to really inflate memory grants are going to be string columns this column is called text it’s not a text data type or an n text data type i think i want to say it’s an nvarkar 700 so it’s not even gigantic but the way that’s the optimizer guesses memory grants or how much memory it will need when we have to know now i’m going to show i’m going to show you something important in a second so don’t get too carried away but whenever you need to sort text columns remember we’re only so we’re ordering by user id and score we’re not ordering by the text column but the text column is part of the result set so what we need to do is we need to write user id and score down in order in the order that we’re asking for but all these columns that accompany user id and score i mean i mean aside from user id and score so like id creation date post id and text we have to write those down in the order that we sort user id and score in sql server will estimate for string columns that every row is half full so let’s just to make it very simple let’s say you have a varkar 100 column sql server will estimate that every single row for that varkar 100 column has 50 bytes in it meaning that it’s half full that gives it some fudge factor if some are very full and some are not that full then we kind of meet in the middle and you probably have a proper memory grant the bigger your columns are regardless of how full they are all the way up to max data types which will ask for a big honking memory grant uh the bigger your the wider your columns are your wider your string columns are so if this was like an barcar 1400 or 38 400 or 2800 or whatever whatever numbers add up sql server would ask would assume that that column is half full and ask for more and more memory that sucks that’s not good it’s not a good situation so whenever people have like you know those those big long presentations about right size and data types and like no don’t use date time if you only need a date and don’t use a big int if only need an inch sure sure knock your socks off what i care the most about are those string columns because people will always get carried away and they say i have no idea how much data can it can get in there i better make it a max and whenever they do that the next thing i see is queries like this that start asking for 9.4 gigs of memory to sort that text column by a couple other columns now what the query itself is doing over here right if we go and we look at what that query is actually doing right we don’t have an order by here and we don’t have an order by here what we have is a windowing function and this windowing function is partitioning by user id so that was the first remember when we looked at the execution plan it was order by user id then order by score descending so we’re partitioning by user id which means we have to like you can almost think of partition by like group by without a grouping what it does is sql server just looks at the results and every time it gets to like like for every like bunch of duplicates we’ll say this is like group one this is partition one we find another group of duplicates that’s partition two we find like a single row that’s a new one we’ll say that’s partition three and so on uh let’s see narav says it’s worse when people use car versus var car yeah so for car it assumes complete complete fullness well car car is different because it is completely full anyway right so for car if you have a column that’s car 100 and you only have like three or four characters full in it the other like 96 97 characters is going to be like just padded right it’s like that anti-padding stupid setting or whatever so like yeah it can totally get weird in there but car car is worse and and and var cars of course worse because it’s unicode and it’s double byte uh double byte encoded so you so if you had a nvarkar one uh 100 sql server would count it as a would would you know of course multiply it by two so you get a 100 byte guess there uh with a plc index help here yes but you are jumping the gun lee damn it you’re banned from all my future webcasts but yeah so uh what we have here is a row number function on user id and score descending and since we’re selecting a bunch of other columns sql server needs to write down all of these other columns in order i’m not a huge fan of excel and also not a huge fan of comparing sql server to excel but i think explaining it like an excel file is a lot more relatable to people let’s say you crack open an excel file and it’s full of data going across and you click that little button up in the top left hand corner that highlights all the rows and columns and then you choose to sort data by one column the entire spreadsheet will flip to match the order of that column and that’s a lot like what order by does and when you in a query you don’t really you don’t just order like you don’t just order that column that you’re saying order by you have to order the entire result set for that like for that column so you’re not just like sorting that one column in memory you’re sorting that one column in memory plus all the columns you’re selecting uh if there’s bandwidth issues i don’t know sometimes no it’s it’s it happens sometimes sorry about that there is there is relatively little i can do i can all i can do is for uh for uh my streaming service to to catch up i apologize uh these things happen uh going live is is crazy uh if you know what you know what i’ll do though i’ll wait a second until people say that things have calmed down and then i’ll uh then i’ll then i’ll pick back up yeah this this happened a little bit yesterday too uh it was back at the beginning of the stream when it happened uh today it’s happening at the end of the stream for some reason i don’t know i guess i’m just lucky uh you know perils of the perils the perils of live broadcasting so we’ve got this query here and really what’s what’s what’s asking for the memory is this part of the query where we’re generating a row number where we’re saying or partition by and order by looks good now sweet let’s get back to business then so what we’re going to do is um we’re going to create this index and this index is going to help our windowing function do its work so we’re going to have user id as the first column because in the when we looked at the sort operator user id was sorted by first ascending then we’re going to put score descending as the second key column so our in our index will be ordered by user id and then score descending which is a great index for this query and since i i have relatively little caring uh for what’s going on on this thing because it’s it’s all just a funny uh dev server to me i’m going to include all of the other columns that we need in here in order to cover the query entirely because remember we’re all we’re you know we’re selecting basically everything in the table and then we’re having this row number generate over these two dads right so this is i mean this is i don’t know is this an index that i would create in production if this query was important enough sure but it also might be a little nervous about it but what’s cool now is if i go back to rml utilities and i’ll clear the screen and i’m going to rerun this if we come back over here now and we look at sp pressure detector well nothing’s happening we haven’t given out any memory right there’s no memory given out and there’s no memory granted out here we have granted out a big whopping goose egg no queries are showing up no queries are showing up here because no queries are asking for memory grants this specifically will check for queries that are asking for memory grants one way we can see what’s going on is if we rerun that and we go look at sp who is active this will show us what’s what’s running like oh i should probably not have query plans on for sp who is active should i what that would be scary but if we look over here we’ll see four queries running those are our four queries that we care about and if we look across we can see that they have used very very little memory that’s like what not much that’s a four that’s nothing at all and if we go and look at did i get the execution plan i didn’t let’s go get the execution plan from over here that sounds like a good idea to me so if we run this query and we get the full execution plan this should finish in about six or seven seconds if it doesn’t um then i owe you all a drink the next time i see you whatever you drink it doesn’t matter i hope you like water okay i lied it’s probably about double that okay i lied it might be triple that okay i lied it’s returned a lot of rows okay it didn’t actually take 19 seconds it took about seven and a half seconds up here all right good for us seven seven point four seconds okay close enough close enough but notice that we don’t have a sort operator down here we no longer have to sort data and we no longer have a hash join we have a merge join since everything is in the order that we wanted in which is lovely too i like i like that is this a perfectly tuned great query well you know it runs seven and a half seconds it returns a crap load of road like we might want to do something about this eventually because it this runs for 19 seconds like most of that time is returning three million rows to stupid ssms and the query finishes in seven and a half but what’s important is that if we go and we look at the properties uh if we look at the memory grant info this query isn’t isn’t asking for any additional memory every query plan every query that runs in the world is going to need some memory it’s going to need a little bit of stuff for like operator state and other things but it’s not going to ask for an additional memory grant that other query or rather this query that other query plan which was this query without the index went and asked for nine and a half gigs of memory this one’s not asking for that extra memory grant but you still always need a little bit of something to have the query run because memory is pretty essential for everything so we have that query asking for a little bit of memory but we don’t have it asking for the big grant now sorts are one of those things that can ask for crazy crazy amounts of memory i’m not saying you always have to index to fix them but what i am saying is you should if you have queries that are asking for large memory grants sorts are probably the first thing that i would look at before hash joins or hash aggregates i’m not saying to rule them out entirely i would just usually focus on the sorts first look at the columns we’re selecting like look at like look what we’re ordering by and sorts don’t only happen with like you know windowing functions or just putting an order by in there sometimes you might put a select distinct in there and sql will choose to order by all sorts of things sometimes sql server might choose to implement a merge join or a stream aggregate where we don’t have the data in the order we want and it’ll choose to sort that data going into those operators even sometimes for key lookups it’ll reorder data going in so there’s all sorts of reasons why you might see a sort in an execution plan that have nothing to do with the way you like you writing the query with an order by or something in it that might not ever show up but there are all sorts of things in databases that ordered data is helpful for all right uh i don’t think there’s any questions on that hopefully everyone is still alive uh i guess it looks like a few people left when things got choppy thanks for braving the storm with me it’s not nice make me feel bad now all right anyway let’s go look at one last kind of fun interesting thing let’s go look at how sql server or rather how we can deal with another awful crappy crazy kind of weight that has to do with threads would you ever create an index with descending uh yeah sure i created one up here with it was descending score descending uh it’s it’s a funny trick um so sort of generally uh there is a very funny thing in sql server where uh backwards scans of indexes can’t be parallelized uh and sometimes if you if if you see if you see like uh like a something looks kind of funny let’s like let’s say you have a query plan that is like 99 parallel but you have like one big index scan that for some reason is serial and then like right afterwards it’s a distribute streams or repartition streams and you see that you might want to like again look at the properties of the operator you can look at the properties by either i don’t think i have a query plan open right now but uh let’s just grab this get an estimated plan if you like either you know right click and get properties or hit f4 uh you can see the uh scan direction in the in the in the query plan operators you don’t it doesn’t show up in the tooltip i don’t yeah it doesn’t show up in the tooltip it only shows up in the properties but if you look at this scan direction it ever says backwards and you have a mostly parallel plan except for this one thing that’s uh that’s serial then uh that then you know you what you’re doing is you’re scanning the index in a backwards order and that and that cannot be parallelized right now in sql server that’s supposed to have been done for like i don’t know 10 years or something but just no one’s ever done it so yeah it’s something that i would do um you know uh in certain circumstances but uh and a lot of times it has sort of limited usage so that’s fun let’s see uh sql server licensing oh god i don’t want to talk about that you have any idea what that’s like a that would only be valid for like six months would not be um could not not be useful like in like a year from now like no one would care about it it would be awful uh and i would get sued i would get sued so much i would get sued i would get sued constantly and say i heard eric darling say that we only need a license blah blah blah and then i would say oh boy uh sorry about your audit i’m sorry about the state of that all right so let’s move on a little bit now and let’s talk about how sql server can uh or let’s look at a crazy situation with a different kind of crappy weight this one’s going to be all about threads now if i run this query this query actually finishes relatively quickly relatively quickly it’s a relatively quick query thankfully like i’m happy i’m happy with how fast this query is it’s good that it’s fast right we like fast queries but regardless of how fast this query is this query does something kind of crappy so let’s go look at properties over here and let’s go look at thread stat so this is something that i’m going to say new but by new i mean this came out in sql server 2012. um let’s see stevano says i reckon one can scan through the execution plan yes uh so actually there’s a check in sp blitz cache under expert mode that i wrote that will find backwards scans uh that does show up in there and that is something that you can look for but it’s under expert mode because the number of times that i’ve found it being the root cause of a performance problem have been pretty slim um you know i’m not saying that it’s something that you never want to uh look at and i’m not saying that it’s not something microsoft should like should fit like listen microsoft shouldn’t fix it but uh at the same time like very rarely have i been like aha it was the backward scan that did it we fixed the problem it’s always been like there’s like a thousand things wrong here the backward scan was just one of many and usually if you like you know if you just create an index that is like most of the way to being helpful then the the backward scan just becomes less of an issue um so just just my experience i’m sure someone out there can show you where a backward scan has been like the most awful red-handed red-headed culprit for a query performance but uh you know uh it just it hasn’t been my experience that that that has often been the root cause of an issue but yeah blitzcache will find it if you run expert mode and uh it happens to pick up on a query where that happens so parallel queries are kind of funny parallel queries or rather queries in general uh well if you join tables together if there’s a key lookup you’ll have these branches all right so by branches i mean this is like one branch and then down here this is another branch if we scroll over to the right left a little bit uh you’ll see another branch that sort of diverges off that main path there and in a so when people talk about parallelism settings when people talk about max stop and cost threshold for parallelism cost threshold for parallelism is pretty easy to explain if you hover over the select operator and we zoom in a little bit we can see that the estimated subtree cost for this query is 860 query bucks and so this was a fairly expensive query at least it was expensive enough for sql server to uh or rather the so this is where things get even funnier this query this parallel query cost 860 query bucks sql server chose this parallel query because it was cheaper than the serial query if we just you know let’s just you know for uh for some fun and giggles let’s just stick an option max stop one here and let’s just get an estimated plan real quick if we look at how much of that the serial query cost it’s 991 query bucks a lot of people will look at parallel plans and say i don’t get it why did the why is the parallel plan less than cost threshold for parallelism because the parallel plan doesn’t have to be worse than cost threshold for parallelism the serial version of an execution plan that the optimizer comes up with first that’s what has to be higher than cost threshold for parallelism so at 990 query bucks that’s way higher than what i have it set to on my server on my server my my server which is like 50 query bucks now if you go look at the the the parallel version of the plan all right we’ll go run this real quick again we’ll get rid of that hint and we’ll rerun this if we go look at the parallel version which cost 860 query bucks that is about 130 query bucks cheaper so that’s why sql server chose a parallel plan here totally fine totally like easy pretty easy thing to explain to people max stop is where things get a little bit trickier a lot of people will say well it limits the number of cores that a parallel query can use which is mostly true like some some of my friends might yell at you that it actually limits the number of schedulers that a query can use which is apparently different from cpus in a way that i have never been able to to expunge on them as much as i try to ring them ring these smart people out for details they’ll never budge on it but what maxed up also controls aside from the number of schedulers that you can use is the number of threads that each concurrent parallel branch can use i know that sounds tricky and it is so in this query there are indeed you know three branches off here there’s a little bit more technical detail behind what what defines a branch it’s really the space between any two parallel exchanges so over here we have a repartition streams and down here we have a repartition streams and over here we have another repartition streams so technically this is one branch right technically these operators between a repartition streams are a branch ditto some of these over here like when we go past that repartition streams we might we might call all the operators between the gather streams and the repartition streams another branch which should be all these operators now there’s a repartition streams down here too so things get things just get all sorts of weird but this query does have this query has three parallel three branches that could run concurrently you might see parallel queries that have many many more branches than show up down here what the what branches measures here is not the total number of branches but the total number of branches that could possibly be running at the same time that could be running concurrently there are again going back to memory consuming operators hashes and sorts those are also what we call stop and go operators which means all the rows that they need to process need to show up there before they can start running that’s one thing that can sort of separate which branches can run concurrently in this query plan aside from the fact that we have repartition streams operators that that define branches we have hash joins like this one right here all right there’s a hash join right here which means that all the rows from this part of the branch have to show up here so we can build the hash table all those rows have to show up and then once that starts kicking off this can start running while that’s running rather well while that’s running uh and rows start coming out of here and passing through the hash join here then all sorts of stuff can happen in here up into the point where we need to start building another hash table here and then once that hash table is built and we start probing in down here all the rows that start passing out from down here can start coming out up here so at any given time we can have three concurrent parallel branches and that gets borne out when we look at the thread stat properties of this plan now i have max stop set to four so my degree of parallelism for this is four the number of threads that this branch uses is 12. i want to say the reservation matches here it does so we’ve reserved and used 12 threads so we have dot four right we have max rear parallelism set to four so we can use four schedulers to run this query but we can use four threads per branch for this query meaning all together this query will reserve and hopefully you and hopefully use all 12 threads right three times four you got it i just i just like to explain it the long way because a lot of people when i just if i just said three times four they would say huh but yeah three times four is 12 so we have 12 used threads 12 reserve threads and we have three parallel branches for a dot four query so i promise you it all well it doesn’t add up does it it all multiplies up good that it multiplies up but and this is where things get tough if we look at the number of schedulers the number of worker threads that my uh i just like saying schedulers but if you look at the number of worker threads that my server has it’s 576 total now this is a microsoft supplied algorithm if we take 512 plus the count of schedulers that are visible online minus four times 16 that is how many worker threads you have on your server unless someone has messed with the max worker thread setting that is the way it will happen i want to say things change a little bit beyond from 64 cores and up but this is what we have and what’s what’s terrible is that it’s it’s shockingly easy to run out of cpu of cpu of worker threads so what i’m going to do is and i’m going to i’m going to hope that this works because it worked last time is i’m going to change the connection here and i’m going to use the admin connection and it’s going to say that it failed which is okay but i’m using the remote dac right now and but you can tell that i am because i have this admin connection down here and the reason that i’m using this is because when i do this cpu demo and i start to run out of worker threads it becomes very very difficult very very difficult to connect to the server and even run simple dmv queries so you can see i have 576 threads right now sql server in the background just for whatever is using 28 threads for other things right bad and what things i don’t know they might be bad they might be good i don’t i don’t really don’t know now what i’m going to do is go back to o stress and i’m going to run a whole crap load of queer of copies of this query that take 12 worker threads i’m going to exacerbate the situation sure i could try to play with it so we got like the exact number and took out the exact but blah blah blah but i just really like to kick the crap out of it here so people understand what things what things will look like when when everything kind of goes goes south on them so i’m going to run this and we’re going to immediately have exactly what i want i’m going to run this one more time for good luck and then i’m going to kill this off so sp pressure detector we’ve changed us to be from memory to look at cpu we’ve connected via the remote dac so that we don’t get thread pooled out of running these queries but this is what happens we had we had a whole bunch of copies of this query running taking 12 worker threads for each well i want to say taking 12 worker threads for each copy that’s not going to totally be true and i’ll show you that i’ll show you what i mean in a minute but if you look at what happened here we have 576 total threads we’ve used 612 which gives us a grand total of negative 36 threads we have 221 threads waiting for a cpu and 96 requests waiting for threads those request those 96 requests are all going to be in this section if we look down here we’ll see that for the section of queries or for that section we have 96 rows right so that’s the 96 requests waiting for threads requests waiting for threads is where we have thread pool weights if we look in here this is where we’re going to see those 96 rows now where things get very very tricky and very very ugly is when you have a script that goes to show you what’s currently running on your server what’s it what’s the first thing it’s going to do it’s going to join in some order dm exec requests to dm exec sessions and it’s going to join them together on session id the problem with that is that if it’s an inner join you’re not going to see any of this because this session id column is completely null there is no data there is no session id in here to join those tables together on.
When SQL Server runs out of worker threads, we can’t even give queries a spid to run on. That’s how completely out of CPU resources we are.
We are completely shot. When I ran this the second time, queries had been waiting nearly six and a half seconds to get worker threads to execute.
All right, and if we scroll down this list, we’re going to see all 96 queries. This one was waiting almost three seconds, but from almost three seconds up to about six and a half seconds just to get threads to run.
If we weren’t connected via the DAC and I tried to run this query, it would time out, SSMS would throw an error message, and we would say, I don’t know, server’s down, restart it.
We would restart it, and things would probably go back to normal. But that’s no fun, right? That’s no fun. I like to give you the information that you would get if you had listened to me about setting your server up right.
And you would enable the remote DAC. That’s all I want. Now, the third set of results from SP Pressure Detector is going to give you CPU-intensive queries.
Now, these are all queries that at least, I mean, do they all have session IDs? I forget. Yeah, these queries all have session IDs. So this is 243 rows.
So these 243 queries all got spids, and we’re all able to start running. But there is a big but here, and this is the kind of big but that Sir Mixalock does not care for.
If we go over here and look at what happened to some of these queries, we’ll see that very many of them are running at DOP4 and have reserved those 12 worker threads that we talked about.
But if we start scrolling down a little bit, we will eventually see that change. What happened?
DOP is two here, and we have six worker threads. DOP is one here. And this is going to be null for the worker thread count because we can generally infer enough that a DOP1 query is only going to need one worker thread.
We can do that. But what’s super sucky, crappy, just plain mean is that SQL Server won’t tell us that these queries were actually running at DOP1.
So what we have here, I’m going to bring only the DOP1 queries into the screen. This is all DOP1. And if we go all the way across to where the query plans are, did I go too far or not far enough?
There we go. So these queries were all running at DOP1, but the query plan that we see from them is going to tell us that it’s running in parallel. So SQL Server, when you start running out of worker threads, one thing that SQL Server will do is start downgrading DOP for your parallel queries.
Remember, we have this one query up here that was running at DOP2, and then all of a sudden it drops off to DOP1. So SQL Server, the first thing it will do is say, parallel queries, sorry, I don’t have room for you.
We’re going to run you at DOP1. If you don’t like it, talk to the person who bought the CPUs, or talk to the person who tunes the queries. You know, I can’t do anything for you.
No room at the end. But we’ll see that a whole lot of these were actually running at DOP1. So SQL Server actually did a lot, a lot, to try and avoid running out of worker threads. But at the end of the day, we just completely overwhelmed it with queries, and we had 96 of them that just couldn’t even get a worker thread.
When you can’t get a worker thread, you end up showing this thread pool weight. We’ve looked at two pretty terrible weights today. We looked at resource semaphore, and we’ve looked at worker threads, or thread pool rather.
If you see a lot of these weights on your server, your server is in tough, tough shape. He says, is there a way to set that threshold where it starts limiting threads? No, I don’t think that’s something you can set even in resource, Governor.
I think that’s just something that SQL Server fires off internally at some threshold. I’m not sure what it is or where. There might be a weird trace flag for it. I don’t know.
I wish I knew. I wish I was that smart. But yeah, I don’t know. But no, I don’t think there is a way to do that. I think that’s like a judgment call from SQL Server. It’s like, at what point does the pain here mean you call 911?
I don’t know. I’m sure that threshold is different for different circumstances and different people. But pretty cool there. But of course, the main thing with this query, if we think about what that query is doing, this query runs pretty quickly.
It’s parallel. But if we throw enough copies of it out there, it’ll suck. But if you go look at the query, we’re joining stuff together. We have a where clause on reputation.
But at the same time, we don’t really have indexes that support this query very well. He says, I would be more conservative than SQL. Well, you know, I don’t know if that’s easy.
In some regards, it’s easy. In some regards, that’s hard. It’s a hard decision to make. But really, the problem here is that we just don’t have very good indexes to support this query that we’re running.
So let’s create some indexes. Because remember, the whole point of this session is about problems you can fix with indexes. And this is another problem that you can pretty reliably fix with indexes.
Because with the right indexes in place to help queries find data and join things together and sort of get things done in the right way, we can end up with a query that runs pretty quickly and doesn’t need to go parallel.
Right? So this thing finishes in 849 milliseconds. There’s no parallelism going on here, which means that we are running at DOP1, which means that we could run 500 copies of this without SQL Server really, you know, go and crap things out.
Let’s see. Ronald says, can a sleeping session still use a lot of CPU? So the way that the DMVs work is they just tally things up. Right?
They just tally things up as things run. So a really awesome thing to do if you have queries that are sleeping that have a high amount of CPU is you can do exec SP who is active and you can do at, I want to say it’s delta interval equals 5.
I might be, oops, I might be wrong about the delta interval. No, I’m right. And what this will do is it will look at how much progress, I’ll put that into chat, it’ll look at how much progress or how much resources your query has used over a span of time.
Right? So for this one, I ran it for 5 seconds. So what SP who is active will do is it’ll go through and do like the initial run of SP who is active. It’ll wait 5 seconds. Like if you’ve ever used SP blitz first and done like the second sample, it’s totally like, it’s almost the same thing except for who is active.
And what it will do is it will go through and it will add these columns in called delta. And these delta columns will tell you how much resources that query has used over a span of time.
So if you have a sleeping session and that sleeping session has a high amount of CPU, run who is active with a delta interval and see if it’s still accumulating CPU.
If a session is asleep, that usually means that the query has finished and either the application has forgot to close it or some weird connection pooling thing is happening.
Maybe there’s a leak, but the connection hasn’t closed. So typically a sleeping session isn’t going to keep accumulating resource usage if it’s been like, you know, sleeping for a long time. You know, usually something has to be like running or runnable in order to get more stuff.
Let’s see. Wes says, can’t I just tell my director that I need more resources and ignore all this? Yes, up to a point. But, you know, it depends on where the budget for more resources comes from.
So if the budget for more resources comes from your, like your bonus or your paycheck, I might want to, I might want to fix a problem. Max stop one is the ultimate solution.
Yes, if you want everything to be terrible. Right? You want everything to be terrible, max stop one is a good solution. I like, I like parallelism. I love parallelism.
It’s one of my favorite things. Okay, let’s see here. What else do I have left? I think that’s it. Is that the end? That is the end. Wow, that’s the end. Good for us. So, what did we learn?
All sorts of ways to fix problems with indexes. We looked at how to solve performance problems, how to fix spools, how to fix blocking, and how to fix queries that just use way too many resources.
I think it’s a pretty good run. It’s been almost two hours since I started. So I’m going to stick around for another like five or so minutes right until the top of the hour if you have any more questions, comments, anything like that.
Stick around for that. But other than that, I could use, I’m starting to get this, so I could use some liquid, and I could use, I don’t know, I would like to sit down again, to be honest with you.
But if you need, if you have any other questions, anything else you want to ask about, I know there was someone on earlier who asked for a copy of the script. I’ll put that up in the resources either on Twitch or on YouTube.
I just have to, I have to make sure that I have the most recent version of everything all zipped up, and then I’ll get that out there. Let’s see. Tell your director that, then fix the issue.
You’ll be swimming in resources. Yeah, yeah. But, and then you could, you know what you could do after that too, is you could tell the director that you fixed the problem and give a bunch of resources back and say, look at all the money I saved you.
Give me a raise. This is something that people love doing during pandemics. Says, this is great. Your streams are top notch. Thank you.
I hope I can keep, I hope that I can keep up the top notchness. I’m thinking about bringing back the office hoursy type thing because that seems, I don’t, I don’t think anyone or really anyone’s doing that either on Twitch or YouTube or anywhere right now.
So, you know, maybe I’ll start doing something like that once a week again. I don’t know. Yeah, I’ll get the scripts out as soon as I can.
I’m gonna, I’m gonna go faint for like 20 minutes when I’m done and then, then I’ll come, I’ll get the scripts ready. All right. I’ll start doing them again.
It was tough. It was tough last time around. There’s, I don’t know, it was only on YouTube and the setup was rather unsophisticated and, you know, the schedule got tough because, you know, once, once, once like client work really picked up, I couldn’t always do the Friday thing.
So, you know, ah, well, Mr. P. Shaw, I will, I will pick it back up. If you come to me day one for a 64 core box, you buy it.
In day two, you say, by the way, I tune the code, we can run on four cores. I’m not gonna be smiling. Yeah, I guess, but just think of all the room to grow you’ll have. Think about, think about the upward expansion that you have there.
Think, think about that. You have 60 cores that you can grow into. Oh, yeah, I know. It’s, it’s so tough. Sometimes services get, sometimes services get, one service is blocked, another one doesn’t.
If I, if I do it, I’m gonna do it just like these and it’s gonna be YouTube and Twitch. I don’t really have any other places to stream things out to. So if anyone has like suggestions for other services they can stream, that I can stream to, that would be, that would be it.
Gina R. Fria says, I have simple queries running 10,000 times an hour. How do I fix this? That, that, that is something you can really only fix with developers. Mixer.
I don’t know. I’ve never heard of Mixer. I’m, I’m old, but I’ll, I’ll look into it. But that, that is really something that only developers can fix because things that are running that frequently, are they’re not running that?
Well, okay, I’m going to take that back. I’m going to walk that back a little bit in a minute, but if you have queries running that frequently from the application, then that’s something that developers, developers would have to fix either by, you know, not, I’ll say something obvious, not running those queries so much or having those queries hit like some caching layer and only refreshing the cache for those queries like less frequently.
The other times that I see simple queries running constantly like that is when you have scalar valued functions or multi-statement table valued functions that are called in queries that return lots and lots of rows because one kind of hidden issue with, with, with functions like that is that they don’t run once per query.
They run once per row returned by the query. So that can, they can really sort of, they can really run quite frequently if you call them in queries that return or process lots of rows.
It could also be like, you know, it could also be like cursors or something that, you know, you know, couldn’t fix, but there’s no, there’s no like no button you can push in SQL Server that says, you’re only allowed to run a hundred times an hour.
I wish there was, but that might be dangerous. If only SQL Server had a caching layer, I guess, I don’t know. I don’t, I don’t want that.
If anyone from Microsoft is listening or watching, I don’t, I don’t actually want that. But yeah, that is, that is typically a developer problem. That’s typically not something that a DBA can, can fix or limit on their own unless it’s happening from functions.
What I would say is if you want to, if you want like sort of a decent way to, oops, I did that all wonky. You want a decent way to track that down. Oh my God.
Hmm. I can’t type today. This guy, this is why I type everything ahead of time because I can’t type, especially when people are watching. If we do SP, which let’s cash and we do sort order equals XPM.
XPM stands for executions per minute. And what we can catch with executions per minute is stuff that executes quite frequently. And it just might be a sort of easy way to catch high, high frequency execution things.
So unfortunately, I don’t have anything all that interesting in here now. We could also just do plain executions and run that.
And this would sort the plan cache by executions. And this is another way to kind of find things that execute frequently that, but, you know, just may not use a ton of resources.
So like this has executed 243 times. Executions per minute isn’t something that the plan cache directly tracks. It’s something that Blitz cache tracks by looking at the number of minutes between when the plan was created and last executed, and then doing some division to see how many times it was executed in those minutes.
So it’s coming up as zero here because of how fast those 243 executions happen. But generally, using either XPM or executions, you can catch what’s happening.
If they are functions, then they might be things that you could rewrite and fix. But if they are, if they are, you know, just pure like, I don’t know, like entity for ORM queries, something like that coming in, then it’s not anything you can do.
Uh, Kryron says, when we use max.dop8 and index, how is the index structure? Uh, I only use it so the index, uh, creates a little bit faster.
Um, there’s, there’s really nothing about the way the index is structured that, uh, it changes or helps. Um, at least for rowstore indexes, for columnstore indexes, dop can affect compression and typically the lower dop, the lower dop is, the better compression you get, or rather the few open, like row groups or whatever you can have.
But for rowstore indexes, I only do it here. I really only do it here during demos so that the indexes create a little bit faster. It’s really not, um, really not anything like, it’s really not any special magic, like, you know, God mode, ID clip, you know, contra code thing to get extra index lives or anything like that.
All right. I’ll give it another minute. Any other questions? Anyone else want to talk about anything? This went on longer than I thought it would.
I didn’t realize I had so much to say until I started talking. And then I, and I just kind of went off the rails. And now I have nothing.
Now I’m just brain dead and have nothing to say, which is probably nice. Like some people probably are grateful that I’m brain dead and have nothing to say. All right. Anyway, uh, thanks for showing up. Thanks for hanging out.
Thanks for watching. Um, if you have not already done it and you are the type of person who enjoys SQL Server content, um, if you follow me on Twitch or as, as the kids say, like, and subscribe over on YouTube, uh, you’ll get notified whenever I start doing one of these things.
If you follow me on Twitter, you’ll, you’ll also get that. Um, but you know, it’s, it’s always nice to, you know, have a good crowd in here to do things. I like having lots of people, lots of questions, you know, lots of different levels of experience.
So, you know, come on back, um, you know, tell a friend, invite, whatever it is. I forget how the, I forget how all this stuff works, but you know, please, you know, follow along. Uh, I’m going to be doing a lot more of these, uh, now that I’m kind of set up to do it, and I have all sorts of fun things, uh, on my mind, then I, I hope that, uh, you find it useful and entertaining and enjoyable, and I will see you, um, I don’t know, maybe, maybe I’ll even come back tomorrow and do something, but thanks for showing up, thanks for hanging out, and I will see you next time.
Adios. Adios.
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Why is IS NULL (not to be confused with ISNULL, the function) considered an equality predicate, and IS NOT NULL considered an inequality (or range) predicate?
It seems like they should be fairly equivalent, though opposite. One tests for a lack of values, and one tests for the presence of values, with no further examination of what those values are.
The trickier thing is that we can seek to either condition, but what happens next WILL SHOCK YOU.
Ze Index
The leading column in this index is NULLable, and has a bunch of NULLs in it.
CREATE INDEX nully_baby
    ON dbo.Posts(LastEditDate, Score DESC);
Knowing what we know about what indexes do to data, and since the LastEditDate column is sorted ascending, all of the NULL values will be first, and then within the population of NULLs values for Score will be sorted in descending order.
But once we get to non-NULL values, Score is sorted in descending order only within any duplicate date values. For example, there are 4000 some odd posts with a LastEditDate of “2018-07-09 19:34:03.733”.
Why? I don’t know.
But within that and any other duplicate values in LastEditDate, Score will be in descending order.
Proving It
Let’s take two queries!
SELECT TOP (5000)
    p.LastEditDate,
    p.Score
FROM dbo.Posts AS p
WHERE p.LastEditDate IS NULL
ORDER BY p.Score DESC;

SELECT TOP (5000)
    p.LastEditDate,
    p.Score
FROM dbo.Posts AS p
WHERE p.LastEditDate IS NOT NULL
ORDER BY p.Score DESC;
Which get very different execution plans.
you can’t get it
But Why?
I know, I know. The sort is technically non-deterministic, because Score has duplicates in it. Forget about that for a second.
For the NULL values though, Score is at least persisted in the correct order.
For the NOT NULL values, Score is not guaranteed to be in a consistent order across different date values. The ordering will reset within each group.
We’ll talk about how that works tomorrow.
Thanks for reading!
Going Further
If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.