Making The Most Of Temp Tables Part 4: Batch Mode

Le Big Zoom Zoom


When you have queries that need to process a lot of data, and probably do some aggregations over that lot-of-data, batch mode is usually the thing you want.

Originally introduced to accompany column store indexes, it works by allowing CPUs to apply instructions to up to 900 rows at a time.

It’s a great thing to have in your corner when you’re tuning queries that do a lot of work, especially if you find yourself dealing with pesky parallel exchanges.

Oh, Yeah


One way to get that to happen is to use a temp table with a column store index on it.

SELECT 
    v.UserId, 
    SUM(v.BountyAmount) AS SumBounty
FROM dbo.Comments AS c
JOIN dbo.Votes AS v
    ON  v.PostId = c.PostId
    AND v.UserId = c.UserId
GROUP BY v.UserId
ORDER BY SumBounty DESC;

CREATE TABLE #t(id INT, INDEX c CLUSTERED COLUMNSTORE);

SELECT 
    v.UserId, 
    SUM(v.BountyAmount) AS SumBounty
FROM dbo.Comments AS c
JOIN dbo.Votes AS v
    ON  v.PostId = c.PostId
    AND v.UserId = c.UserId
LEFT JOIN #t AS t 
    ON 1 = 0
GROUP BY v.UserId
ORDER BY SumBounty DESC;

Keep in mind, this trick won’t work if you’re on SQL Server 2019 and using in memory tempdb. But aside from that, you’re free to rock and roll with it.

If you end up using this enough, you may just wanna create a real table to use, anyway.

Remarkable!


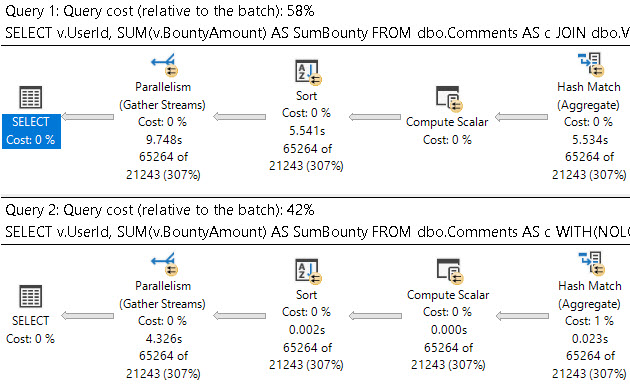
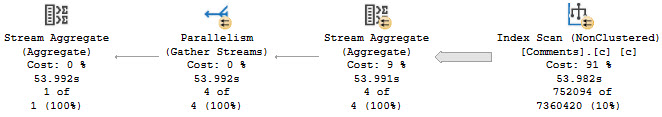
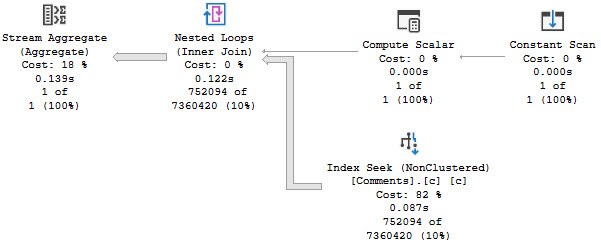
If we look at the end (or beginning, depending on how you read your query plans) just to see the final times, there’s a pretty solid difference.
SQL Server Query Plan
you can’t make me

The first query takes around 10 seconds, and the second query takes around 4 seconds. That’s a pretty handsome improvement without touching anything else.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Making The Most Of Temp Tables Part 3: More Opportune Indexes To Make Queries Go Faster

I Know You


You have too many indexes on too many tables already, and the thought of adding more fills you with a dread that has a first, middle, last, and even a confirmation name.

This is another place where temp tables can save your bacon, because as soon as the query is done they basically disappear.

Forever. Goodbye.

Off to buy a pack of smokes.

That Yesterday


In yesterday’s post, we looked at how a temp table can help you materialize an expression that would otherwise be awkward to join on.

If we take that same query, we can see how using the temp table simplifies indexing.

SELECT
    p.OwnerUserId,
    SUM(p.Score) AS TotalScore,
    COUNT_BIG(*) AS records,
    CASE WHEN p.PostTypeId = 1 
         THEN p.OwnerUserId
         WHEN p.PostTypeId = 2
         THEN p.LastEditorUserId
    END AS JoinKey
INTO #Posts
FROM dbo.Posts AS p
WHERE p.PostTypeId IN (1, 2)
AND   p.Score > 100
GROUP BY CASE
             WHEN p.PostTypeId = 1 
             THEN p.OwnerUserId
             WHEN p.PostTypeId = 2 
             THEN p.LastEditorUserId
         END,
         p.OwnerUserId;

CREATE CLUSTERED INDEX c ON #Posts(JoinKey);

SELECT *
FROM #Posts AS p
WHERE EXISTS
(
    SELECT 1/0
    FROM dbo.Users AS u
    WHERE p.JoinKey = u.Id
);

Rather than have to worry about how to handle a bunch of columns across the where and join and select, we can just stick a clustered index on the one column we care about doing anything relational with to get the final result.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Making The Most Of SQL Server Temporary Tables Part 2: Materializing Expressions

Bad Data


A lot of the time when I see queries that are written with all sorts of gymnastics in the join or where clause and I ask some questions about it, people usually start complaining about the design of the table.

That’s fine, but when I ask about changing the design, everyone gets quiet. Normalizing tables, especially for Applications Of A Certain Age™ can be a tremendously painful project. This is why it’s worth it to get things right the first time. Simple!

Rather than make someone re-design their schema in front of me, often times a temp table is a good workaround.

Egg Splat


Let’s say we have a query that looks like this. Before you laugh, and you have every right to laugh, keep in mind that I see queries like this all the time.

They don’t have to be this weird to qualify. You can try this if you have functions like ISNULL, SUBSTRING, REPLACE, or whatever in joins and where clauses, too.

SELECT
    p.OwnerUserId,
    SUM(p.Score) AS TotalScore,
    COUNT_BIG(*) AS records
FROM dbo.Users AS u
JOIN dbo.Posts AS p
    ON u.Id = CASE 
                   WHEN p.PostTypeId = 1 
                   THEN p.OwnerUserId
                   WHEN p.PostTypeId = 2
                   THEN p.LastEditorUserId
              END
WHERE p.PostTypeId IN (1, 2)
AND   p.Score > 100
GROUP BY p.OwnerUserId;

There’s not a great way to index for this, and sure, we could rewrite it as a UNION ALL, but then we’d have two queries to index for.

Sometimes getting people to add indexes is hard, too.

People are weird. All day weird.

Steak Splat


You can replace it with a query like this, which also allows you to index a single column in a temp table to do your correlation.

SELECT
    p.OwnerUserId,
    SUM(p.Score) AS TotalScore,
    COUNT_BIG(*) AS records,
    CASE WHEN p.PostTypeId = 1 
         THEN p.OwnerUserId
         WHEN p.PostTypeId = 2
         THEN p.LastEditorUserId
    END AS JoinKey
INTO #Posts
FROM dbo.Posts AS p
WHERE p.PostTypeId IN (1, 2)
AND   p.Score > 100
GROUP BY CASE
             WHEN p.PostTypeId = 1 
             THEN p.OwnerUserId
             WHEN p.PostTypeId = 2 
             THEN p.LastEditorUserId
         END,
         p.OwnerUserId;

SELECT *
FROM #Posts AS p
WHERE EXISTS
(
    SELECT 1/0
    FROM dbo.Users AS u
    WHERE p.JoinKey = u.Id
);

Remember that temp tables are like a second chance to get schema right. Don’t waste those precious chances.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Making The Most Of Temp Tables In SQL Server Part 1: Fully Parallel Inserts

Sing Along


If you have a workload that uses #temp tables to stage intermediate results, and you probably do because you’re smart, it might be worth taking advantage of being able to insert into the #temp table in parallel.

Remember that you can’t insert into @table variables in parallel, unless you’re extra sneaky. Don’t start.

If your code is already using the SELECT ... INTO #some_table pattern, you’re probably already getting parallel inserts. But if you’re following the INSERT ... SELECT ... pattern, you’re probably not, and, well, that could be holding you back.

Pile On


Of course, there are some limitations. If your temp table has indexes, primary keys, or an identity column, you won’t get the parallel insert no matter how hard you try.

The demo code is available here if you’d like to test it out.

SQL Server Query Plan
amanda lear

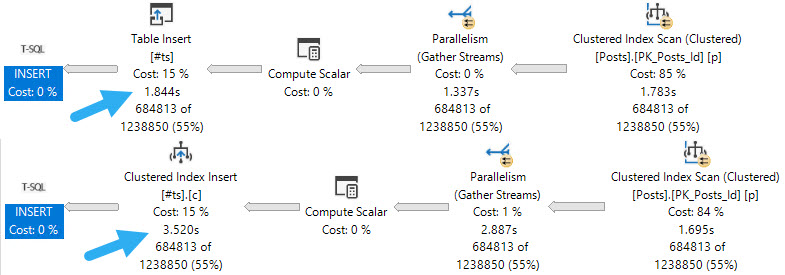
The first thing to note is that inserting into an indexed temp table, parallel or not, does slow things down. If your goal is the fastest possible insert, you may want to create the index later.

No Talent


When it comes to parallel inserts, you do need the TABLOCK, or TABLOCKX hint to get it, e.g. INSERT #tp WITH(TABLOCK) which is sort of annoying.

But you know. It’s the little things we do that often end up making the biggest differences. Another little thing we may need to tinker with is DOP.

SQL Server Query Plan
little pigs

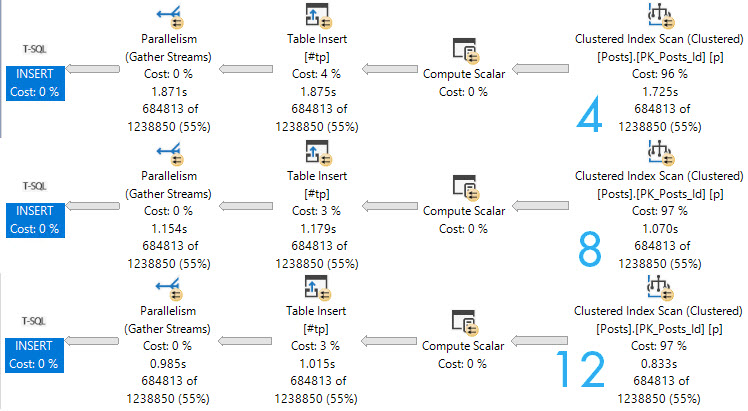
Here are the query plans for 3 fully parallel inserts into an empty, index-less temp #table. Note the execution times dropping as DOP increases. At DOP 4, the insert really isn’t any faster than the serial insert.

If you start experimenting with this trick, and don’t see noticeable improvements at your current DOP, you may need to  bump it up to see throughput increases.

Also remember that if you’re doing this with clustered column store indexes, it can definitely make things worse.

Page Supplier


Though the speed ups above at higher DOPs are largely efficiency boosters while reading from the Posts table, the speed does stay consistent through the insert.

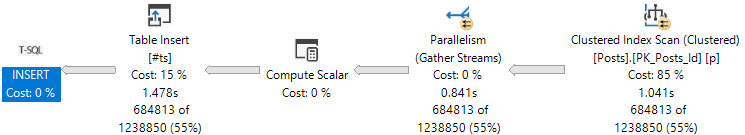
If we crank one of the queries that gets a serial insert up to DOP 12, we lose some speed when we hit the table.

SQL Server Query Plan
oops

Next time you’re tuning a query and want to drop some data into a temp table, you should experiment with this technique.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Announcing The Darling Data Vantablack Friday Sale!

A Word From Our Sponsors


First, a huge thank you to everyone who has bought my training so far. You all are incredible, and I owe all of you a drink.

Your support means a lot to me, and allows me to do nice stuff for other people, like give training away for free.

So far, I’ve donated $45k (!!!) worth of training to folks in need, no questions asked.

Next year, I’d like to keep doing the same thing. I’d also like to produce a whole lot more training to add value to the money you spend. In order to do that, I need to take time off from consulting, which isn’t easy to do. I’m not crying poor, but saying no to work for chunks of time isn’t easy for a one-person party.

I’m hoping that I can make enough in training bucks to make that possible.

Because this sale is extra sale-y, I’ve decided to name it after the blackest black known to man.

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
SQL Ciderday

Tis The Season


Look, it’s the Friday after Thanksgiving, and we’re both too tired to deal with SQL Server. Rather than get all worked up and worn out by talking about databases, today we’re going to talk about how to make cider from scratch.

It’s a noble pursuit, making cider, and it makes things smell good.

It’s also great with some rum in it, which is an easy way to keep warm in these long, cold, endless winter months (provided you’re in the correct hemisphere).

Good Lookin’


The first thing you’re gonna need is a large pot. It doesn’t matter much what kind it is, but it has to be big enough to hold 12 apples and two oranges, and just about a cup of water per apple. I use a 7.25 quart Dutch Oven, which is just big enough to hold everything.

The next thing you’re gonna need is 12 apples. It doesn’t matter much what kind, and you can even use a whole bunch of different kinds all in together. If you’re feeling crazy, you can sub in 4-6 pears.

Don’t just throw them in the pot though! You gotta chop the apples to get rid of the cores. They don’t need to be diced down really fine, because we’re gonna mash them up once they’re soft enough. If you’re putting pears in, cut off the stems and get rid of the seeds if you can.

So far, so good. Our apples (or pears!) are chopped, our oranges are peeled and quartered, and we’ve got them in a pot with about 14 cups of water.

Now to add the stuff that makes the magic happen:

A lot of recipes will have you add a sweetener. Don’t do it. It’s gross, and anyone who tells you to do it is gross.

Good Cookin’


Bring all that to a boil, and let it cook uncovered for an hour or so, until the apples (or pears!) are soft enough to mush. I do everything with a slotted spoon, since my pot is pretty deep, and the masher I have is too short for the job.

Once you’ve got the fruits mashed up pretty well, turn the heat down to a little less than half of whatever full blast is on your burner. Leave it uncovered, and let it reduce until the pot is about half full. You should be tasting as it reduces. If you stop too soon, it’ll be watery. You don’t want that, and you also don’t want cider gravy.

When things are reduced, kill the heat and let it cool for an hour. If you have a thermometer, wait until things are at 100F or below. You’re gonna need a strainer to pull out the pulp. This part is annoying, because you do need to let the fluid drain out from the pulp a bit. I’ll usually use a spoon to move the pulp around so it drains faster.

After all the pulp is out, you’ll wanna pour what’s left through the strainer again to get out any sediment, and errant chunks.

Mmm. Errant chunks.

But hey, now you’ve got cider! I store mine in mason jars, because uh… we had them around. I don’t think they have any special powers.

Good Drinkin’


If you’re into alcoholic beverages, adding in rum is a good choice. I like El Dorado 15 for the job, but you’re free to pick your own poison. Garnish with an orange, or just leave it off because garnishes just get in the way of drinking, ha ha ha.

If you’re bulking, you can also stir in a teaspoon of butter, just probably grab the unsalted stuff, here.

Another good option is Balvenie Caribbean Cask, which is a scotch with some rum-ish properties, in case you couldn’t tell by the name.

You can also drink it just fine on its own, but I started making cider specifically to make cocktails, so there we are.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
An Edge Case When Working With Date Parameters In SQL Server

Wheeze Man


When people tell you that working with correct data types is important, it’s for a variety of very good reasons.

Not only can you avoid performance issues, but you can avoid strange query plan distractions, too.

Let’s look at an example for when you use date parameters against datetime columns.

Wrong And Mean


Index from outta nowhere pow!

CREATE INDEX pe ON dbo.Posts(LastEditDate);

The important thing about the LastEditDate column in the Posts table is that it’s nullable.

Not all posts will get edited. Especially mine. They’re always correct the first time.

Basically read only, if we’re being honest about things.

Or maybe it’s about 50/50.

If your columns aren’t nullable, you’ll run into far fewer problems and ambiguities.

I’d like a new data type called ABYSS. Or maybe VOID.

The Problem: Wrong Data Type And NULL Checks


DECLARE @d date = '20170601';
DECLARE @sql nvarchar(MAX) = N'
SELECT
    COUNT_BIG(*) AS records
FROM dbo.Posts AS p
WHERE p.LastEditDate > @d
AND   p.LastEditDate IS NOT NULL;'

EXEC sp_executesql @sql, 
                   N'@d date', 
                   @d;
GO

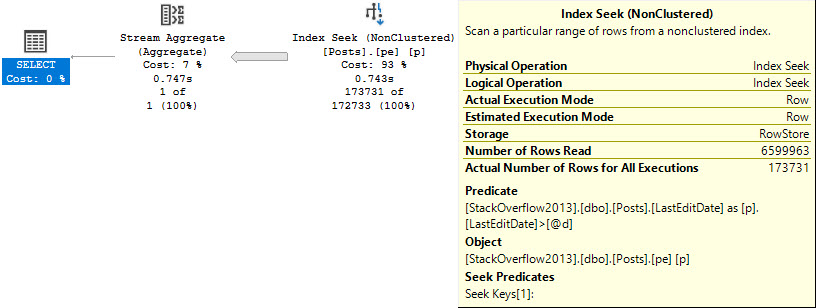
If we pass in a parameter that has a date datatype, rather than date time, an odd thing will happen if we add in a redundant IS NOT NULL check.

SQL Server Query Plan
yortsed

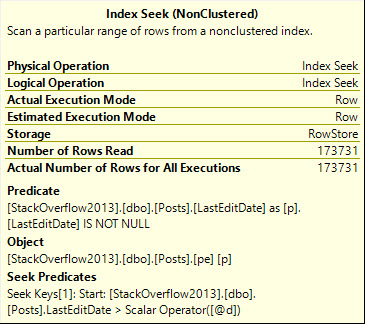
The seek predicate will only seek to the first non-NULL value, rather than immediately to the start of the range of dates we care about, which means we end up reading a lot more rows than necessary.

Note the query runtime of 743 milliseconds, and that we end up reading quite a few more rows than we return.

And here I was told Seeks are always efficient ?

Solution One: Stop Checking For NULLs


If we either stop checking for NULLs, we’ll get around the issue.

DECLARE @d date = '20170601';
DECLARE @sql nvarchar(MAX) = N'
SELECT
    COUNT_BIG(*) AS records
FROM dbo.Posts AS p
WHERE p.LastEditDate > @d;'

EXEC sp_executesql @sql, 
                   N'@d date', 
                   @d;
GO

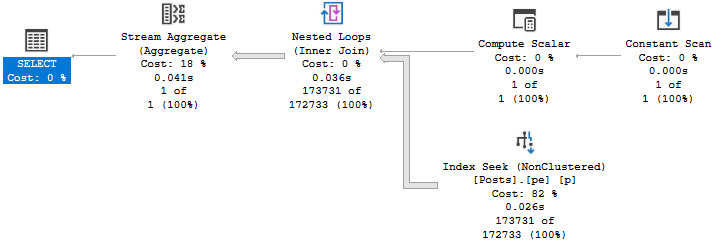
The plan for this query looks a bit different, but performance is no worse for the wear.

SQL Server Query Plan
still using the wrong datatype

Note the 25 millisecond execution time. A clear improvement over the 743 milliseconds above. Though the query plan does look a bit odd.

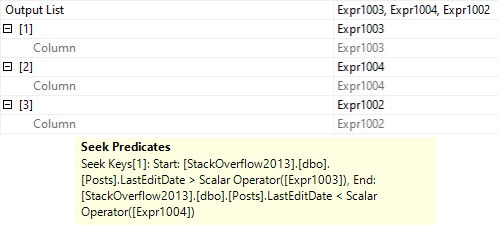
The compute scalar gins up a date range, which is checked in the seek:

SQL Server Query Plan
HELLO COMPUTER

I wonder what Expr1002 is up to.

Solution Two: Just Use The Right Datatype To Begin With


In reality, this is what we should have done from the start, but the whole point of this here blog post is to show you what can happen when you Do The Wrong Thing™

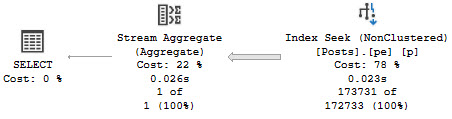
When we use the right datatype, we get a simple plan that executes quickly, regardless of the redundant NULL check.

DECLARE @d date = '20170601';
DECLARE @sql nvarchar(MAX) = N'
SELECT
   COUNT_BIG(*) AS records
FROM dbo.Posts AS p
WHERE p.LastEditDate > @d
AND   p.LastEditDate IS NOT NULL;'

EXEC sp_executesql @sql, 
                   N'@d datetime', 
                   @d;
SQL Server Query Plan
no fuss, no muss

Here, the NULL check is a residual predicate rather than the Seek predicate, which results in a seek that really seeks instead of just meandering past some NULLs.

SQL Server Query Plan
gerd jerb

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Be Careful Where You Use AT TIME ZONE In Your SQL Server Queries

Universal


Databases really do make you pay dearly for mistakes, and new linguistic functionality is not implemented with performance in mind.

I’ve written before about how to approach date math in where clauses: Where To Do Date Math In Your Where Clause

And it turns out that this lesson is brutally true if you need to pass time zones around, too.

Wherely


To make things as easy as possible on our query, let’s create an index up front:

CREATE INDEX c ON dbo.Comments(CreationDate);

Now let’s pretend that we need to query the Comments table with some time zone consideration:

DECLARE @d datetime = '20131201';

SELECT 
    COUNT_BIG(*) AS records
FROM dbo.Comments AS c
WHERE c.CreationDate AT TIME ZONE 'UTC+12' >= @d
OPTION(RECOMPILE);
GO

We’re going to wait a very long time. Assuming that a minute is a long time to you. It is to me, because every minute I spend waiting here is a minute I’m not doing something else I’d rather be doing.

SQL Server Query Plan
un momento por favor

Whyly


We made a bad decision, and that bad decision was to to try to convert every column value to some new time zone, and then compare it to a value that we could have very easily computed once on the fly and compared to the column.

DECLARE @d datetime = '20131201';

SELECT    
    COUNT_BIG(*) AS records
FROM dbo.Comments AS c
WHERE c.CreationDate >= DATEADD(HOUR, 1, @d) AT TIME ZONE 'UTC-11'
OPTION(RECOMPILE);
GO

When we make a good decision, the query runs in much shorter order.

SQL Server Query Plan
ooh la la

One may even accuse us of cheating time itself when looking at how much more quickly this runs without the aid of parallelism.

And that’s really the message in all of these posts, isn’t it? It’s not about left side vs. right side of the comparison. It’s about what we decide to make an expression out of.

When it’s data — the stuff that we physically store — converting that turns into a circus.

When it’s a value — something that we express once via a parameter or variable or some line of code — it’s far less of a burden.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Troubleshooting RESOURCE_SEMAPHORE_QUERY_COMPILE Waits In SQL Server

Unfortunate


RESOURCE_SEMAPHORE_QUERY_COMPILE happens, in a nutshell, when SQL Server has allocated all the memory it’s willing to give out to compile query plans of a certain size and, throttles itself by making other queries wait to compile. For more details, head over here.

Now, this of course gets easier if you’re using Query Store. You can get heaps of information about query compilation from query_store_query. For everyone else, you’re left dipping into the plan cache to try to find queries with “high” compile memory. That can be hit or miss, of course.

But if it’s something you really find yourself needing to track down, here’s one way to do it:

WITH XMLNAMESPACES('http://schemas.microsoft.com/sqlserver/2004/07/showplan' AS p)
SELECT TOP (10) 
    x.compile_time_ms,
    x.compile_cpu_ms,
    x.compile_memory_kb,
    x.max_compile_memory_kb,
    x.is_memory_exceeded,
    x.query_plan
FROM
(
    SELECT
        c.x.value('@CompileTime', 'BIGINT') AS compile_time_ms,
        c.x.value('@CompileCPU', 'BIGINT') AS compile_cpu_ms,
        c.x.value('@CompileMemory', 'BIGINT') AS compile_memory_kb,
        c.x.value('(//p:OptimizerHardwareDependentProperties/@MaxCompileMemory)[1]', 'BIGINT') AS max_compile_memory_kb,
        c.x.exist('//p:StmtSimple/@StatementOptmEarlyAbortReason[.="MemoryLimitExceeded"]') AS is_memory_exceeded,
        deqp.query_plan
    FROM sys.dm_exec_cached_plans AS decp
    CROSS APPLY sys.dm_exec_query_plan(decp.plan_handle) AS deqp
    CROSS APPLY deqp.query_plan.nodes('/p:ShowPlanXML/p:BatchSequence/p:Batch/p:Statements/p:StmtSimple/p:QueryPlan') AS c(x)
    WHERE c.x.exist('@CompileMemory[. > 5120]') = 1
) AS x
ORDER BY x.compile_memory_kb DESC;

This query is filtering for plans with compile memory over 5MB. I set the bar pretty low there, but feel free to raise it up.

If you want to look at gateway info, and you’re on SQL Server 2016 or newer, you can use this DMV:

SELECT *
FROM sys.dm_exec_query_optimizer_memory_gateways AS deqomg
WHERE deqomg.pool_id > 1;

Scoping It Out


It only makes sense to run that query if you’re hitting RESOURCE_SEMAPHORE_QUERY_COMPILE wait with some frequency.

If you are, you just may be lucky enough to find the culprit, if your plan cache has been around long enough.

Thanks for reading!

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.
Announcing The Darling Data Vantablack Friday Sale!

A Word From Our Sponsors


First, a huge thank you to everyone who has bought my training so far. You all are incredible, and I owe all of you a drink.

Your support means a lot to me, and allows me to do nice stuff for other people, like give training away for free.

So far, I’ve donated $45k (!!!) worth of training to folks in need, no questions asked.

Next year, I’d like to keep doing the same thing. I’d also like to produce a whole lot more training to add value to the money you spend. In order to do that, I need to take time off from consulting, which isn’t easy to do. I’m not crying poor, but saying no to work for chunks of time isn’t easy for a one-person party.

I’m hoping that I can make enough in training bucks to make that possible.

Because this sale is extra sale-y, I’ve decided to name it after the blackest black known to man.

Going Further


If this is the kind of SQL Server stuff you love learning about, you’ll love my training. Blog readers get 25% off the Everything Bundle — over 100 hours of performance tuning content. Need hands-on help? I offer consulting engagements from targeted investigations to ongoing retainers. Want a quick sanity check before committing to a full engagement? Schedule a call — no commitment required.