This Looks Bonkers!
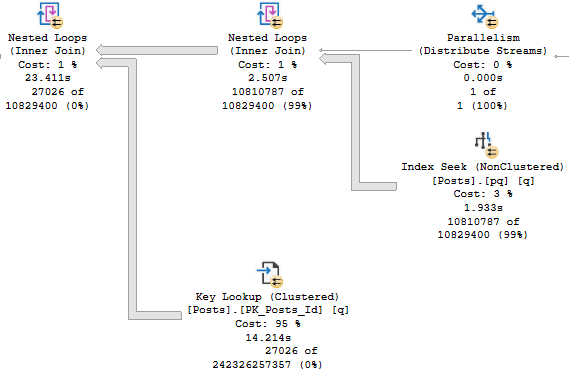
If you’ve ever read Kim Tripp’s wonderful post on tipping points, you’re probably staring at this Key Lookup and wondering why SQL Server would ever even consider it here. That’s like a 12 digit number. Twelve. That’s like a foreign phone number. That’s like what I spent on cheese plates last year.
I kid, I kid. Though I would not be opposed to that lifestyle.
The thing is, what that number represents is a little different from what we might first expect.
That number comes from multiplying these two numbers:
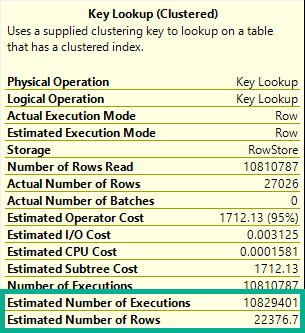
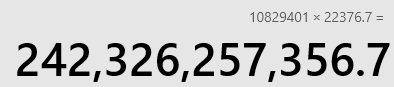
But Really
That’s how many rows we read. Which isn’t great, obviously. Look how long that thing runs for.
And it gets worse when we examine how rows were distributed on threads.
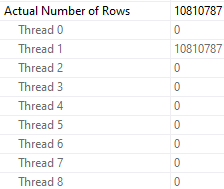
So for each of the ~11 million rows that comes out of the index seek of our nonclustered index, we:
- “Join” it to the clustered index based on the clustered index key column
- Evaluate if the OwnerUserId for that row is 22656
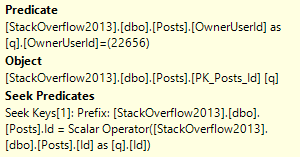
The 27,062 number is how many rows are produced after the filter is applied. That’s a bit more obvious when using Plan Explorer.
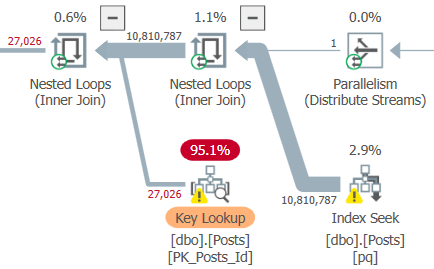
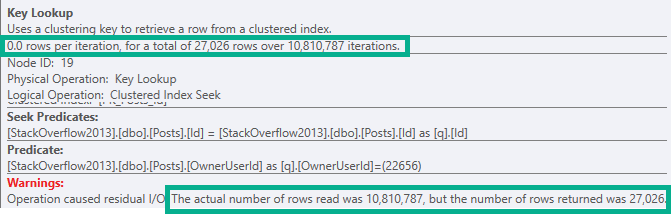
This lookup doesn’t produce any rows or columns, that’s why there are 0.0 rows per iteration.
It’s purely to filter data out, and it does that. Slowly.
Look, I’m not defending the choice, I’m just using it to teach you something.
How Can You Fix It?
In this case, it would probably be worth adding the OwnerUserId column to the nonclustered index we already have on Posts that’s being used in this query, assuming that it wouldn’t be disruptive to other queries. If that’s not possible, then a new index that satisfies the entire where clause would be a good solution.
If neither of those is palatable, then you might try some exotic rewrites to isolate those rows, correlate on a different column, or “persuade” the optimize to stop pursuing nested loops joins.
Thanks for reading!
Going Further
If this is the kind of SQL Server stuff you love learning about: these days I have AI do the annoying stuff for me. My new video course teaches you to work the same way, and I teach whole teams in a one-day workshop. Someone still has to know enough SQL Server to keep the robots in check, and that’s what my training is for.
One thought on “Interpreting Key Lookups In SQL Server Query Plans Can Be Tricky”
Comments are closed.